Frontier ECI and the benchmark scores behind it
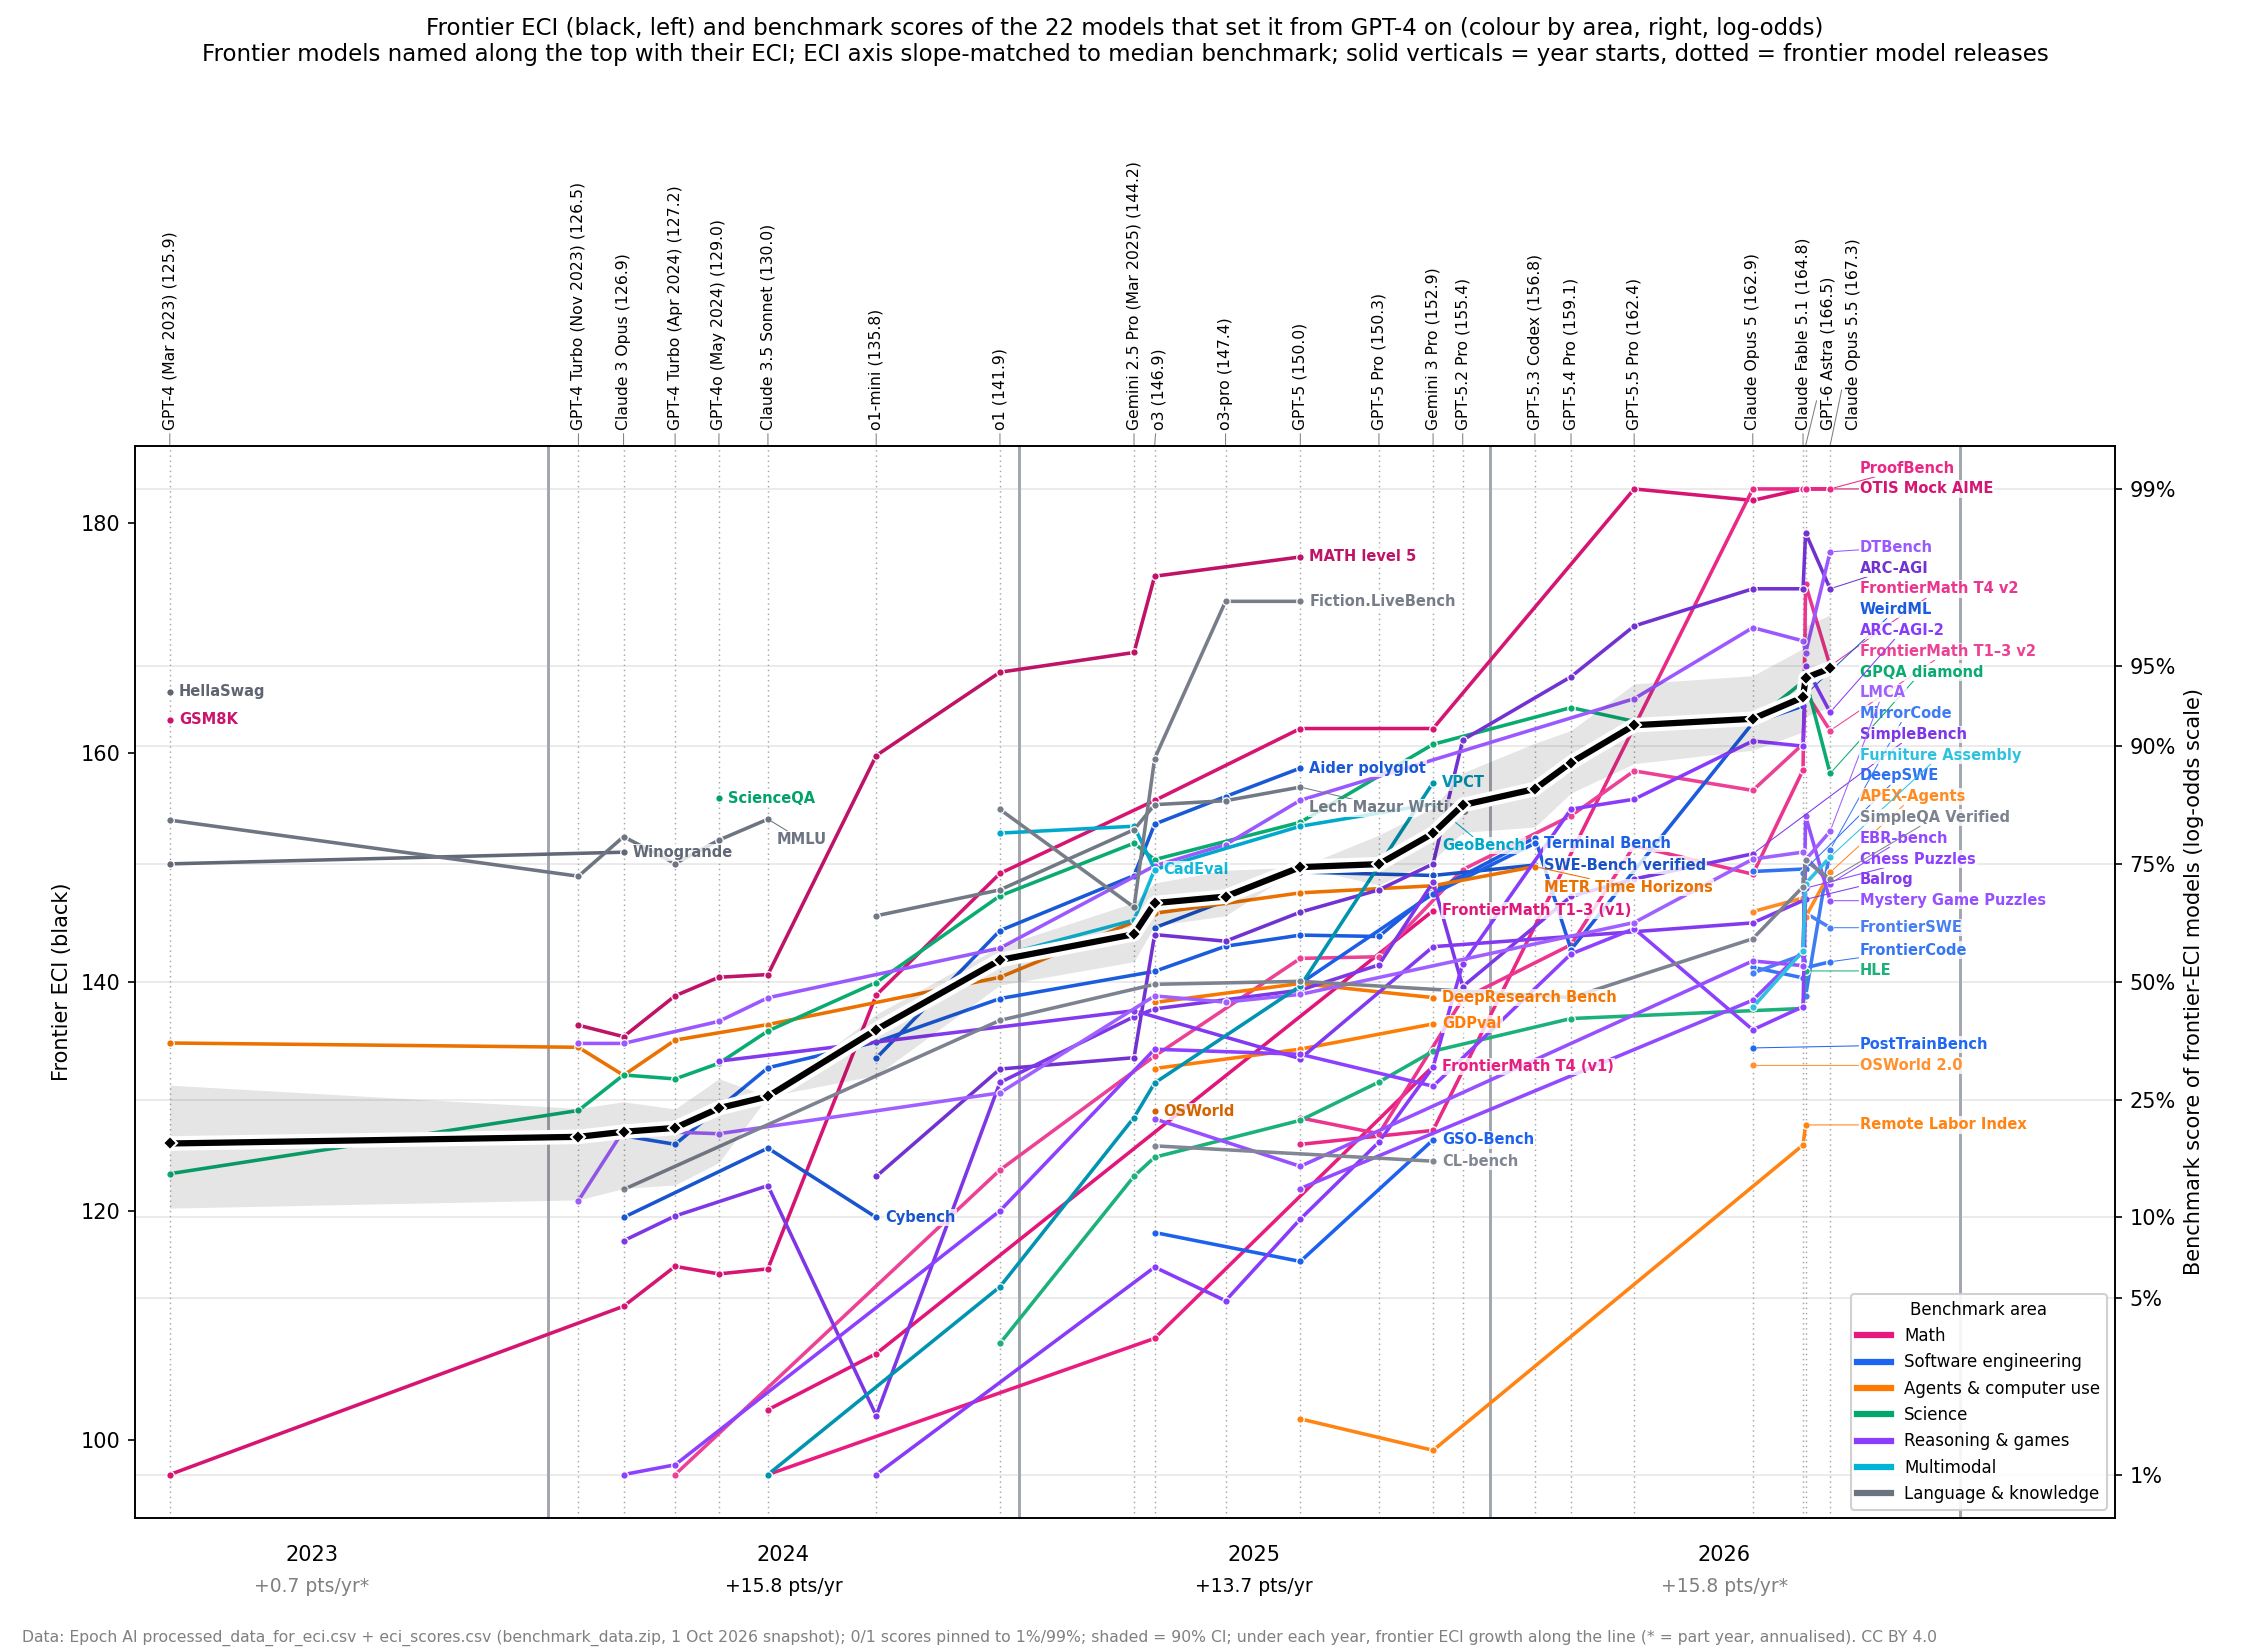
The interactive chart could not load here, so this is the static version.
Benchmarks in the ECI fit:
Data: Epoch AI's own ECI fit input (processed_data_for_eci.csv) and published ECI scores (eci_scores.csv) from benchmark_data.zip, snapshot of 1 Oct 2026, shown from GPT-4 (14 Mar 2023) onward. Each model's lab is the first organisation Epoch lists for it; labs with at least five models in the period can be chosen above. Every score is already floor- and ceiling-adjusted: (raw − random-guess baseline) ÷ (attainable ceiling − baseline), clipped to [0, 1], taking the best version within each model group. Frontier ECI is the running maximum by release date, over all labs or over the chosen lab's models; where several models share a date only the highest counts. ECIs come from Epoch's joint fit over every lab's models (including the few pre-GPT-4 models not shown), so a lab's frontier is directly comparable with the overall one.
Areas follow the primary domain tag on Epoch's ECI page, grouped into seven: Math; Software engineering (includes Cybench); Agents & computer use; Science; Reasoning & games (conceptual reasoning plus games); Multimodal; Language & knowledge (language understanding, world knowledge, long context, writing). Seven benchmarks have no tag there and were assigned by hand: METR Time Horizons, DeepResearch Bench (agents), LMCA (reasoning), Lech Mazur Writing (language), GeoBench (multimodal), and the two FrontierMath v1 sets (math).
Solid vertical lines mark the start of each year; dotted lines mark the release of each frontier model. The frontier line joins successive records with straight lines, and the figure under each year is the rise along that line between 1 January and 31 December, in ECI points; a starred figure covers only part of the year (from the first record, or to the latest) and is annualised. The slope-matched ECI axis is scaled so a benchmark with the median fitted slope ( logits per ECI point) runs parallel to the ECI line; steeper benchmarks climb faster than it.
Refitting: untick benchmarks under “Benchmarks in the ECI fit” and ECI is re-estimated in your browser on the rest, using Epoch's model and objective (open-source eci-public): score = sigmoid(slope × (capability − difficulty)), least squares with the same L2 penalty, scaled so Claude 3.5 Sonnet = 130 and GPT-5 = 150. With all benchmarks ticked the chart shows Epoch's published numbers; this solver reproduces them to within 0.06 points. Refits have no intervals, since Epoch's come from 500 bootstrap refits. Unticked benchmarks stay on the chart as faded dotted lines, and Epoch's published frontier is drawn faded behind the refitted one. The link records the lab and any dropped benchmarks, so a refit can be shared. Scores of exactly 0 or 1 are pinned to 1% and 99%. Data CC BY 4.0, Epoch AI.
See also the nonparametric version: each benchmark gets a free monotone curve instead of a sigmoid, with diagnostic plots of every curve.