- Q: How much has discovery accelerated?
-
LLMs have shown the ability to make novel discoveries across many domains. How much has this affected the aggregate discovery rate? In this graph I plot all the data sources I can find, and make some very loose observations:
- Discovery of cyber vulnerabilities has accelerated sharply.
- Discovery of math results has accelerated somewhat. However this is harder to objectively measure.
- Discovery of optimizations has not shown a dramatic acceleration.
These conclusions are based only only public discoveries, it is quite plausible that AI labs are making discoveries internally that they are not disclosing (earlier discussion).
- I also make two other more tentative observations:
-
- Many LLM-assisted discoveries did not seem to rely on domain expertise.
- The expenditure on LLM-assisted discoveries is important but difficult to estimate. Many announcements report relatively low inference-time expenditure for individual discoveries (relative to human expenditure), but they often don’t discuss expenditure on training, and inference expenditure which did not yield a discovery.
- Thanks.
- Thanks especially to Greg Burnham for extremely helpful comments, and who is graciously taking responsibility for all errors in this post.
Overview
- We are just looking for slope changes.
-
AI-assisted discoveries are often announced, but their significance is hard to assess. Here I will look for slope changes in various metrics of discovery to see if we can detect an acceleration. For concreteness, I will highlight January 2026 as a potential breakpoint at which the effects of AI might become observable. Some data sources record whether a discovery was AI-assisted or AI-contributed, but our primary focus is overall acceleration.
I will use the word “discovery” to refer to any advance in the state of public knowledge or ability. A new invention, or rewriting an algorithm to make it more efficient, would be a “discovery.”
- Note on the data.
- The analysis below plots about 20 different time series of discoveries across different problems. The analysis was written by agents. I have done my best to audit the results but likely some mistakes remain. The source material is in this repository, and it is set up so I can keep updating them over time.
- Discovery of vulnerabilities: sharp acceleration.
-
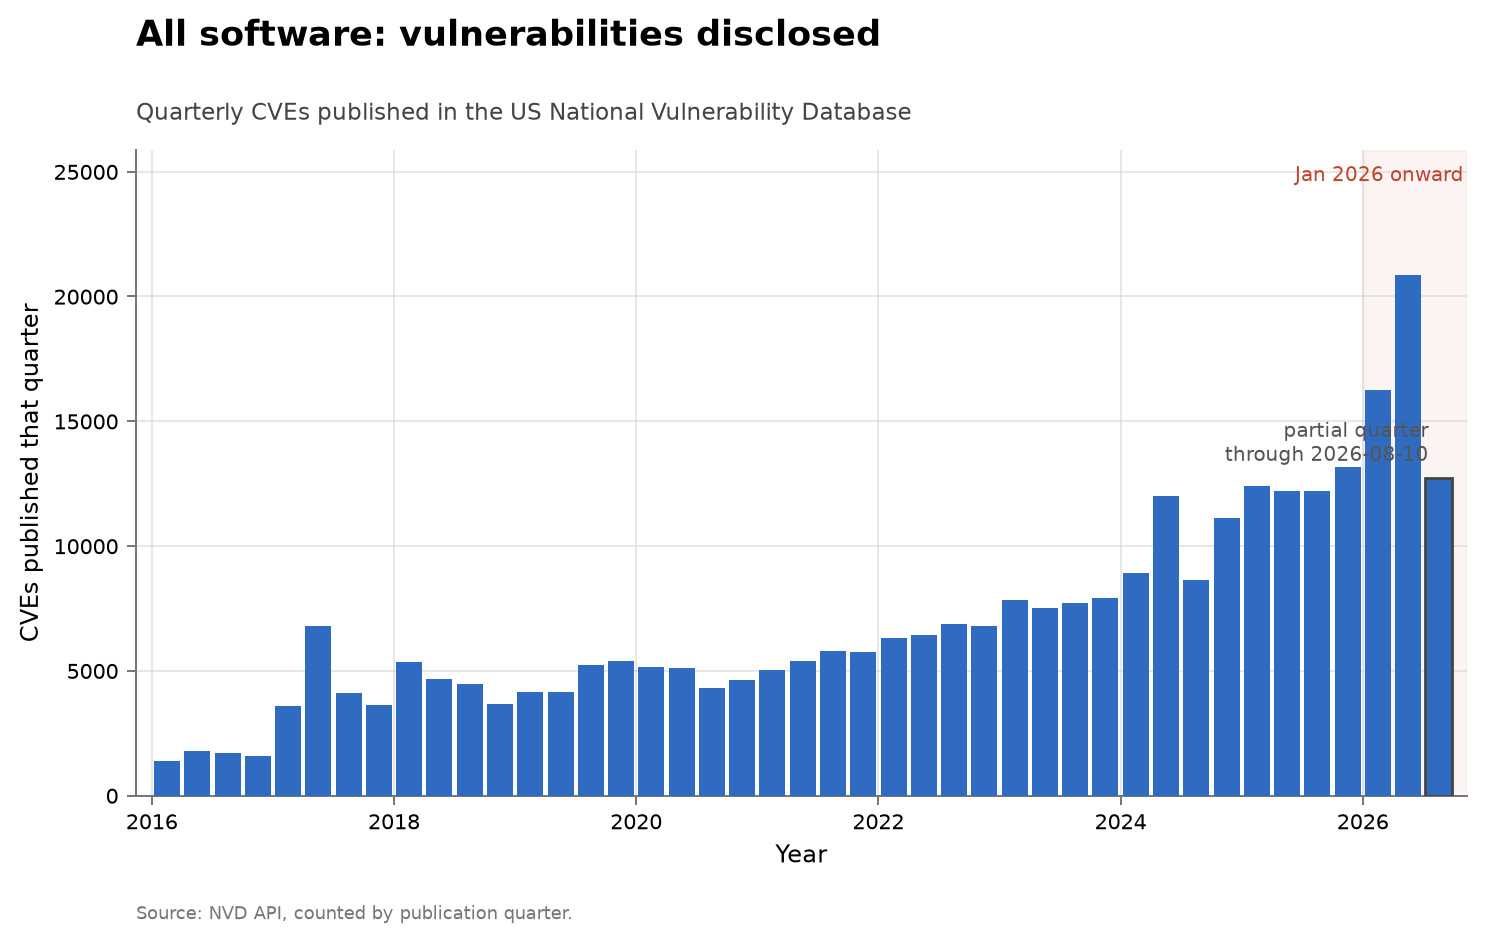
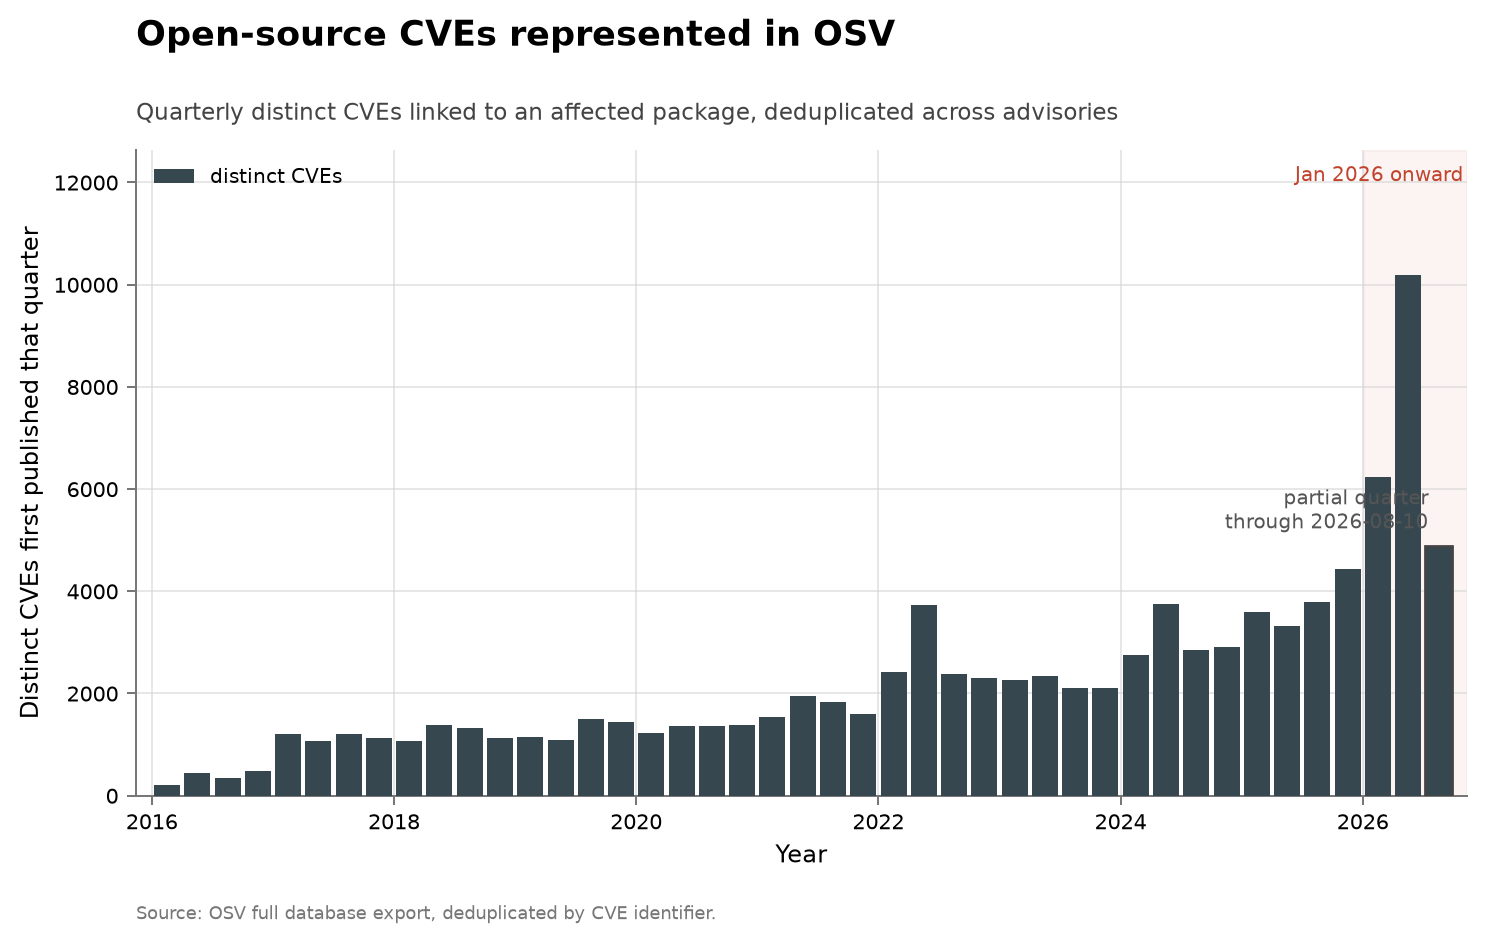
The rate of vulnerabilities reported across many projects has dramatically accelerated in 2026 compared with 2025, both for specific projects (cURL, OpenSSL, and Firefox) and for aggregate vulnerability databases (the US NVD, and OSV). The growth in aggregate vulnerabilities is roughly concurrent, and similar magnitude, to growth in AI-identified discoveries, implying they’re mostly incremental. Some of the data sources break give ratings of severity: in general higher-severity categories show lower acceleration, but there is still acceleration.
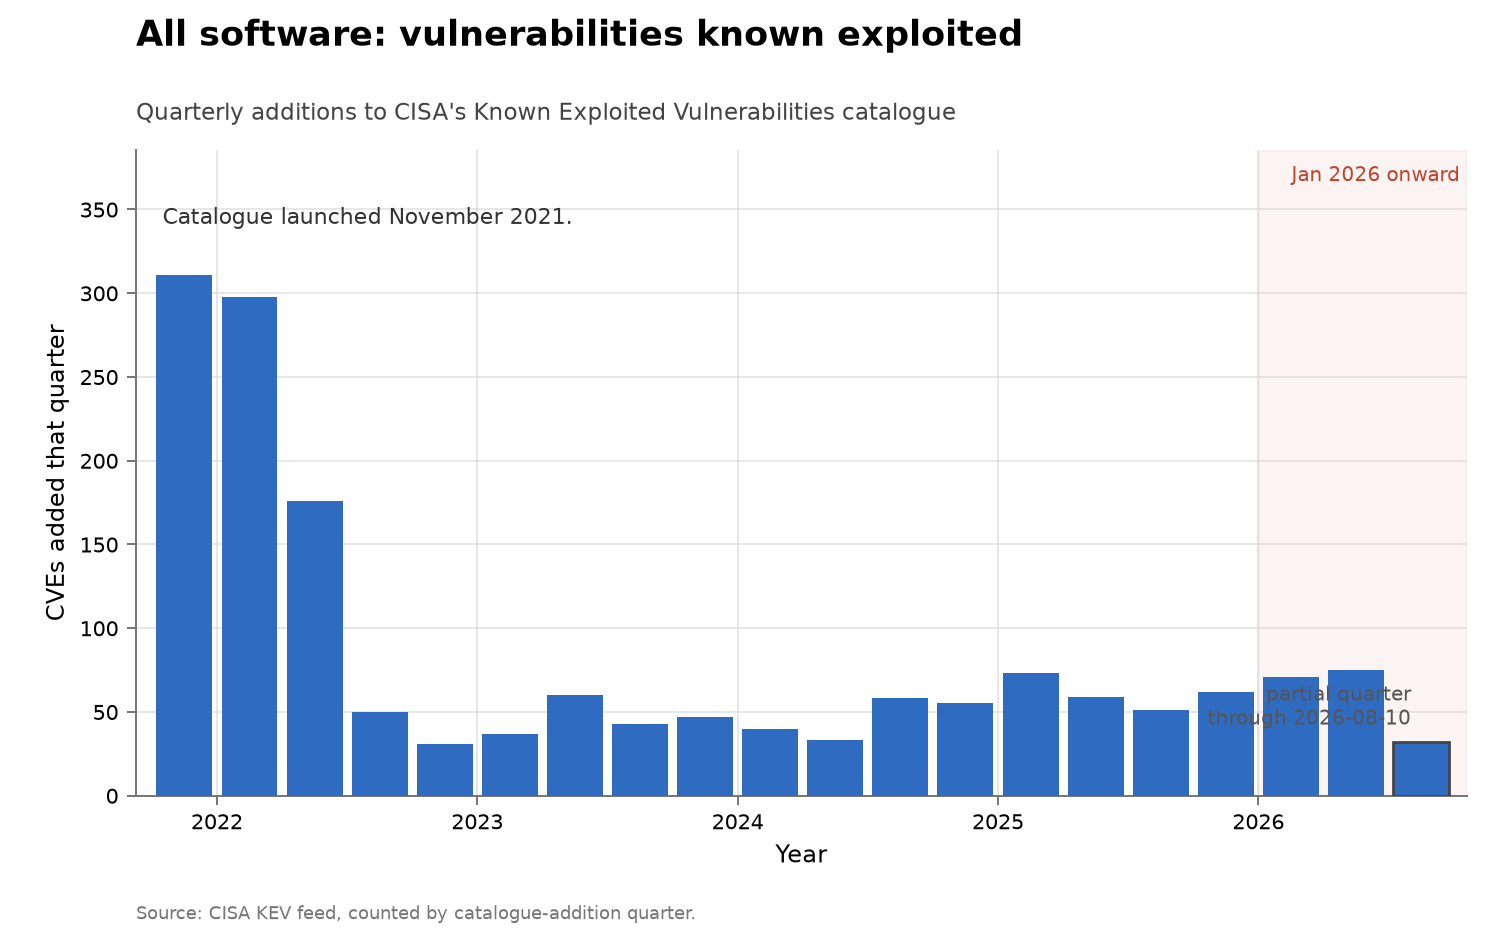
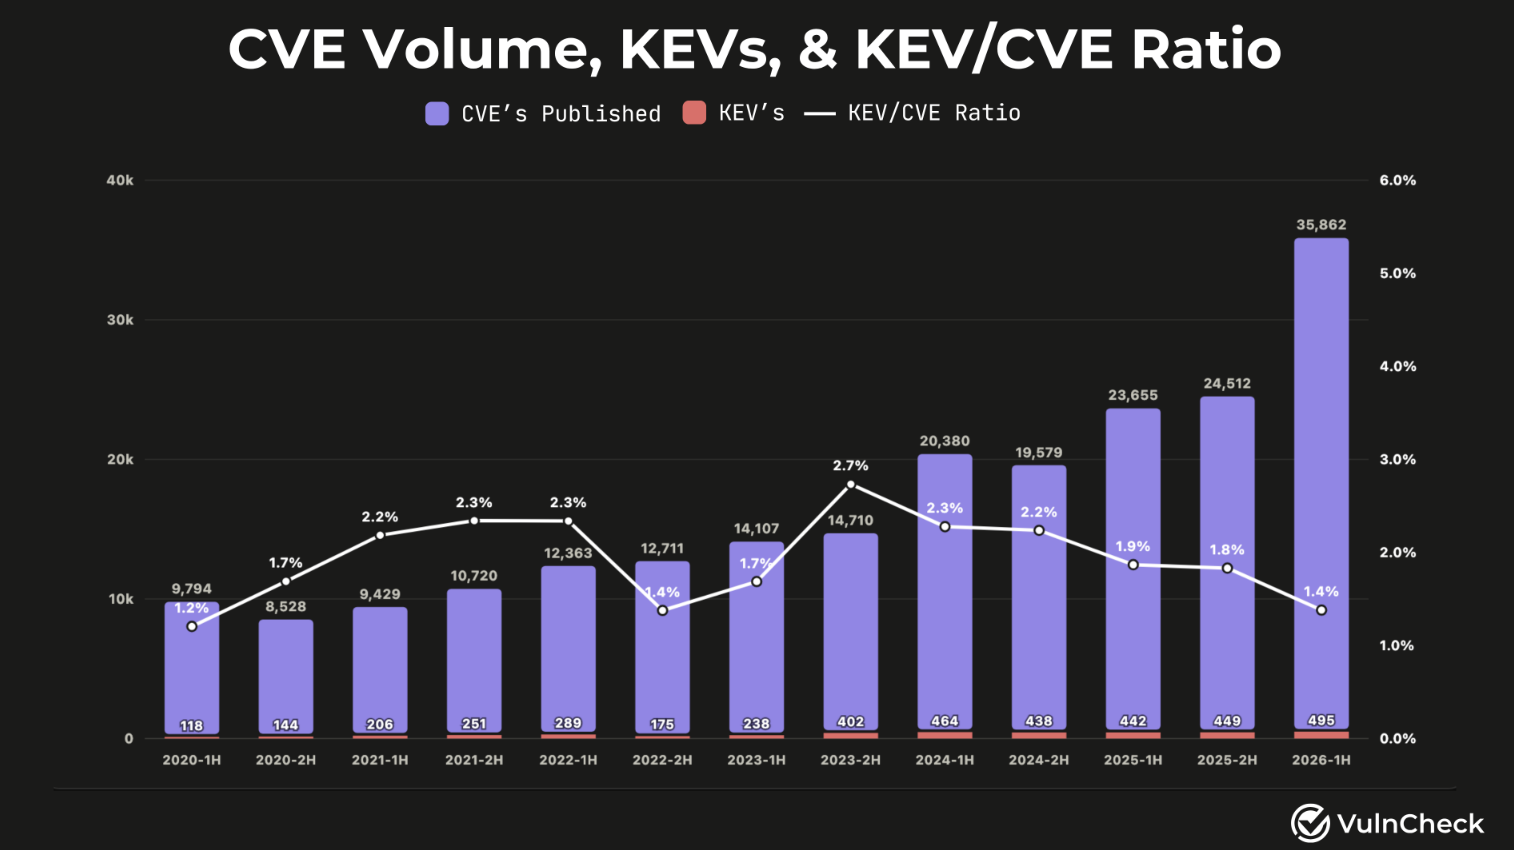
It is notable that databases tracking exploited vulnerabilities (CISA and Vulncheck CEVs) show significantly lower year-over-year growth than the databases of known vulnerabilities.
- Discovery in mathematics: likely acceleration, but it’s hard to benchmark.
-
AI is clearly contributing to more problems being solved, but quantifying the magnitude is difficult.1
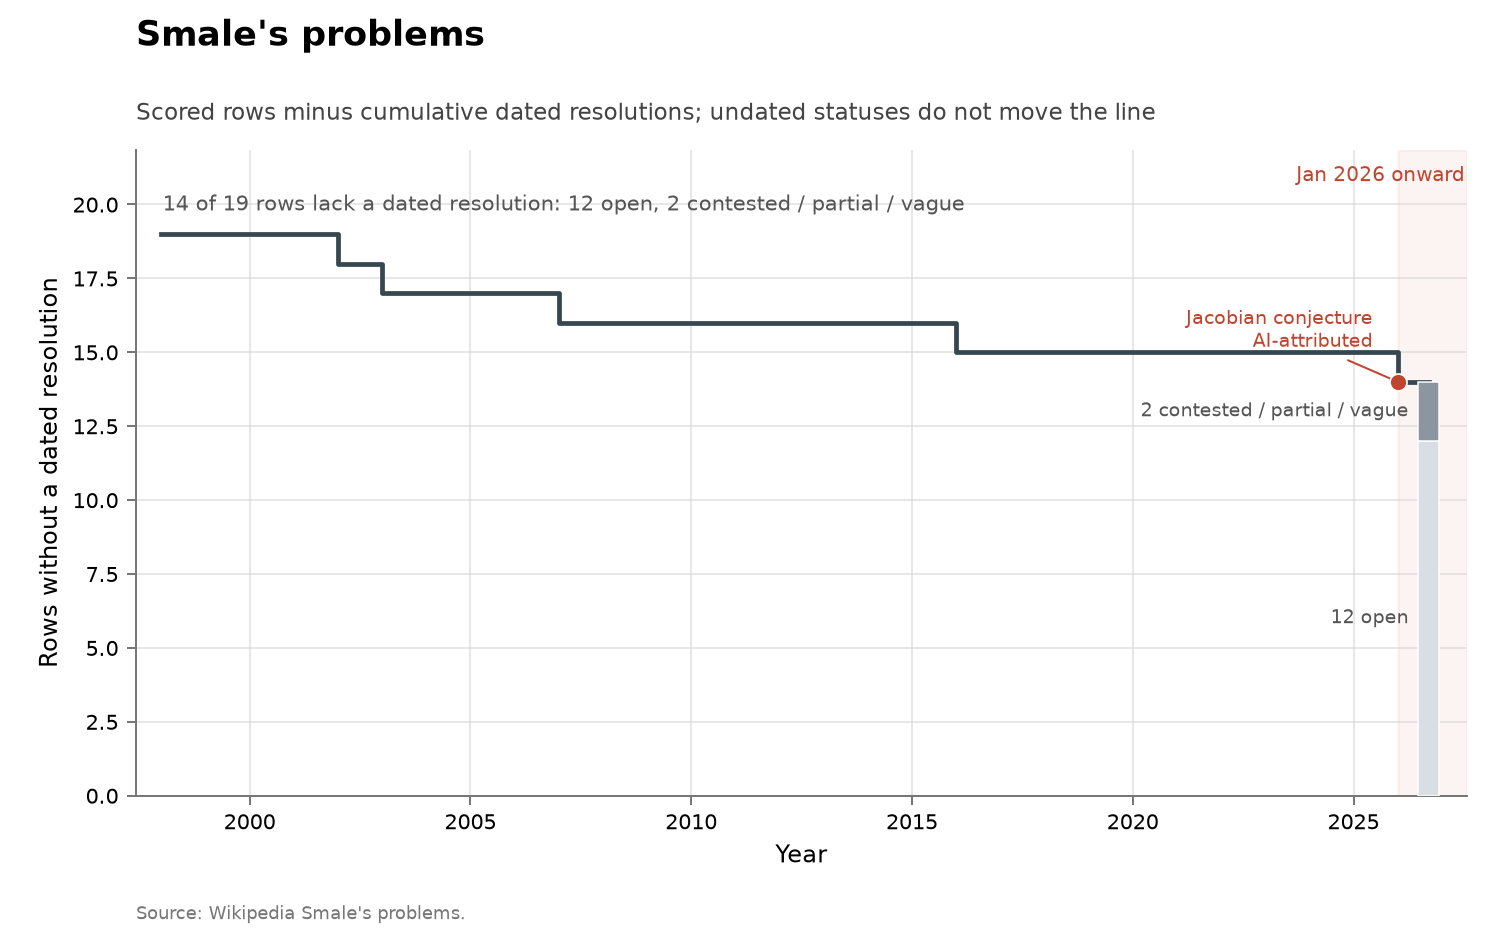
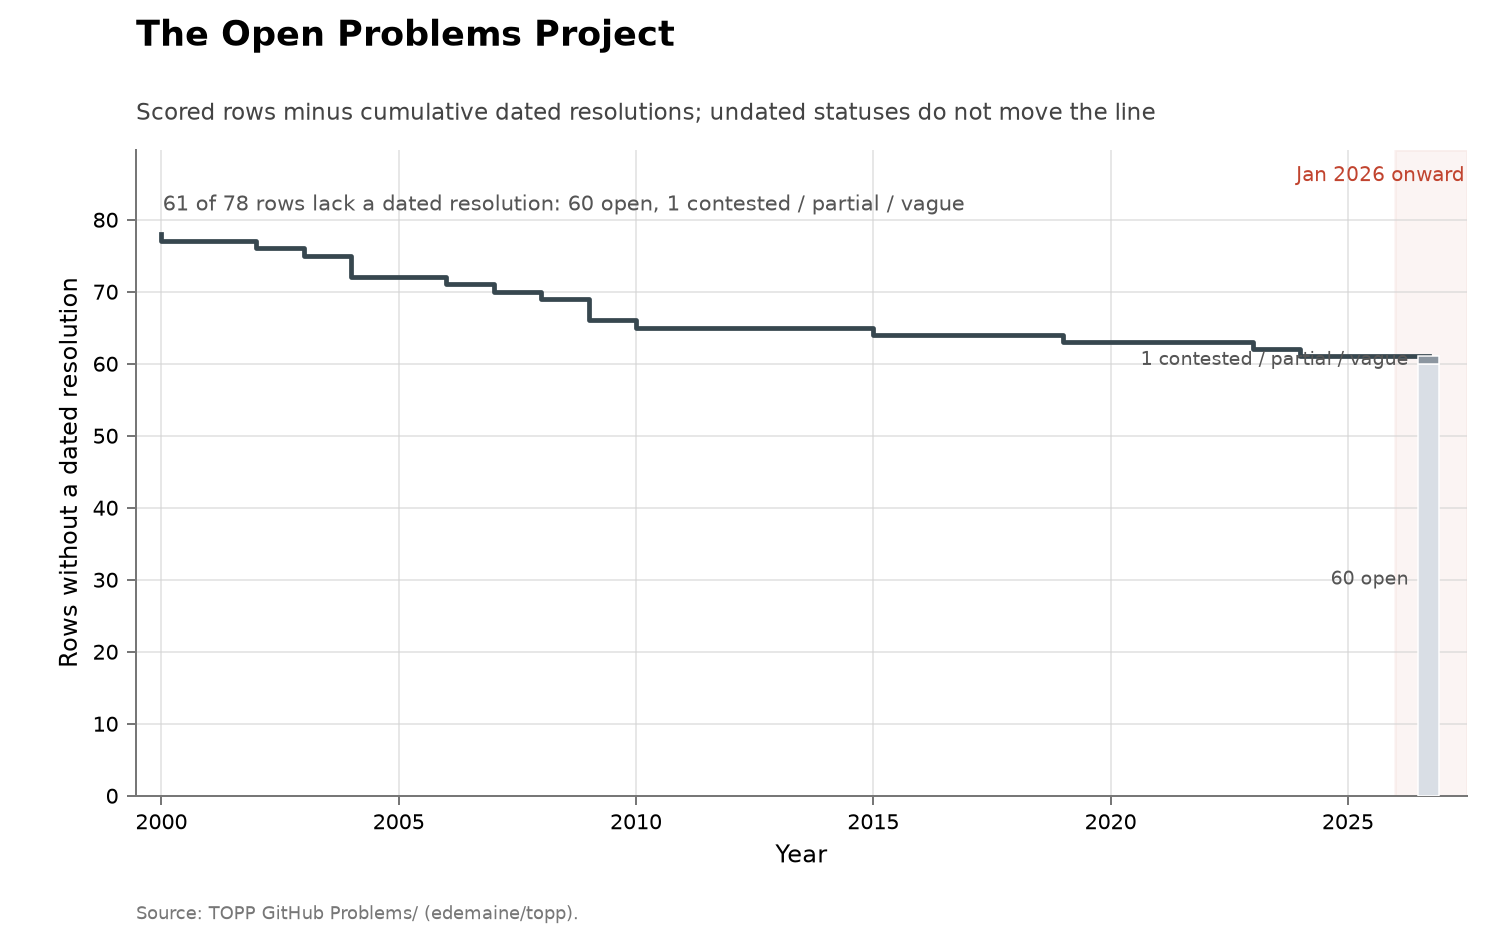
We can measure progress in mathematics by the rate of solving open problems from pre-existing lists: Hilbert, Millennium, Smale, and The Open Problems Project. One problem from these lists was solved with AI in 2026: the Jacobian conjecture, from Smale’s list. This is some evidence of acceleration, but it is very weak.
The Erdős list contains many more problems, but they vary widely in significance, and it is challenging to construct a historical time series of solutions. Again, there is some evidence of acceleration, but it is weak.
Another strategy for quantifying mathematical progress would be to look at tightening of bounds: sphere-packing, analytic number theory exponents, combinatorics constants. I collected some data on these in the repo but don’t feel I understand them well enough to draw any conclusions about velocity.
- Discovery of optimizations: no clear acceleration.
-
I collected historical time series for algorithmic efficiency across five problems (CIFAR-10, Hutter compression, mixed-integer programming, nanoGPT, and Stockfish, matrix multiplication exponent), which have relatively dense histories of discoveries.
Two of these series include LLM-driven contributions, but none show a clear change in slope, comparable to the changes in vulnerability or mathematical discovery. Thus the record of overall algorithmic optimization does not yet show an appreciable acceleration.
This was somewhat surprising to me. There has been a lot of recent excitement about LLM-driven optimization. In January of 2026 Yuksekgonul et al. (2026) reported advancing the frontier on 5 optimization problems (“every problem we attempted”) with a simple model and trivial expenditure on inference-time compute. I would have expected this technology to have led to significant acceleration in overall progress and it’s somewhat of a puzzle why we have not seen this.
- Why is AI accelerating some domains more than others?
-
I think this is the most interesting question in the world right now, and understanding the answer would give substantial insight into the imminence of RSI.
Some candidates:
- Variation in inference expenditure. The disproportionate growth in discovery of vulnerabilities could be simply due to disproportionate growth in inference expenditure on discovering vulnerabilities.2
- Variation in training expenditure. The same point as above could apply to training expenditure, e.g. if labs spend a lot on training models to discover vulnerabilities.
- Variation in difficulty for LLMs. Some domains might be more difficult for LLMs to navigate, relative to humans. This could have a few possible reasons, e.g. variation in cost to verify, variation in convexity of the discovery landscape.
- Variation in disclosure. As mentioned above, we might observe less progress in some domains in part because progress is being kept confidential. This seems plausible for AI-related algorithmic progress.
- Variation in data quality. The varation in progress might be partly an artefact of our imperfect data, e.g. cyber discoveries are very closely monitored with authoritative up-to-date databases, while progress in math and optimization is less easy to track, and so might show acceleration with a lag.
I hope to write a followup post going through these theories in more detail, and relating these facts to apple-picking and other theories of AI discovery.
- Many discoveries claim to have been made without expert prompting.
-
On the surface many discoveries have been made by LLMs prompted in generic ways, which did not seem to encode problem-specific expertise. However this can hide expertise used in choosing problems, in training, and in verifying solutions. Here I just give quotes, and generally leave interpretation for another time.
OpenAI’s unit-distance result:
“The proof came from a new general-purpose reasoning model, rather than from a system trained specifically for mathematics, scaffolded to search through proof strategies, or targeted at the unit distance problem in particular. As part of a broader effort to test whether advanced models can contribute to frontier research, we evaluated it on a collection of Erdős problems. In this case, it produced a proof resolving the open problem.”
“Jarred Sumner, an Anthropic staff member (and non-mathematician), prompted Claude to “take a real stab” at the hypothesis itself, leaving the mathematical choices from there up to the model.”
Google DeepMind’s AlphaEvolve paper says:
“in contrast to [traditional computational or theoretical methods performed by human experts], we have found that AlphaEvolve can be readily scaled up to study large classes of problems at a time, without requiring extensive expert supervision for each new problem.”
Mythos Preview’s announcement says:
“We then invoke Claude Code with Mythos Preview, and prompt it with a paragraph that essentially amounts to “Please find a security vulnerability in this program.” … Engineers at Anthropic with no formal security training have asked Mythos Preview to find remote code execution vulnerabilities overnight, and woken up the following morning to a complete, working exploit.”
Hiverge says, in announcing its new record on CIFAR-10:
“domain expertise is no longer a prerequisite for breakthrough results.”
- It is hard to tell the true cost of LLM discoveries.
-
We would like to know the average cost per discovery for autonomous LLM-produced discoveries, compared with human-produced discoveries.
There are many claims implying the average cost per AI discovery is much lower than the average cost per human discovery.
Many have . The average cost can be hard to interpret, but a simple assumption is that people are spending on LLM test-time compute until the marginal returns to expenditure are roughly equalized between humans and LLMs. In this case, a lower average cost implies a lower elasticity (the elasticity is the ratio of marginal to average returns).
- Acceleration might be occurring inside labs.
- It’s possible that the rate of discoveries is accelerating but we’re not observing it in public data. Concretely, it seems quite plausible that AI labs are making algorithmic efficiency discoveries at an increasing rate but not disclosing them. In addition, labs may be intentionally constraining the public ability of models to contribute to algorithmic discoveries.3
Discovery in Vulnerabilities
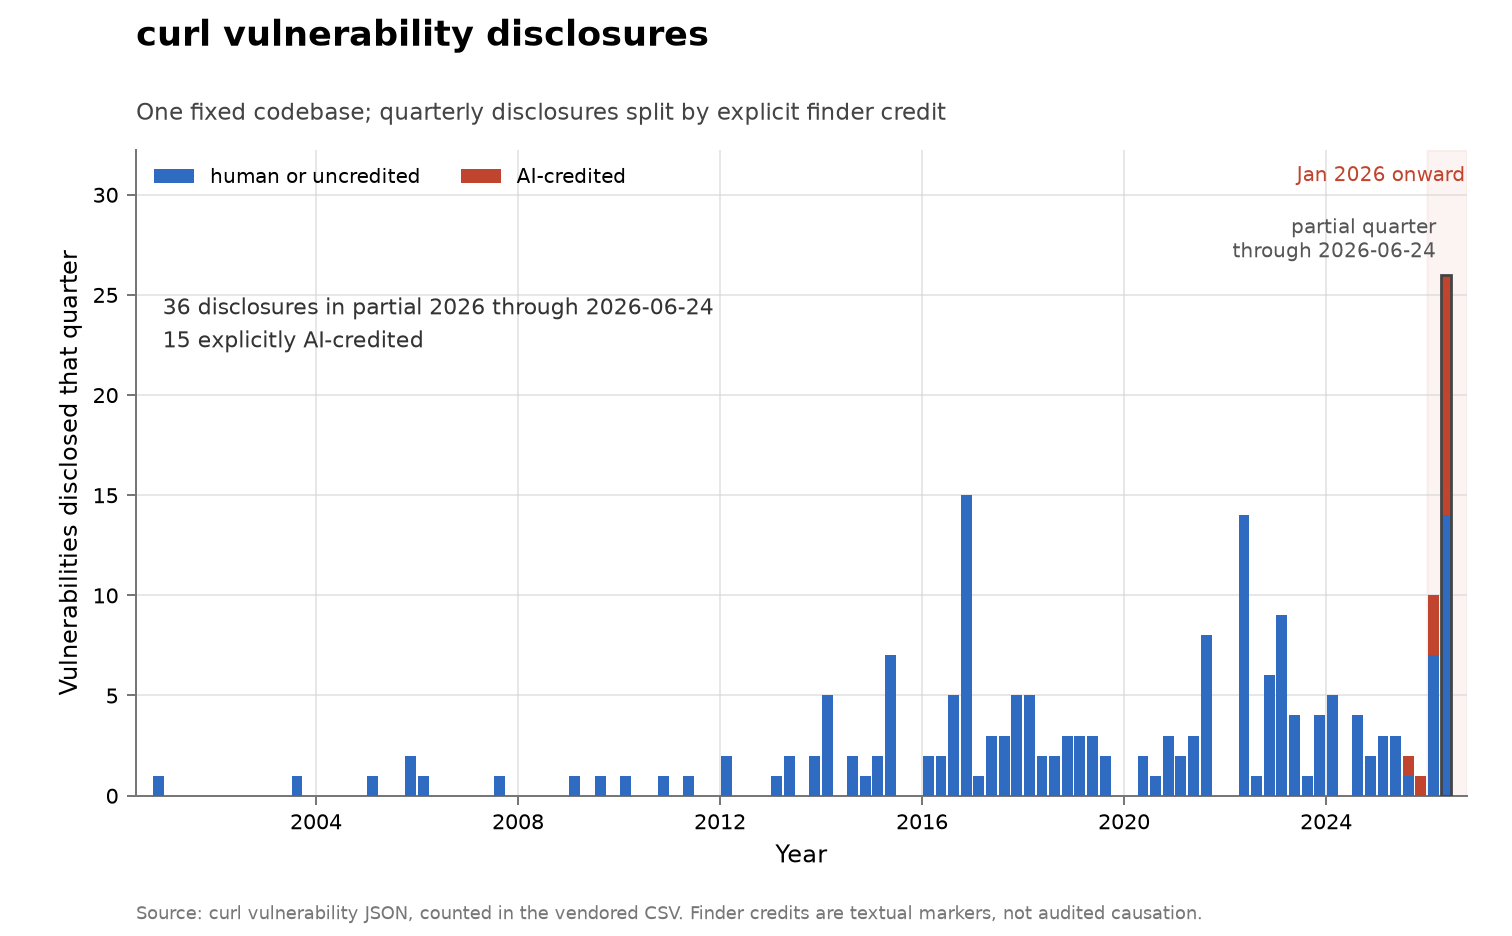
curl CVEs: dramatic acceleration
- cURL vulnerabilities grew from 9 in 2025 to 36 so far in 2026.
- Around half of the 2026 vulnerabilities are explicitly credited to AI.
- The overall severity mix has stayed constant between 2025 and 2026 (in fact, there is a slightly smaller share of “low severity”), but AI-credited vulnerabilities skew somewhat less severe than those not credited to AI.
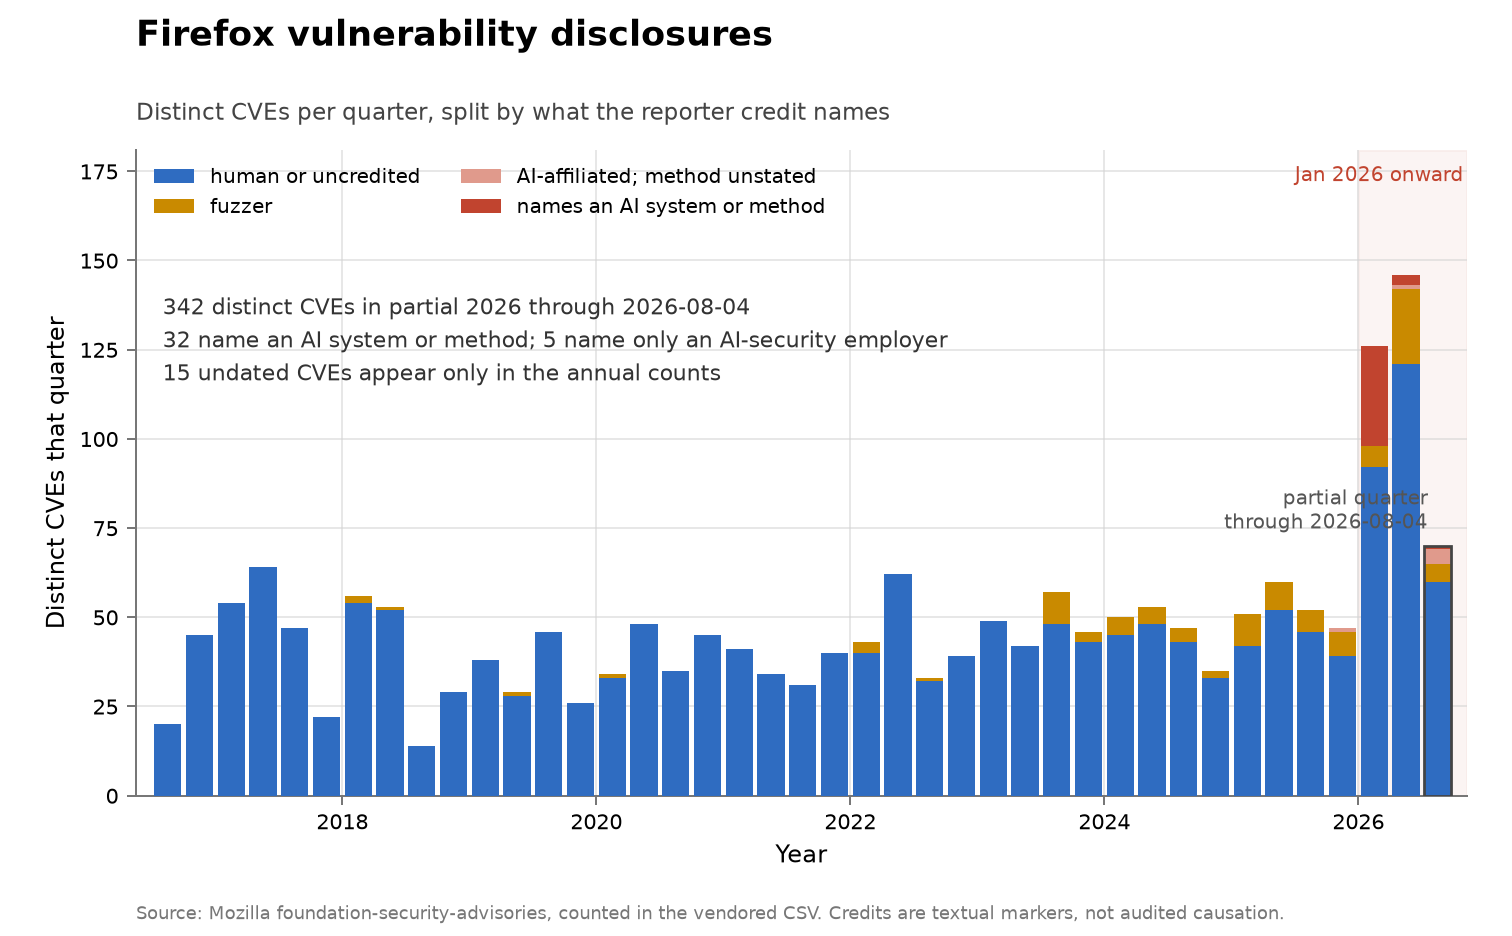
Firefox CVEs: dramatic acceleration
- Firefox CVEs (Common Vulnerabilities and Exposures) grew from 205 in 2025 to 342 so far in 2026.
- Only a small share explicitly name an AI system or method.
- Firefox endorse the seriousness of AI-found bugs and vulnerabilities in a March blog post.
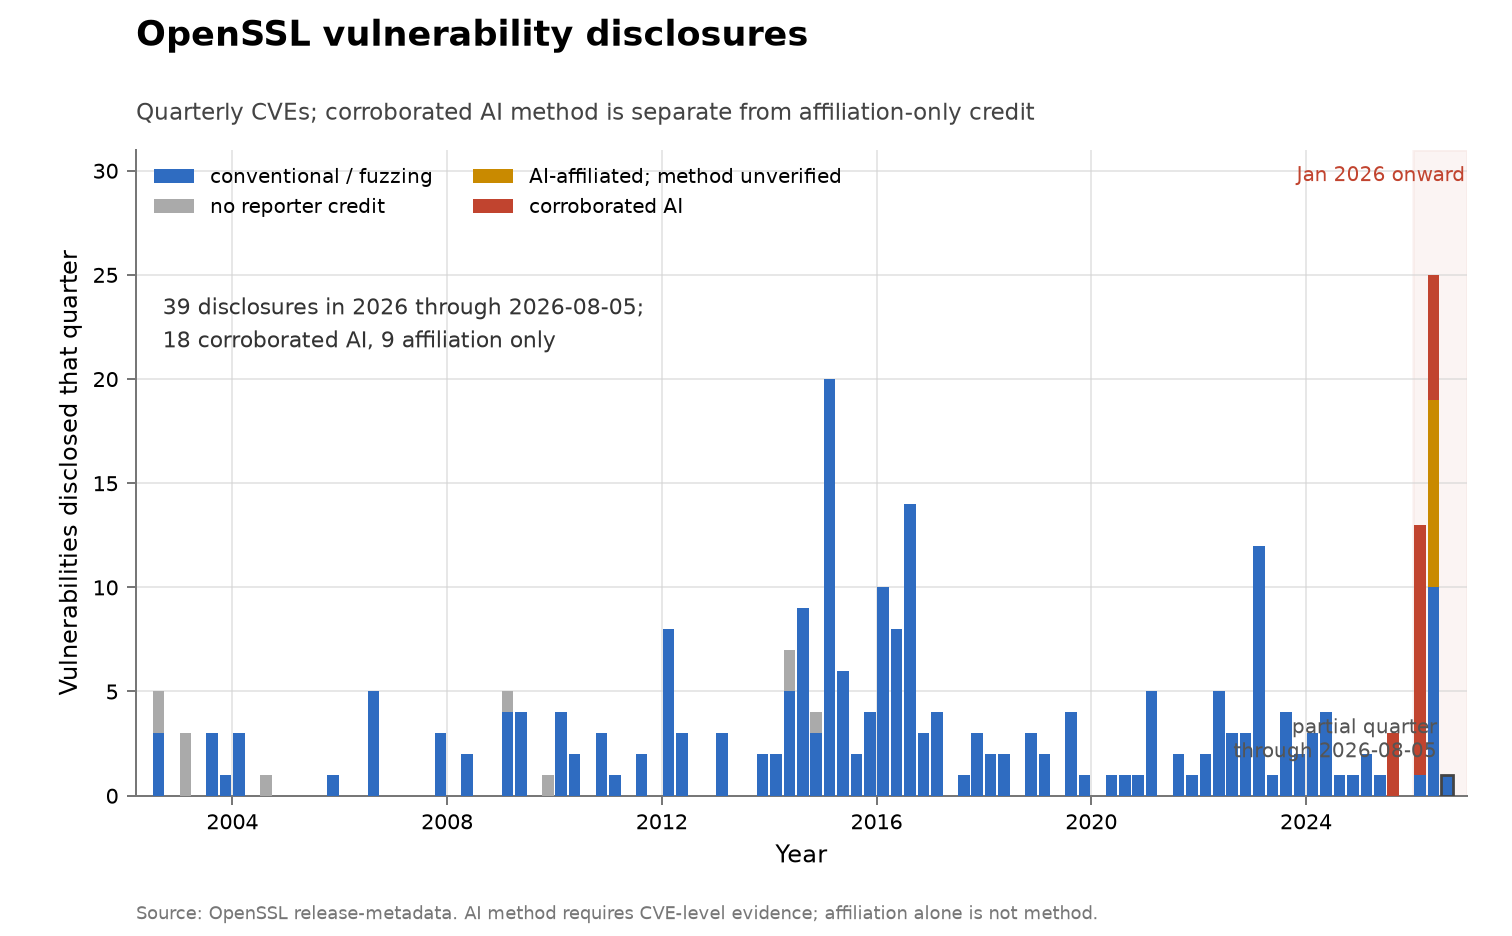
OpenSSL vulnerability disclosures: dramatic acceleration
- OpenSSL has shown a dramatic acceleration in vulnerabilities from 2025 to 2026.
- Around half of 2026’s vulnerabilities are explicitly AI-discovered, and another 1/4 are AI-affiliated.
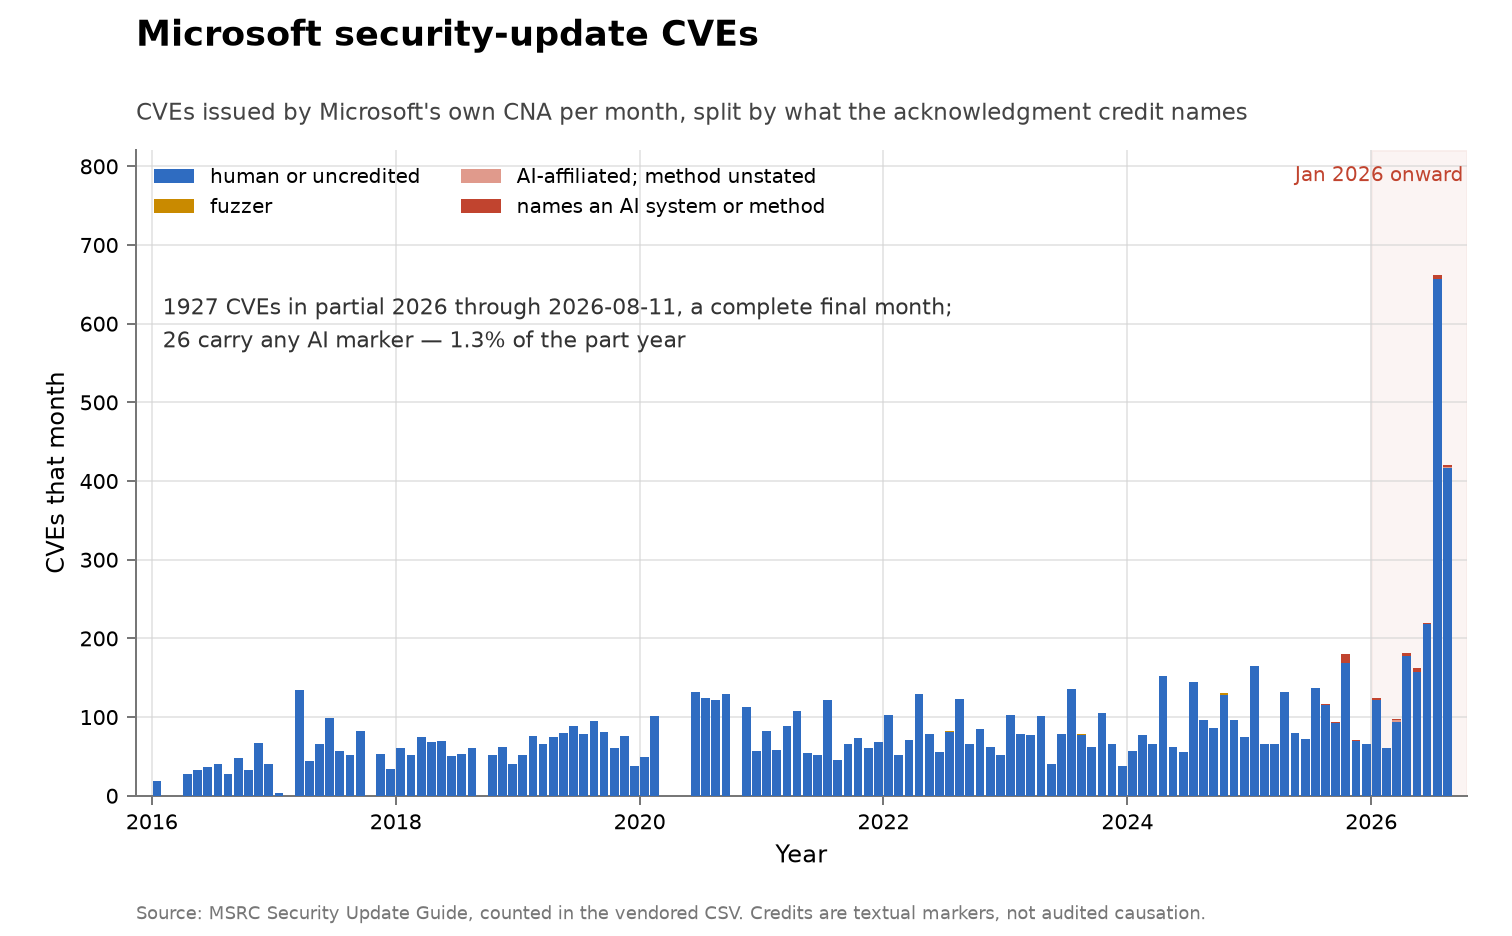
Microsoft security-update CVEs: dramatic acceleration
- Microsoft-issued CVEs grew from 1,243 in all of 2025 to 1,507 through July 2026, annualizing to about 2.1 times the 2025 rate.4
- Only 22 of the 2026 CVEs carry any AI marker, 1.5% of the total.
- CVEs are batched by Patch Tuesday and dated when fixed and disclosed, not when found.
US National Vulnerability Database CVEs: acceleration
- As of early August, the number of 2026 CVEs already equals the 2025 total.
Open-source CVEs: acceleration
- Google maintains an Open Source Vulnerability (OSV) database.
- As of early August, the number of OSVs already significantly exceeds the 2025 count.
CISA Known Exploited Vulnerabilities: small acceleration
- The Cybersecurity and Infrastructure Security Agency (CISA) maintains a list of Known Exploited Vulnerabilities (KEV), a subset of known vulnerabilities.
- As of early August, we appear to be on track to exceed 2025’s total, but the growth is clearly lower than CVEs.
- It’s important to note that the record of a vulnerability exploited can lag from its discovery.
Vulncheck Known Exploited Vulnerabilities: small acceleration
Vulncheck publishes statistics on exploitation, which casts a wider net than CISA.
The graph at right shows both CVEs (vulnerabilities discovered) and KEVs (vulnerabilities exploited).
Vulncheck say:
“While the first half of 2026 saw a 10% increase in KEVs compared to the prior six months, CVE volume grew at a much faster rate of 45%, resulting in a significant drop in the KEV-to-CVE ratio. Of course, exploitation often occurs months or even years after a vulnerability is disclosed, so it’s still too early to determine whether exploitation volumes will eventually follow the same growth trend as CVE issuance or level off at current rates. We’ll have to wait and see how publicly available Frontier AI Cyber models continue to progress over the next year.”
Discovery in Math Problems
Problems and time series
ArXiV submissions: dramatic acceleration
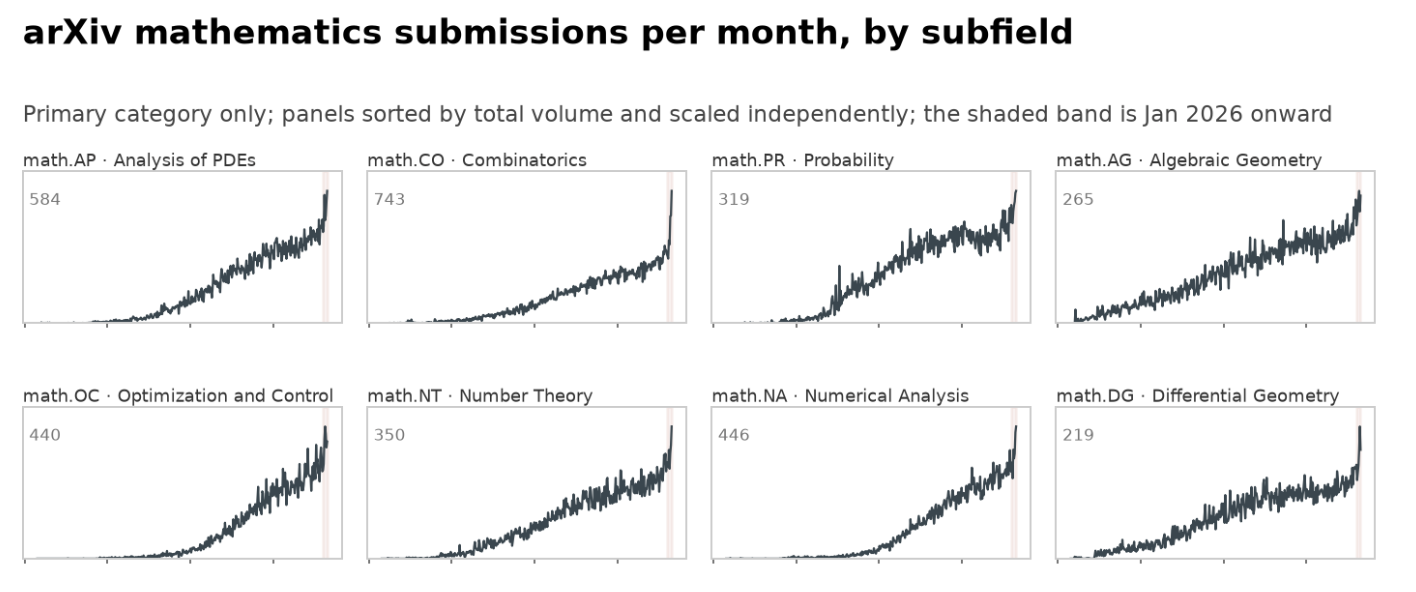
- Mathematics submissions to arXiv have dramatically accelerated, with big variations by subfield. E.g. combinatorics papers have roughly doubled over 8 months in 2026.
Erdős problems: dramatic acceleration
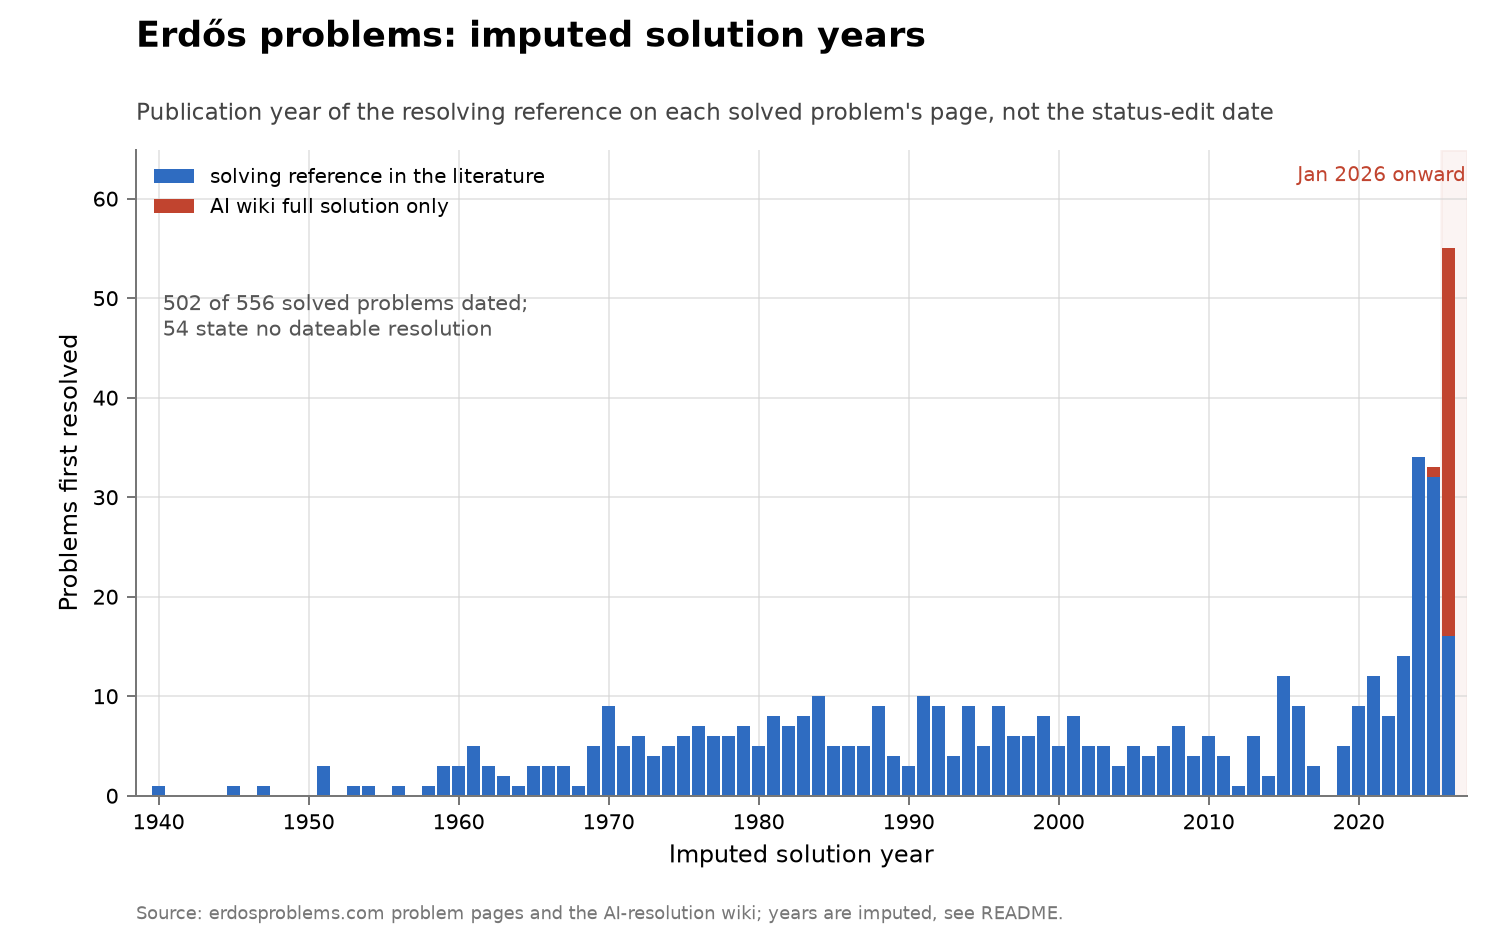
- Paul Erdős stated many unsolved problems or conjectures. Lists of problems and solutions are maintained at Thomas Bloom’s erdosproblems.com and Terence Tao’s Erdős Problem tracker.
- At right we show a crude time series which imputes solution date from the year of the paper cited in Bloom’s resolution wiki. This is done against Bloom’s warning,5 so for this reason should be taken as very weak evidence for acceleration pending a more thorough dating.
- The reconstructed time series shows an overall acceleration in 2024, and a further increase in 2026 associated with an explosion in AI-attributed solutions.
- I do not have a good explanation for the increase in solution rate in 2024. Many of the solutions appear in distinct arXiv papers, and it is unclear whether they were AI-accelerated.
- In April 2026 Thomas Bloom posted a list of top 10 ‘most important’ Erdős Problems. The list doesn’t lend itself well to quantifying progress, in part because some of the problems are combined, and because some problems are technically already resolved but included because they point to interesting areas. However it is notable that the list includes the unit distance conjecture, resolved shortly after the list was posted.
Hilbert’s problems: too sparse
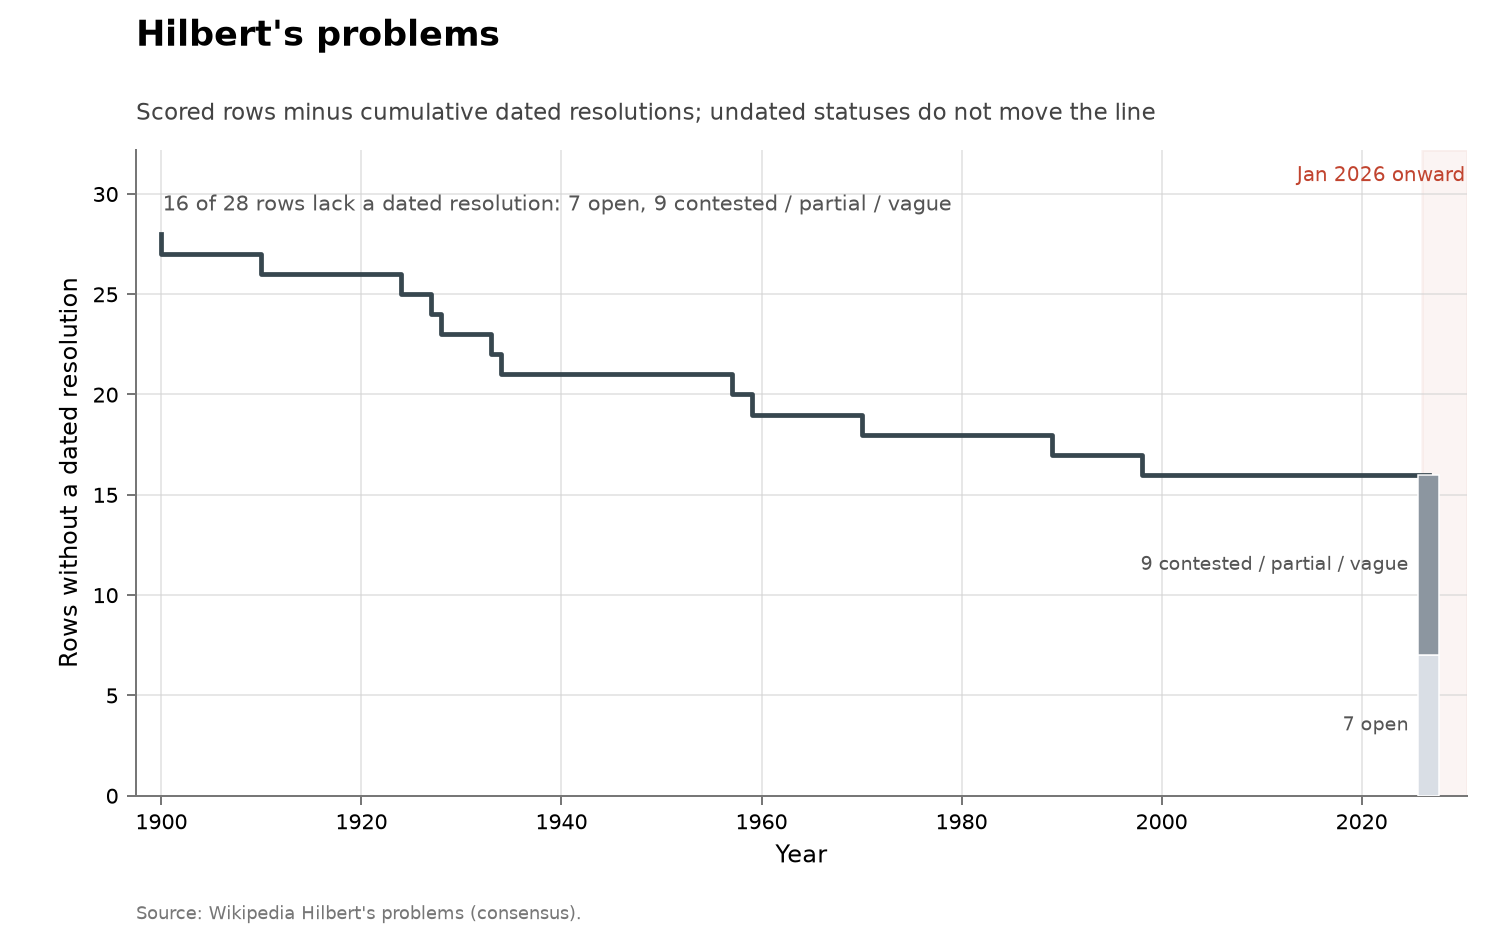
- Hilbert’s twenty-three problems were presented in 1900 (split into 28 rows to account for subquestions).
- Twelve rows have dated resolutions, ending with Hales’s computer-assisted sphere-packing proof in 1998; seven remain open and nine are disputed, partial, or vague. No solutions are AI-attributed.
Millennium Prize Problems: too sparse
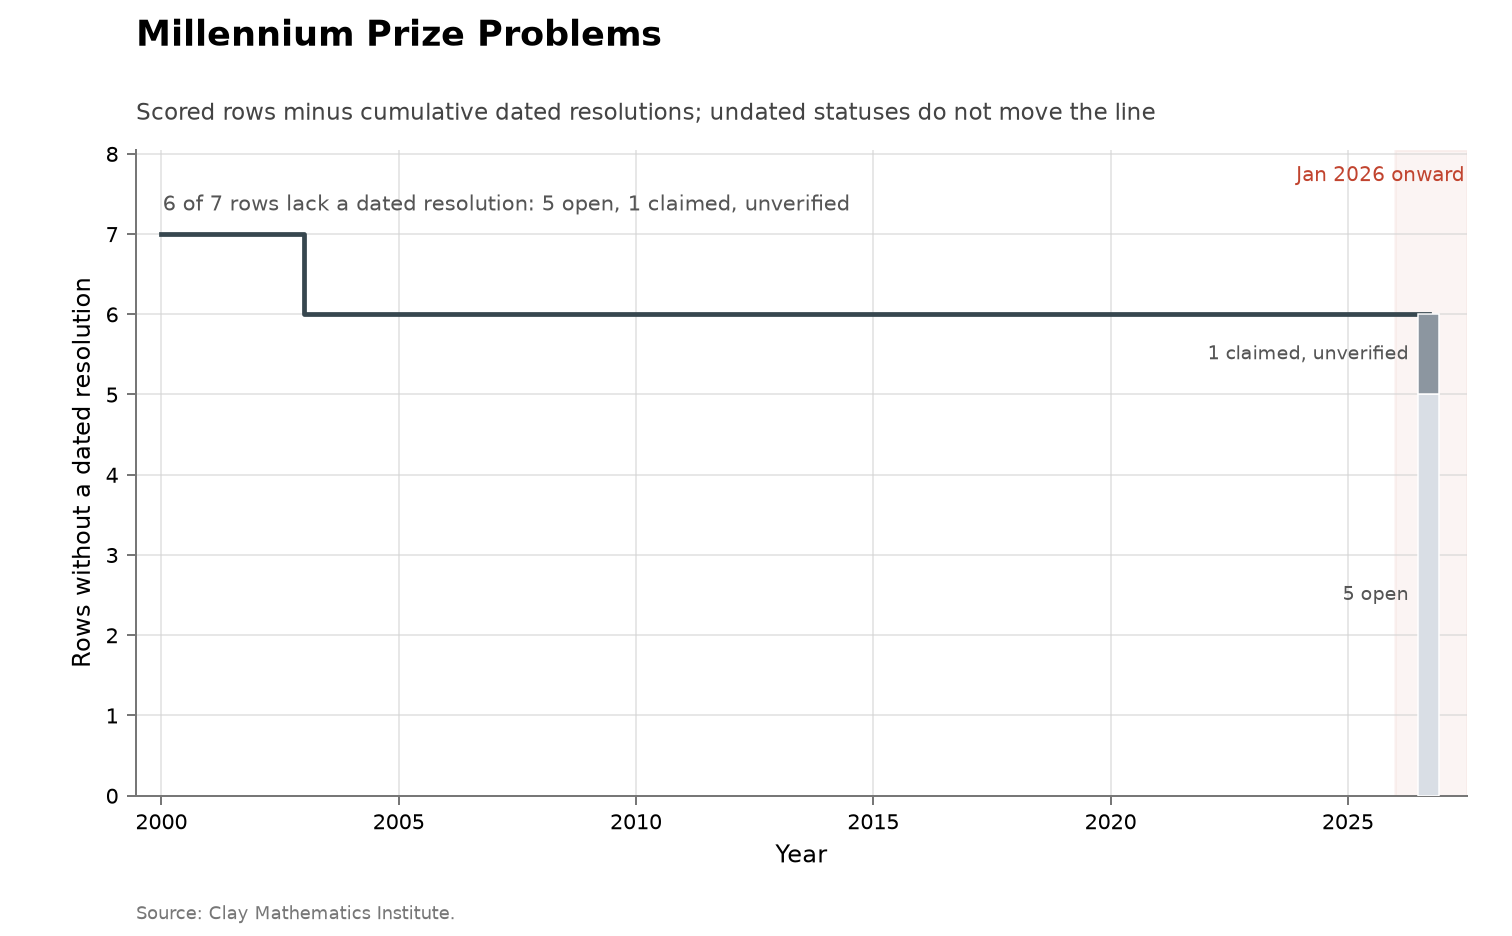
- The Clay Mathematics Institute selected seven problems in 2000 and offered a $1 million prize for each.
- Only the Poincaré conjecture has been resolved, by Perelman’s work in 2002–2003; the other six remain open.
Smale’s problems: one AI-assisted resolution
- Smale’s 1998 list of eighteen “problems for the next century” is a modern successor to Hilbert’s list.
- Five rows have been resolved.
- One was resolved with AI help: Alpöge and Claude Fable’s 2026 counterexample to the Jacobian conjecture in dimensions three and above.
The Open Problems Project: no clear acceleration
- The Open Problems Project is a maintained list of seventy-eight computational-geometry problems, many asking for an algorithm, a complexity bound, or an NP-hardness proof.
- Seventeen rows have been resolved: thirteen by 2010, followed by isolated resolutions in 2015, 2019, 2023, and 2024. None is AI-attributed.
- The recent pace is slower, not faster, although missing dates for when problems entered the list prevent treating this as a clean fixed-cohort solve rate.
Notable LLM contributions
| Date | Result | What happened | Domain expertise / prompt generality | Expenditure |
|---|---|---|---|---|
| Dec 2023 | FunSearch (cap set) | Improved asymptotic cap-set lower bound (claimed largest in ~20 years); LLM evolves programs scored by an automated evaluator | Nature: “feedback loops between domain experts and FunSearch.” | MIT TR: “After a couple of million suggestions and a few dozen repetitions of the overall process—which took a few days.” |
| May 2025 | AlphaEvolve (e.g. kissing # in dim. 11) | Raised dim.-11 kissing lower bound 592→593; later paper: improved a minority of ~50–67 open problems (mostly small nudges) | “can be readily scaled up to study large classes of problems at a time, without requiring extensive expert supervision for each new problem” — but “in the hands of a user who is a subject expert… AlphaEvolve has always performed much better”; “Giving AlphaEvolve an insightful piece of expert advice in the prompt almost always led to significantly better results.” Tao: failed on analytic number theory “even when given suitable expert hints.” | Authors: setup “took only up to a few hours”; dollar cost of the 67-problem campaign unknown. |
| May 2026 | OpenAI unit-distance disproof | Disproved Erdős’s 1946 unit-distance growth conjecture (\(n^{1+\delta}\) construction); independently digested by nine mathematicians | OpenAI: “The proof came from a new general-purpose reasoning model, rather than from a system trained specifically for mathematics, scaffolded to search through proof strategies, or targeted at the unit distance problem in particular.” | Unknown. |
| May 2026 | AlphaProof Nexus | Formal verify-and-retry agents resolved 9 of a vendor-defined set of 353 open Erdős problems (~2.5%); also 44/492 OEIS conjectures | Medium: Lean verify-and-retry on a pre-formalized corpus. Authors: “We did not select which problems to attempt; the set was determined entirely by what the open-source community had formalized”; then “experts on our team validated that the Lean statement faithfully captured the original conjecture.” | Authors: “at the per-problem cost of a few hundred dollars”; but “The reported costs also do not capture the full cost of discovery: we applied the full-featured agent to all 353 Erdős problems… identifying tractable problems was itself a significant computational investment.” |
| Jul 2026 | Alpöge–Claude Fable (Smale 16) | Counterexample to the Jacobian conjecture in dim. \(\ge 3\); independently formalized in Lean and Isabelle; peer review pending | Unclear: the prompting strategy was not disclosed, but the result was announced by mathematician Levent Alpöge: “thanx to my close friend akhil for asking about it and my other close friend fable.” | Unknown; Alpöge says Fable was “working during the world cup final.” |
| Aug 2026 | Anthropic Claude on zeta zeros | Raised the proven lower bound on the fraction of non-trivial zeta zeros on the critical line from 41.6% to 67.2%; Lean formalization; Conrey and Goldston examined on short notice. RH itself remains open. | Low specialist prompting. Anthropic: “Jarred Sumner, an Anthropic staff member (and non-mathematician), prompted Claude to “take a real stab” at the hypothesis itself, leaving the mathematical choices from there up to the model.” High post-hoc validation (Anthropic mathematicians + outside experts + Lean). | Anthropic: “over two sessions in Claude Code, using a total of 31 million output tokens.” |
| Aug 2026 | OpenAI Astra | Vendor package of claimed advances with Lean certificates, including packing/coding upper bounds and Erdős #146/#180/#183; peer review pending | AI-lab hybrid. OpenAI: “an internal version of Astra”; “We helped prepare the manuscripts and formalize the proofs in Lean, and we take responsibility for their correctness, while the mathematical arguments themselves were generated by our system.” | OpenAI: “The total number of tokens needed to find solutions to these problems would cost roughly $2,000 at Sol API rates.” |
Discovery in Algorithms
Problems and time series
NanoGPT speedrun: AI contributions, acceleration unclear.
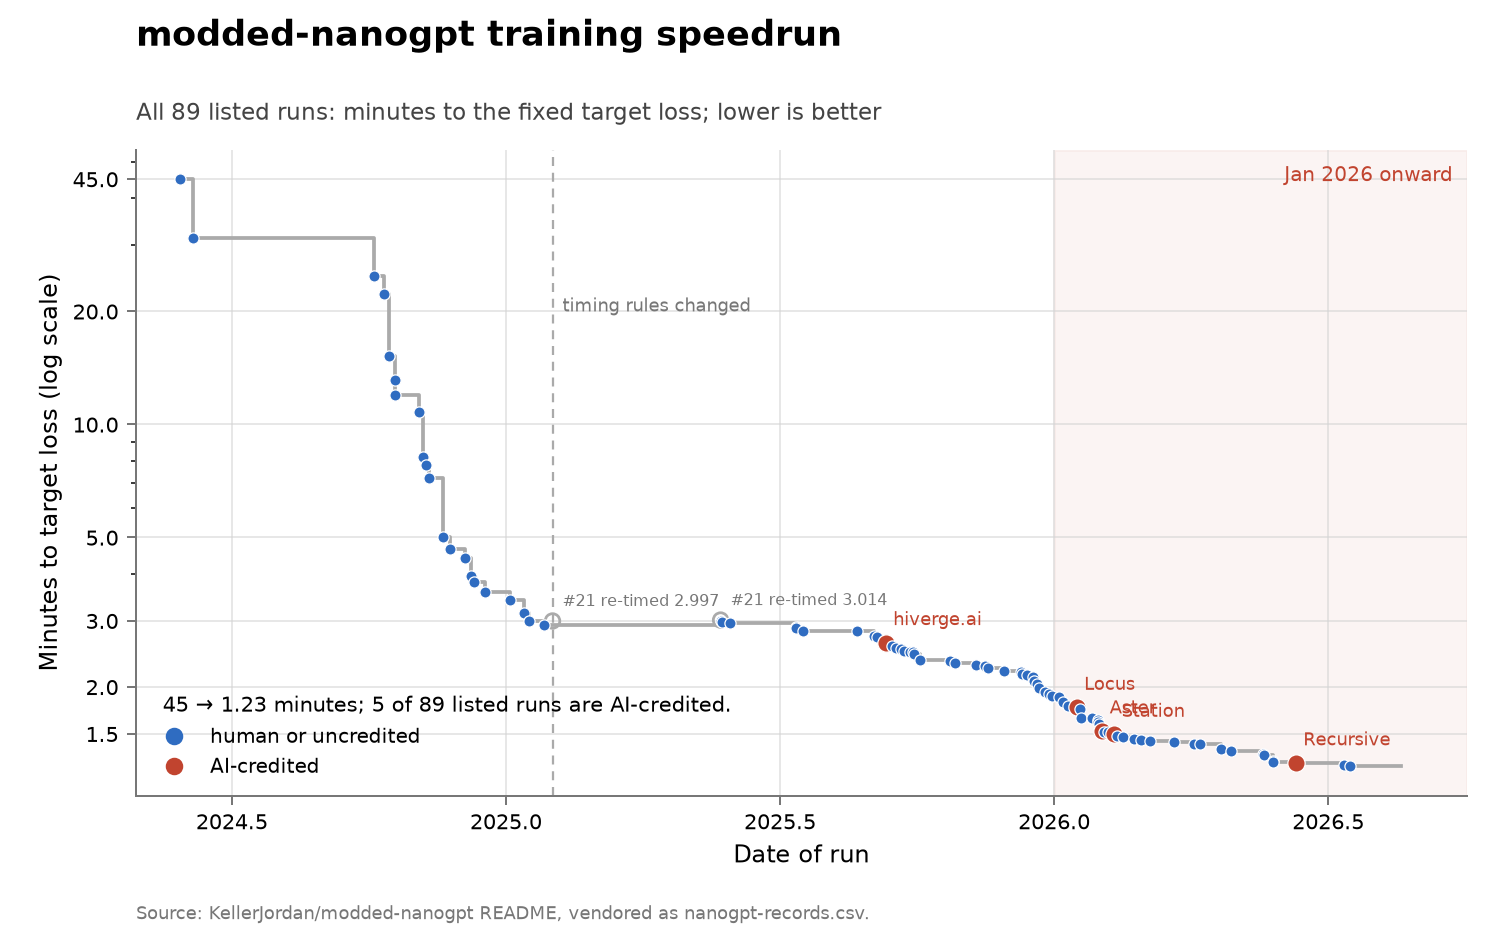
- nanoGPT is a collective competition to minimize the training time for an LLM to reach a specific loss on held-out text, given fixed hardware. We can benchmark progress back to GPT-2, and the overall reduction in training time over 2019-2026 has been estimated at about 700-fold.6
- There have been around six AI-attributed contributions. Taken at face value, they have contributed a fairly small share of the overall progress.
- It is difficult to judge whether there has been an acceleration. Progress in 2024 mostly involved catching up with the frontier. There was little progress from January through August 2025, but since September 2025 there has been regular progress (see Manish Shetty’s discussion of the history of nanoGPT here). It is conceivable that the acceleration in late 2025 and early 2026 was due to unattributed AI use.
CIFAR-10 speedrun: AI contributions, acceleration unclear.
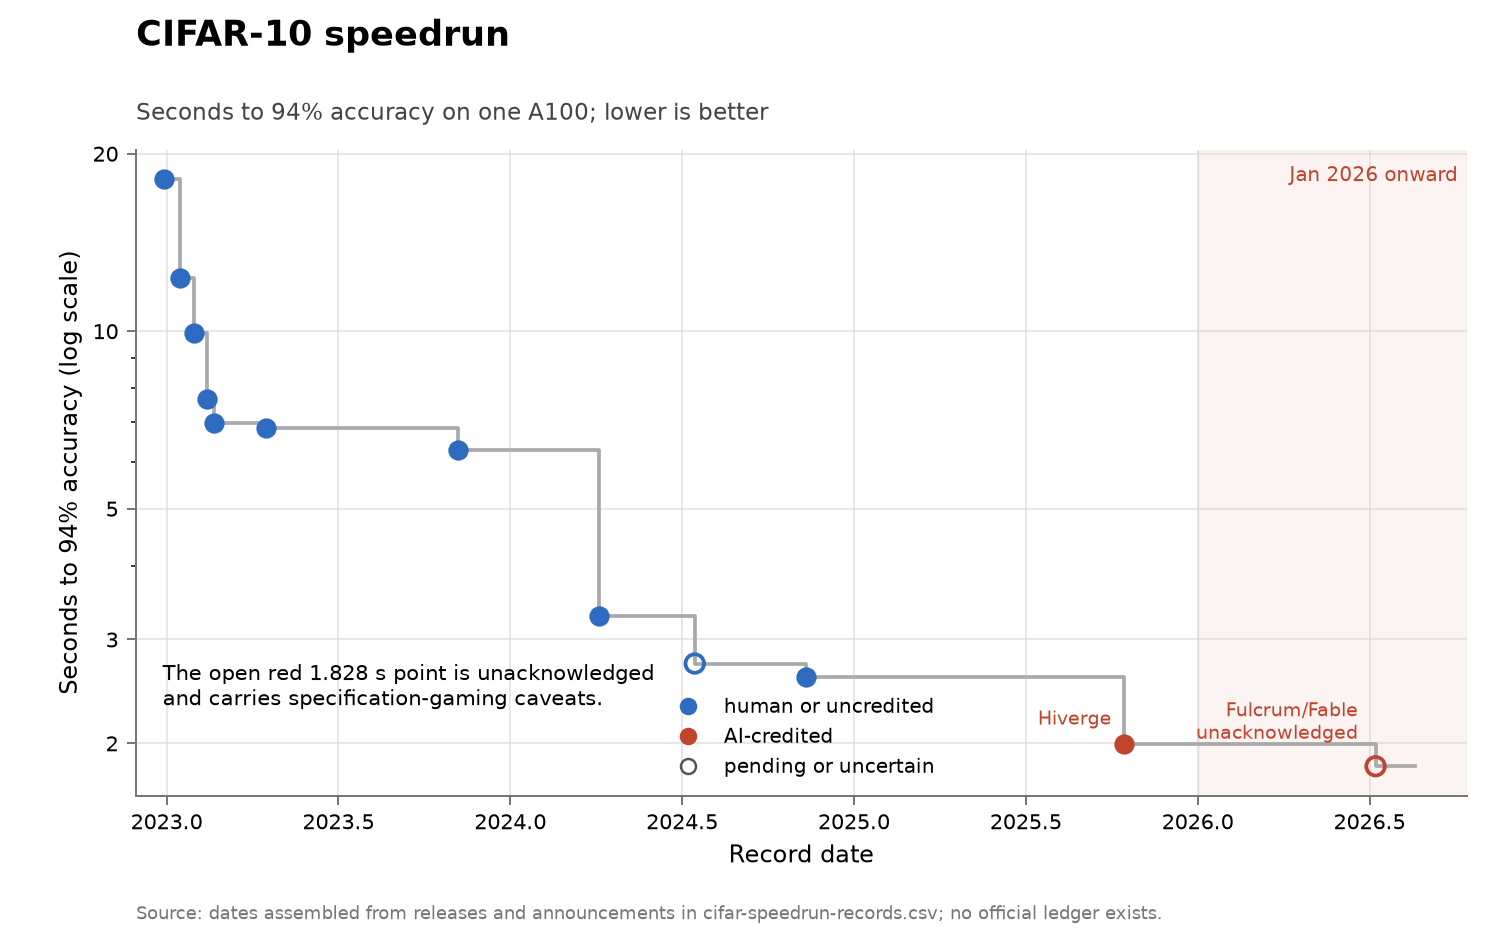
- A public competition to reach 94% test accuracy on CIFAR-10 in as little wall-clock time as possible, on a single A100.
- The newest acknowledged record is AI-set: Hiverge’s engine cut the previous 2.59-second record by about 23%. A later 1.828-second claim (Fulcrum/Fable) is unacknowledged and has specification-gaming caveats.
- The two recent contributions are not outstandingly large by historical standards.
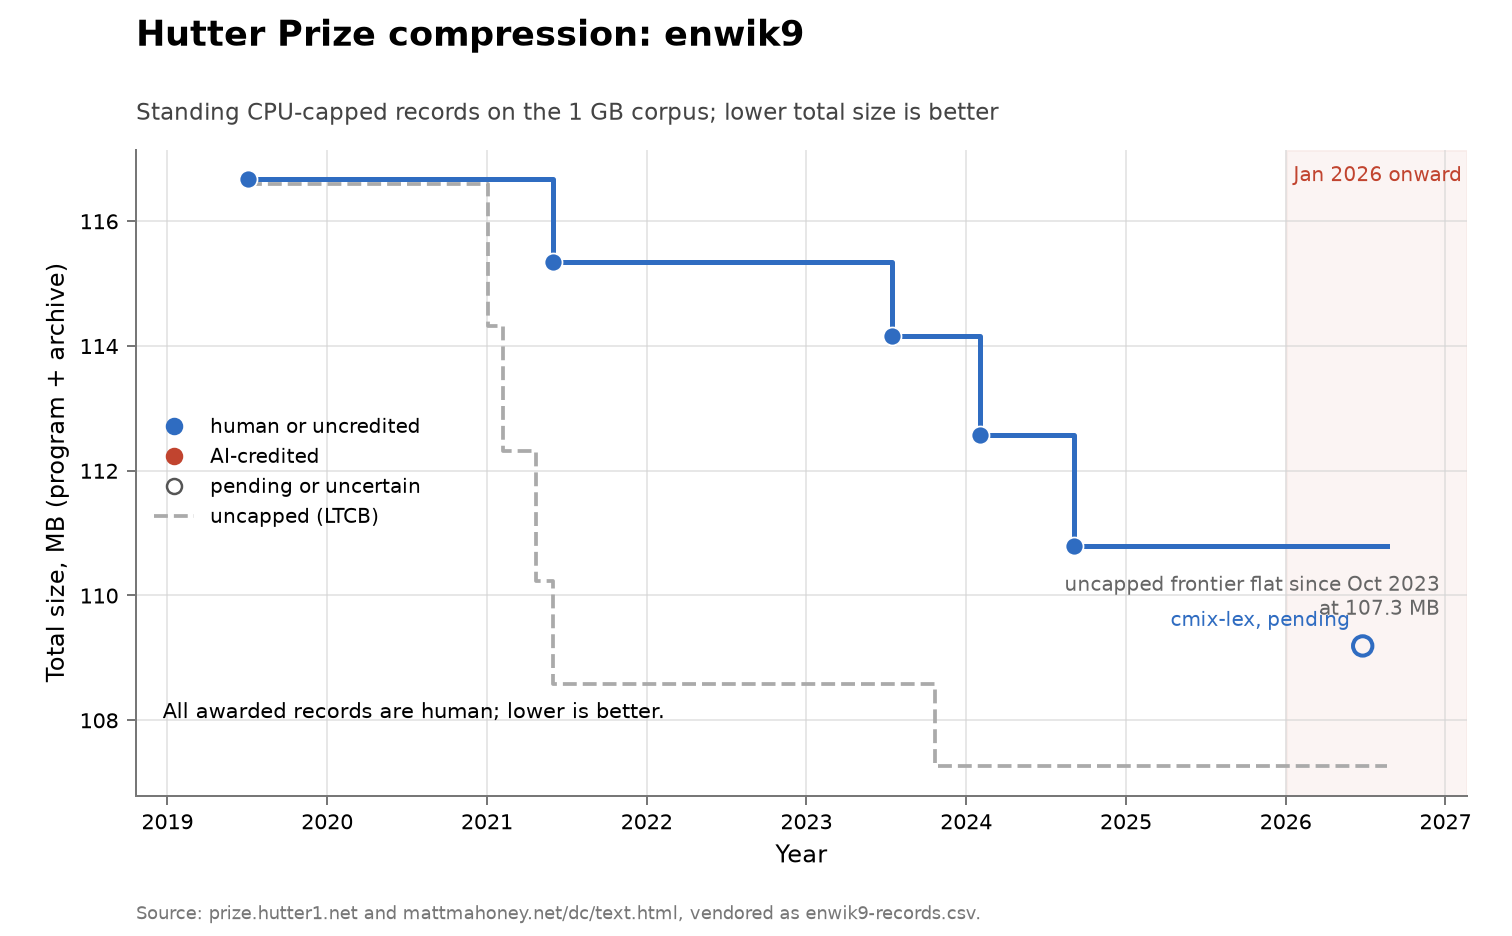
Hutter Prize compression: too sparse.
- A prize for compressing a fixed 1 GB Wikipedia dump, scored on compressed size plus the decompressor, under a single-CPU time and memory cap (no GPUs). The corpus has been frozen since 2006.
- No entry claims a language model wrote the compressor. The leaderboard has not moved since October 2023.
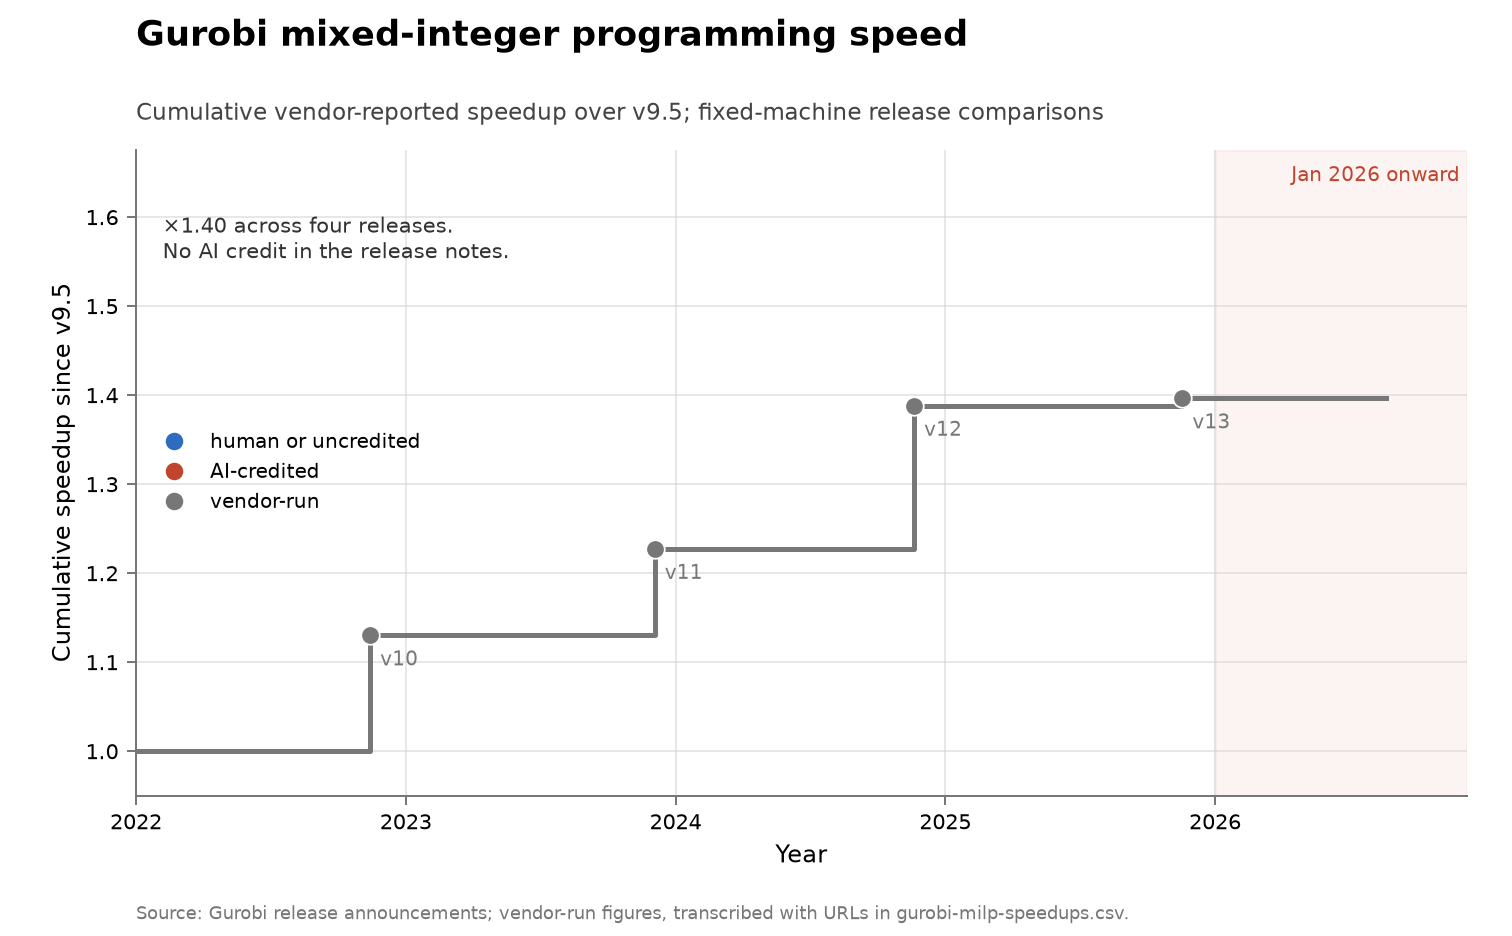
Gurobi mixed-integer programming: no acceleration.
- Gurobi reruns each new solver release on the same machine and the same model set, so the series is a vendor-reported speedup with hardware held fixed.
- Four annual releases (2022–2025) gained 13%, 8.6%, 13.1%, and 0.6%, a cumulative factor of about 1.4 since version 9.5. None of the announcements credits AI.
- The release is only annual, so we may see big speedups in 2026.
- The current pace of improvement seems to be slower than perviously, Grace (2013): says “some mixed integer programming (MIP) algorithms, run on modern MIP instances with modern hardware, have roughly doubled in speed each year”.
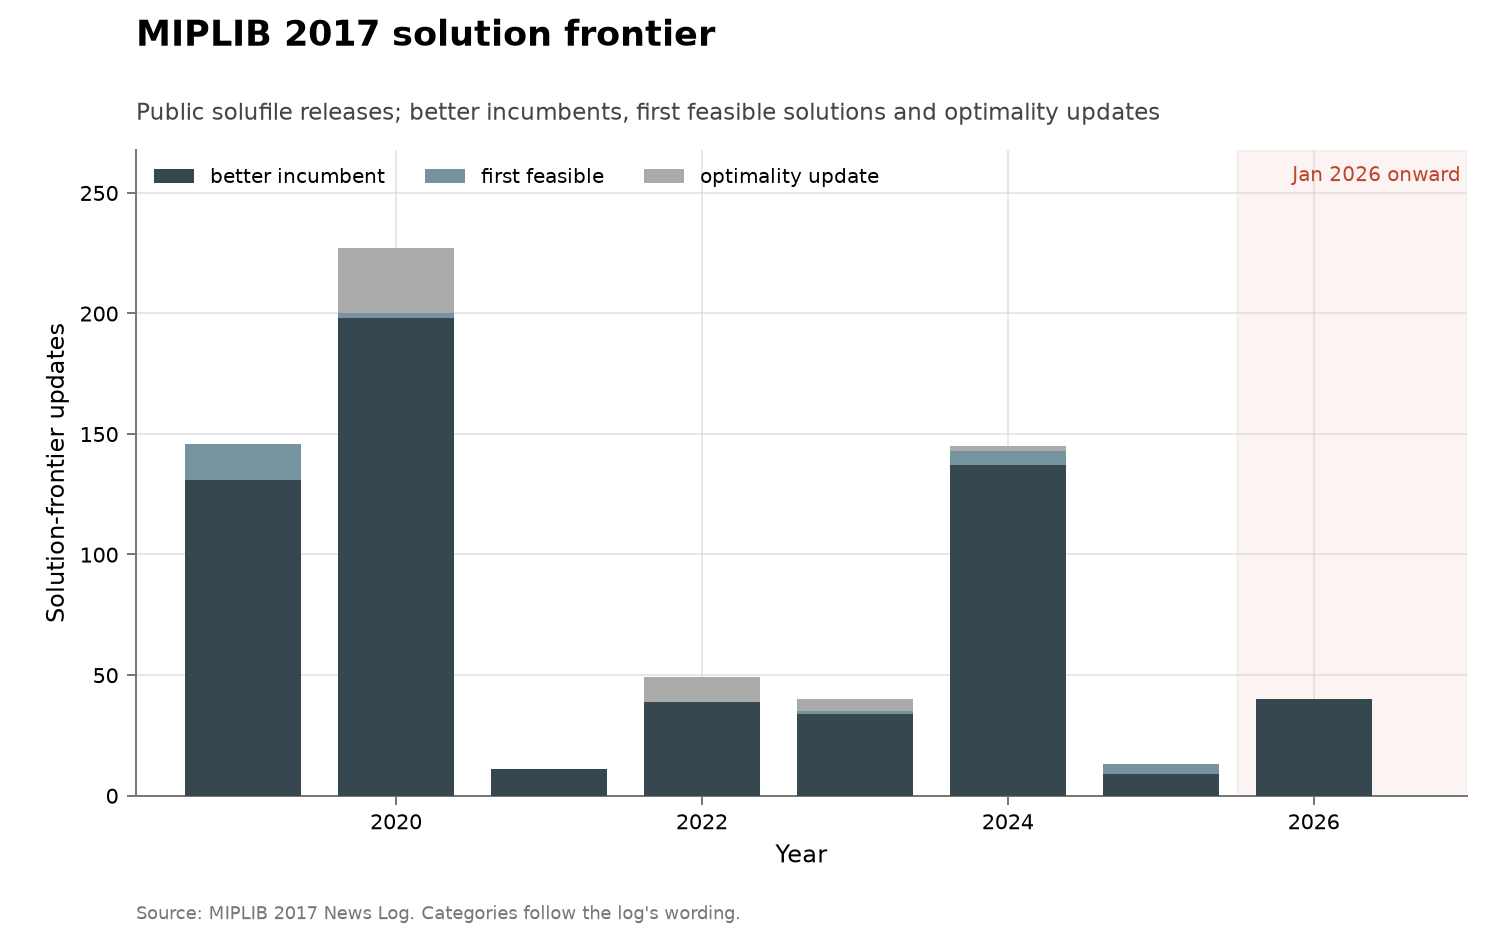
MIPLIB solution frontier: no acceleration
- MIPLIB is a standard public library of mixed-integer programs. Maintainers accept improved solutions to open instances and periodically publish a new solution file, so the series is a history of public frontier updates rather than a timestamped lab notebook.
- Across 28 releases, the log reports hundreds of better incumbents plus a smaller number of first feasible solutions and optimality proofs. Submitters are not labelled consistently enough to count AI contributions; none are stated.
- The largest waves were in late 2019 and early 2020. Later years remain active but do not show a rising rate.
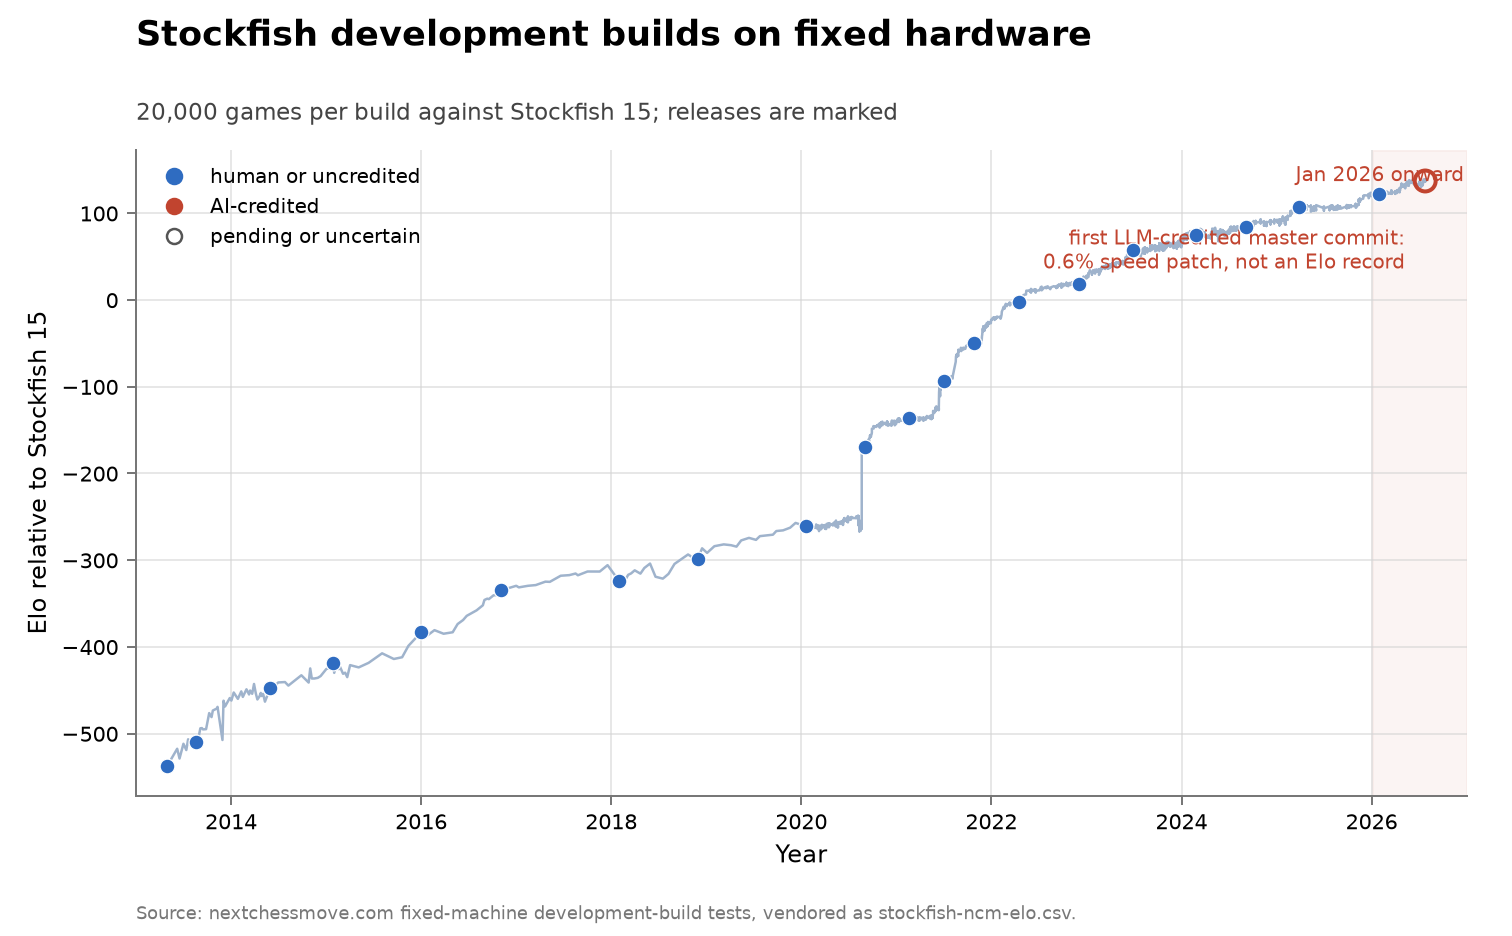
Stockfish Elo: no acceleration
- Stockfish is an open-source chess engine. A third party plays every development build 20,000 times against a frozen opponent (Stockfish 15), using one machine and one time control, so the series is pure software progress on a fixed Elo scale.
- About 675 Elo of software gain from 2013 to 2026, averaging around 50 Elo a year. Exactly one master commit credits a language model (a 0.6% speed patch in July 2026, not an Elo record); no Elo gain in the series is AI-attributed.
- There is no sign of acceleration.
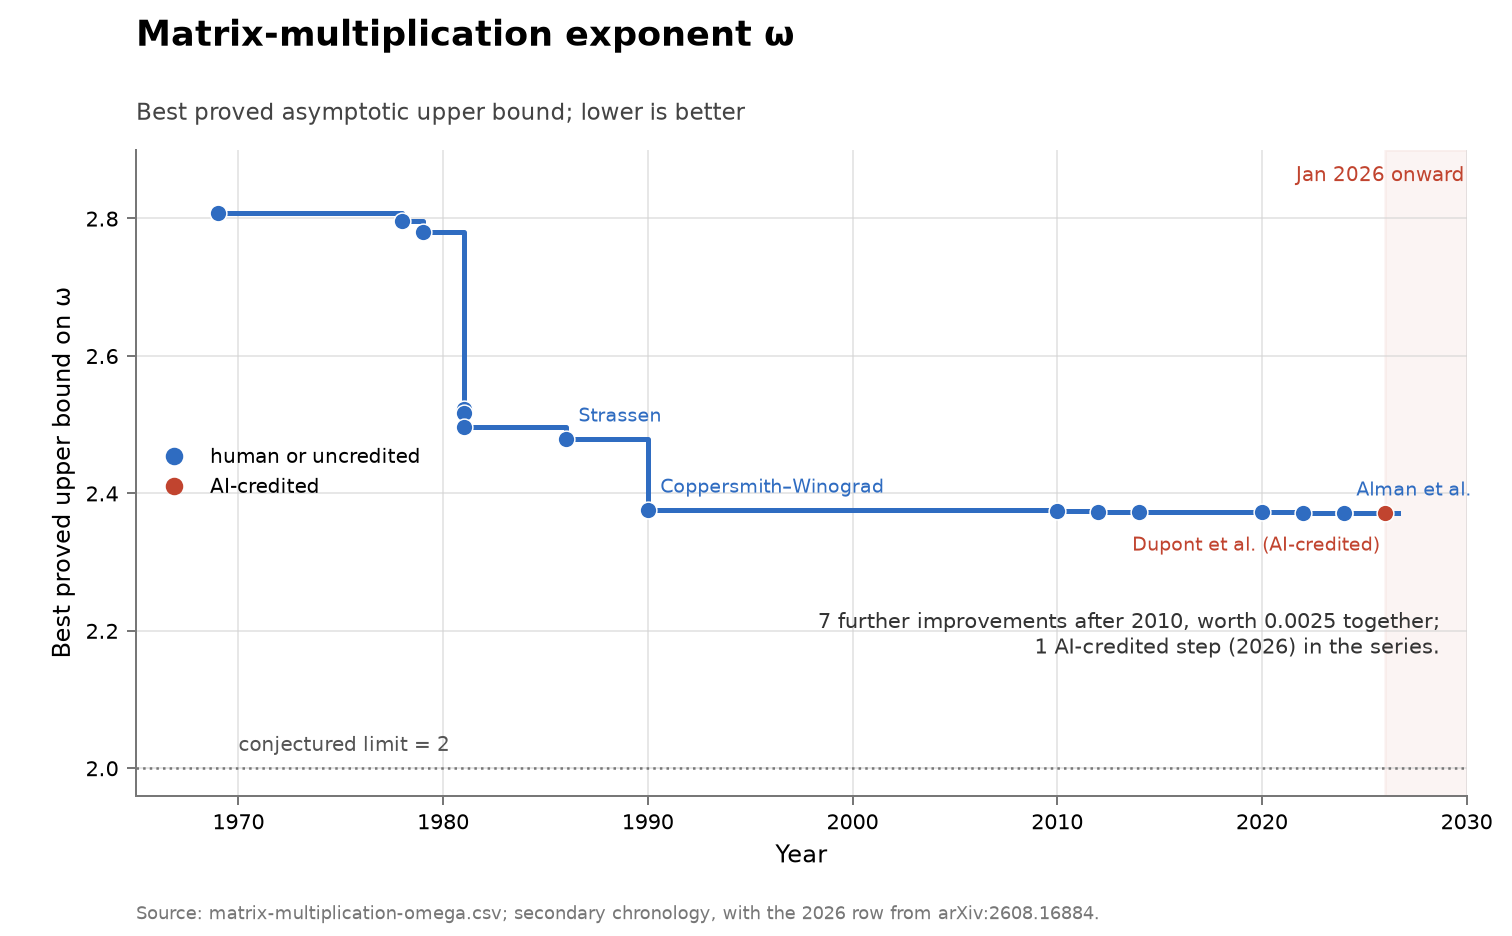
Matrix-multiplication exponent ω: no acceleration
- The exponent \(\omega\) is the best proved asymptotic upper bound on the number of operations needed to multiply two \(n \times n\) matrices.
- The record fell from 2.8074 in 1969 to 2.3755 in 1990, but the six improvements after 2010 moved it only another 0.0024, to 2.371339 in 2024.
- Every step is a human proof, and there is no sign of acceleration. AI has improved algorithms for finite matrix sizes, but not for the asymptotic exponent.
Notes
- Just last year it was notable that LLMs had not contributed much to knowledge.
-
Many people were commenting on the lack of notable contributions by LLMs to knowledge.
One possible explanation is the shift from LLMs trained on human-generated data to LLMs trained directly against the real world (RLVR). See the discussion in my January 2026 post on knowledge-creating versus knowledge-sharing LLMs.
- Most science can’t be judged with a single number.
-
The work of most scientists can’t be judged with a single scalar. Physicists, chemists, and biologists are typically judged by their peers on qualitative grounds.
When we do have a single number (either a set of problems, an upper or lower bound, or a measure of efficiency), it is generally based on problems with cheap validation.
 <!– Paper and code production increased sharply.
-
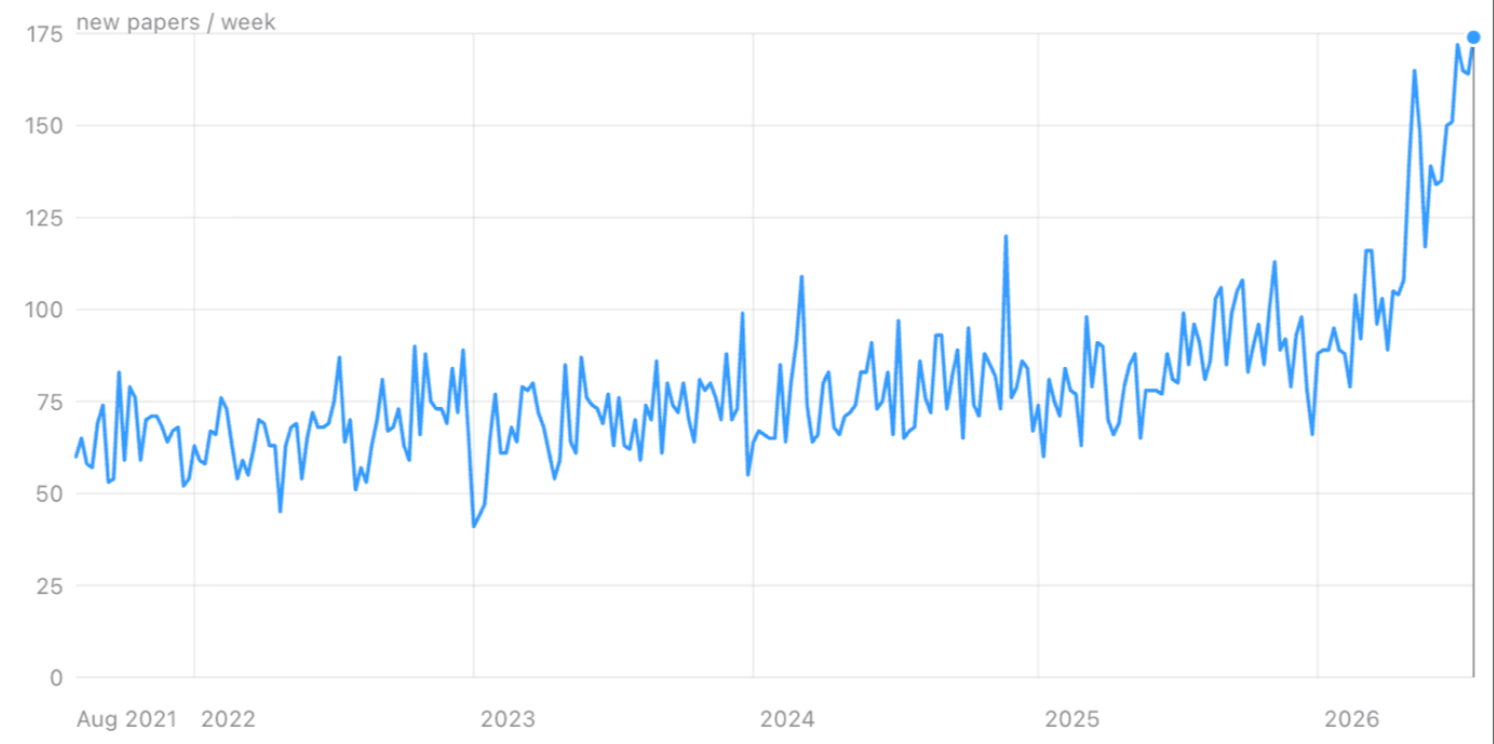
Monthly arXiv submissions rose from 17,271 in November 2022 to 32,040 in June 2026, about 85%. GitHub pushes roughly doubled from late 2024 to early 2026. A particularly sharp explosion is in combinatorics papers (from Daniel Litt):
However these series just measure quantity, not the quality or value of contributions. –>
- <!– Assessing the significance of individual discoveries is hard.
- A new record can be a deep conceptual advance or a tiny movement on a neglected target. Without the size of the step, the prior trend, and a denominator of comparable attempts or human results, a list of successes cannot establish aggregate acceleration. –>
- Measuring an LLM’s ability to make discoveries is hard.
-
In principle we could measure an LLM’s discovery ability offline by giving it a problem and asking for a new result, e.g. a benchmark for discoveries or optimizations.
In practice these are difficult to interpret for many reasons: problem selection and significance, contamination, inference-time scaling, and the division of work between models, scaffolds, and human experts. <!– Is this skill-biased technical change?
-
We can fairly confidently state that some contributions to the frontier have recently come from non-experts across all three domains. This contrasts with the pre-LLM equilibrium, in which non-experts made essentially no contribution to the frontier.
In economics, skill-biased technical change is usually defined as the relative change in productivity across skill levels, so observing an increase in the productivity of low-skilled labor does not identify that relative change. However, observing the share of output due to low-skilled labor does identify the relative effect, at least in a simple model with two types of labor and additive output (e.g. total discoveries).
Thus, it seems reasonable to describe this finding as supporting negative skill-biased technical change. This conclusion would reverse if highly skilled workers were making discoveries so large that the non-expert share became negligible.
It is also unclear whether we should describe the progress as due to low-skill labor or as autonomous, i.e. due only to capital. –>
References
Footnotes
One extreme view by a mathematician, Bartosz Naskręcki in August 2026: “At this pace we should expect about 1000+ conjectures proved every month and growing faster with each cycle … we should end this year with a pile of at least a million proven conjectures and solved open problems. The end of 2026 will mark a significant moment in human history where we will have almost all, say 99% of the current questions completely solved (new will be asked but I fix the bar) and not so many of them actually understood by humans at all.”↩︎
E.g. Anthropic announced in April that it is donating up to $100M worth of Mythos Preview credits for discovering and fixing vulnerabilities; other labs have similar programs.↩︎
Anthropic’s Fable 5 system card said: “we’ve implemented new interventions that limit Claude’s effectiveness for requests targeting frontier LLM development (for example, on building pretraining pipelines, distributed training infrastructure, or ML accelerator design).” Originally the fallback was silent, subsequently it became explicit.↩︎
Microsoft wrote in July 2026: “As AI helps defenders discover more issues, customers will see a higher volume of security updates included in each security release.” See Evolving Windows vulnerability management to meet the speed of AI-powered discovery.↩︎
“This is not intended as a record of when the solutions actually happened, or how quickly problems are being solved - they may have been solved weeks, months, or decades earlier, but it took time to verify or just be notified about the solution. This is just when their status was changed on this site, and has no meaning beyond that.”↩︎
Parker Whitfill estimated a 700X compute efficiency gain over 2019-2026.↩︎