| 0 |
pythia |
pythia-70m |
ladder |
pretraining |
7.04e+07 |
3.00e+11 |
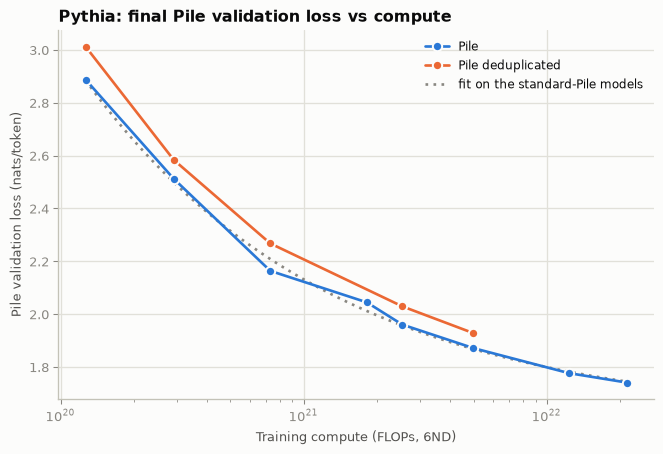
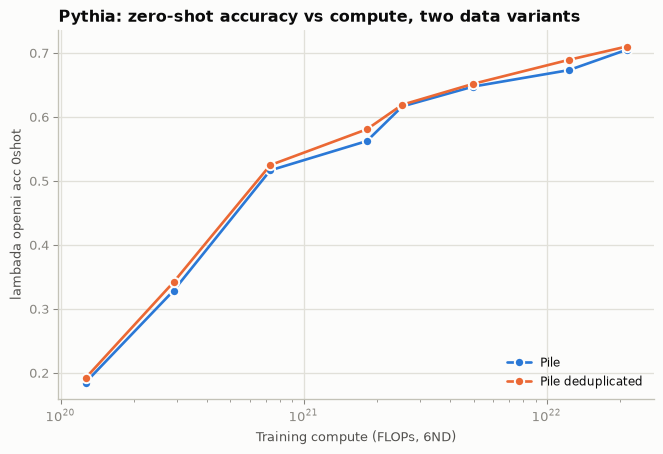
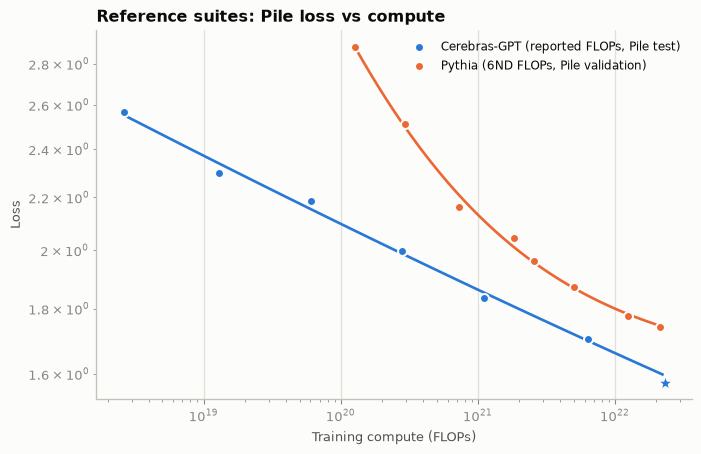
1.27e+20 |
6*N*D with N=total params incl. untied embed/u... |
510.0 |
2.8878 |
lambada_openai_acc_0shot |
0.1846 |
reported |
[src](https://arxiv.org/abs/2304.01373; https:... |
| 1 |
pythia |
pythia-70m |
ladder |
pretraining |
7.04e+07 |
3.00e+11 |
1.27e+20 |
6*N*D with N=total params incl. untied embed/u... |
510.0 |
2.8878 |
piqa_acc_0shot |
0.5947 |
reported |
[src](https://arxiv.org/abs/2304.01373; https:... |
| 2 |
pythia |
pythia-70m-deduped |
ladder |
pretraining |
7.04e+07 |
3.00e+11 |
1.27e+20 |
6*N*D with N=total params incl. untied embed/u... |
510.0 |
3.0127 |
lambada_openai_acc_0shot |
0.1915 |
reported |
[src](https://arxiv.org/abs/2304.01373; https:... |
| 3 |
pythia |
pythia-70m-deduped |
ladder |
pretraining |
7.04e+07 |
3.00e+11 |
1.27e+20 |
6*N*D with N=total params incl. untied embed/u... |
510.0 |
3.0127 |
piqa_acc_0shot |
0.5979 |
reported |
[src](https://arxiv.org/abs/2304.01373; https:... |
| 4 |
pythia |
pythia-160m |
ladder |
pretraining |
1.62e+08 |
3.00e+11 |
2.92e+20 |
6*N*D with N=total params incl. untied embed/u... |
1030.0 |
2.5123 |
lambada_openai_acc_0shot |
0.3284 |
reported |
[src](https://arxiv.org/abs/2304.01373; https:... |
| 5 |
pythia |
pythia-160m |
ladder |
pretraining |
1.62e+08 |
3.00e+11 |
2.92e+20 |
6*N*D with N=total params incl. untied embed/u... |
1030.0 |
2.5123 |
piqa_acc_0shot |
0.6273 |
reported |
[src](https://arxiv.org/abs/2304.01373; https:... |
| 6 |
pythia |
pythia-160m-deduped |
ladder |
pretraining |
1.62e+08 |
3.00e+11 |
2.92e+20 |
6*N*D with N=total params incl. untied embed/u... |
1030.0 |
2.5839 |
lambada_openai_acc_0shot |
0.3417 |
reported |
[src](https://arxiv.org/abs/2304.01373; https:... |
| 7 |
pythia |
pythia-160m-deduped |
ladder |
pretraining |
1.62e+08 |
3.00e+11 |
2.92e+20 |
6*N*D with N=total params incl. untied embed/u... |
1030.0 |
2.5839 |
piqa_acc_0shot |
0.6181 |
reported |
[src](https://arxiv.org/abs/2304.01373; https:... |
| 8 |
pythia |
pythia-410m |
ladder |
pretraining |
4.05e+08 |
3.00e+11 |
7.29e+20 |
6*N*D with N=total params incl. untied embed/u... |
2540.0 |
2.1637 |
lambada_openai_acc_0shot |
0.5162 |
reported |
[src](https://arxiv.org/abs/2304.01373; https:... |
| 9 |
pythia |
pythia-410m |
ladder |
pretraining |
4.05e+08 |
3.00e+11 |
7.29e+20 |
6*N*D with N=total params incl. untied embed/u... |
2540.0 |
2.1637 |
piqa_acc_0shot |
0.6676 |
reported |
[src](https://arxiv.org/abs/2304.01373; https:... |
| 10 |
pythia |
pythia-410m-deduped |
ladder |
pretraining |
4.05e+08 |
3.00e+11 |
7.29e+20 |
6*N*D with N=total params incl. untied embed/u... |
2540.0 |
2.2675 |
lambada_openai_acc_0shot |
0.5244 |
reported |
[src](https://arxiv.org/abs/2304.01373; https:... |
| 11 |
pythia |
pythia-410m-deduped |
ladder |
pretraining |
4.05e+08 |
3.00e+11 |
7.29e+20 |
6*N*D with N=total params incl. untied embed/u... |
2540.0 |
2.2675 |
piqa_acc_0shot |
0.6746 |
reported |
[src](https://arxiv.org/abs/2304.01373; https:... |
| 12 |
pythia |
pythia-1b |
ladder |
pretraining |
1.01e+09 |
3.00e+11 |
1.82e+21 |
6*N*D with N=total params incl. untied embed/u... |
4830.0 |
2.0445 |
lambada_openai_acc_0shot |
0.5620 |
reported |
[src](https://arxiv.org/abs/2304.01373; https:... |
| 13 |
pythia |
pythia-1b |
ladder |
pretraining |
1.01e+09 |
3.00e+11 |
1.82e+21 |
6*N*D with N=total params incl. untied embed/u... |
4830.0 |
2.0445 |
piqa_acc_0shot |
0.7073 |
reported |
[src](https://arxiv.org/abs/2304.01373; https:... |
| 14 |
pythia |
pythia-1b-deduped |
ladder |
pretraining |
1.01e+09 |
3.00e+11 |
1.82e+21 |
6*N*D with N=total params incl. untied embed/u... |
4830.0 |
NaN |
lambada_openai_acc_0shot |
0.5804 |
reported |
[src](https://arxiv.org/abs/2304.01373; https:... |
| 15 |
pythia |
pythia-1b-deduped |
ladder |
pretraining |
1.01e+09 |
3.00e+11 |
1.82e+21 |
6*N*D with N=total params incl. untied embed/u... |
4830.0 |
NaN |
piqa_acc_0shot |
0.7002 |
reported |
[src](https://arxiv.org/abs/2304.01373; https:... |
| 16 |
pythia |
pythia-1.4b |
ladder |
pretraining |
1.41e+09 |
3.00e+11 |
2.54e+21 |
6*N*D with N=total params incl. untied embed/u... |
7120.0 |
1.9605 |
lambada_openai_acc_0shot |
0.6161 |
reported |
[src](https://arxiv.org/abs/2304.01373; https:... |
| 17 |
pythia |
pythia-1.4b |
ladder |
pretraining |
1.41e+09 |
3.00e+11 |
2.54e+21 |
6*N*D with N=total params incl. untied embed/u... |
7120.0 |
1.9605 |
piqa_acc_0shot |
0.7089 |
reported |
[src](https://arxiv.org/abs/2304.01373; https:... |
| 18 |
pythia |
pythia-1.4b-deduped |
ladder |
pretraining |
1.41e+09 |
3.00e+11 |
2.54e+21 |
6*N*D with N=total params incl. untied embed/u... |
7120.0 |
2.0295 |
lambada_openai_acc_0shot |
0.6187 |
reported |
[src](https://arxiv.org/abs/2304.01373; https:... |
| 19 |
pythia |
pythia-1.4b-deduped |
ladder |
pretraining |
1.41e+09 |
3.00e+11 |
2.54e+21 |
6*N*D with N=total params incl. untied embed/u... |
7120.0 |
2.0295 |
piqa_acc_0shot |
0.7203 |
reported |
[src](https://arxiv.org/abs/2304.01373; https:... |
| 20 |
pythia |
pythia-2.8b |
ladder |
pretraining |
2.78e+09 |
3.00e+11 |
4.99e+21 |
6*N*D with N=total params incl. untied embed/u... |
14240.0 |
1.8714 |
lambada_openai_acc_0shot |
0.6472 |
reported |
[src](https://arxiv.org/abs/2304.01373; https:... |
| 21 |
pythia |
pythia-2.8b |
ladder |
pretraining |
2.78e+09 |
3.00e+11 |
4.99e+21 |
6*N*D with N=total params incl. untied embed/u... |
14240.0 |
1.8714 |
piqa_acc_0shot |
0.7388 |
reported |
[src](https://arxiv.org/abs/2304.01373; https:... |
| 22 |
pythia |
pythia-2.8b-deduped |
ladder |
pretraining |
2.78e+09 |
3.00e+11 |
4.99e+21 |
6*N*D with N=total params incl. untied embed/u... |
14240.0 |
1.9281 |
lambada_openai_acc_0shot |
0.6515 |
reported |
[src](https://arxiv.org/abs/2304.01373; https:... |
| 23 |
pythia |
pythia-2.8b-deduped |
ladder |
pretraining |
2.78e+09 |
3.00e+11 |
4.99e+21 |
6*N*D with N=total params incl. untied embed/u... |
14240.0 |
1.9281 |
piqa_acc_0shot |
0.7410 |
reported |
[src](https://arxiv.org/abs/2304.01373; https:... |
| 24 |
pythia |
pythia-6.9b |
ladder |
pretraining |
6.86e+09 |
3.00e+11 |
1.23e+22 |
6*N*D with N=total params incl. untied embed/u... |
33500.0 |
1.7768 |
lambada_openai_acc_0shot |
0.6728 |
reported |
[src](https://arxiv.org/abs/2304.01373; https:... |
| 25 |
pythia |
pythia-6.9b |
ladder |
pretraining |
6.86e+09 |
3.00e+11 |
1.23e+22 |
6*N*D with N=total params incl. untied embed/u... |
33500.0 |
1.7768 |
piqa_acc_0shot |
0.7524 |
reported |
[src](https://arxiv.org/abs/2304.01373; https:... |
| 26 |
pythia |
pythia-6.9b-deduped |
ladder |
pretraining |
6.86e+09 |
3.00e+11 |
1.23e+22 |
6*N*D with N=total params incl. untied embed/u... |
33500.0 |
NaN |
lambada_openai_acc_0shot |
0.6889 |
reported |
[src](https://arxiv.org/abs/2304.01373; https:... |
| 27 |
pythia |
pythia-6.9b-deduped |
ladder |
pretraining |
6.86e+09 |
3.00e+11 |
1.23e+22 |
6*N*D with N=total params incl. untied embed/u... |
33500.0 |
NaN |
piqa_acc_0shot |
0.7601 |
reported |
[src](https://arxiv.org/abs/2304.01373; https:... |
| 28 |
pythia |
pythia-12b |
ladder |
pretraining |
1.18e+10 |
3.00e+11 |
2.13e+22 |
6*N*D with N=total params incl. untied embed/u... |
72300.0 |
1.7412 |
lambada_openai_acc_0shot |
0.7046 |
reported |
[src](https://arxiv.org/abs/2304.01373; https:... |
| 29 |
pythia |
pythia-12b |
ladder |
pretraining |
1.18e+10 |
3.00e+11 |
2.13e+22 |
6*N*D with N=total params incl. untied embed/u... |
72300.0 |
1.7412 |
piqa_acc_0shot |
0.7601 |
reported |
[src](https://arxiv.org/abs/2304.01373; https:... |
| 30 |
pythia |
pythia-12b-deduped |
ladder |
pretraining |
1.18e+10 |
3.00e+11 |
2.13e+22 |
6*N*D with N=total params incl. untied embed/u... |
72300.0 |
NaN |
lambada_openai_acc_0shot |
0.7097 |
reported |
[src](https://arxiv.org/abs/2304.01373; https:... |
| 31 |
pythia |
pythia-12b-deduped |
ladder |
pretraining |
1.18e+10 |
3.00e+11 |
2.13e+22 |
6*N*D with N=total params incl. untied embed/u... |
72300.0 |
NaN |
piqa_acc_0shot |
0.7628 |
reported |
[src](https://arxiv.org/abs/2304.01373; https:... |
| 0 |
cerebras-gpt |
cerebras-gpt-111m |
ladder |
pretraining |
1.11e+08 |
2.22e+09 |
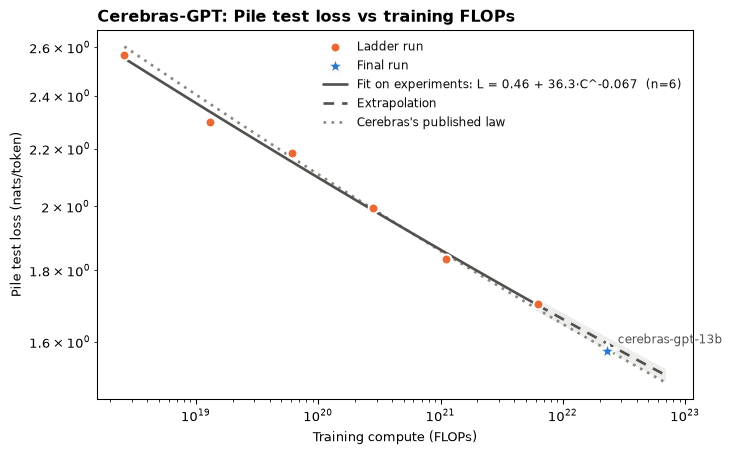
2.60e+18 |
reported in HF model card / paper (Cerebras FL... |
NaN |
2.5660 |
lambada_acc_0shot |
0.1940 |
reported |
[src](https://arxiv.org/abs/2304.03208; https:... |
| 3 |
cerebras-gpt |
cerebras-gpt-256m |
ladder |
pretraining |
2.56e+08 |
5.12e+09 |
1.30e+19 |
reported in HF model card / paper (Cerebras FL... |
NaN |
2.2990 |
lambada_acc_0shot |
0.2930 |
reported |
[src](https://arxiv.org/abs/2304.03208; https:... |
| 6 |
cerebras-gpt |
cerebras-gpt-590m |
ladder |
pretraining |
5.90e+08 |
1.18e+10 |
6.10e+19 |
reported in HF model card / paper (Cerebras FL... |
NaN |
2.1840 |
lambada_acc_0shot |
0.3660 |
reported |
[src](https://arxiv.org/abs/2304.03208; https:... |
| 9 |
cerebras-gpt |
cerebras-gpt-1.3b |
ladder |
pretraining |
1.32e+09 |
2.63e+10 |
2.80e+20 |
reported in HF model card / paper (Cerebras FL... |
NaN |
1.9960 |
lambada_acc_0shot |
0.4620 |
reported |
[src](https://arxiv.org/abs/2304.03208; https:... |
| 12 |
cerebras-gpt |
cerebras-gpt-2.7b |
ladder |
pretraining |
2.65e+09 |
5.30e+10 |
1.10e+21 |
reported in HF model card / paper (Cerebras FL... |
NaN |
1.8340 |
lambada_acc_0shot |
0.5670 |
reported |
[src](https://arxiv.org/abs/2304.03208; https:... |
| 15 |
cerebras-gpt |
cerebras-gpt-6.7b |
ladder |
pretraining |
6.66e+09 |
1.33e+11 |
6.30e+21 |
reported in HF model card / paper (Cerebras FL... |
NaN |
1.7040 |
lambada_acc_0shot |
0.6360 |
reported |
[src](https://arxiv.org/abs/2304.03208; https:... |
| 17 |
cerebras-gpt |
cerebras-gpt-13b |
final |
pretraining |
1.29e+10 |
2.57e+11 |
2.30e+22 |
reported in HF model card / paper (Cerebras FL... |
NaN |
1.5750 |
lambada_acc_0shot |
0.6960 |
reported |
[src](https://arxiv.org/abs/2304.03208; https:... |