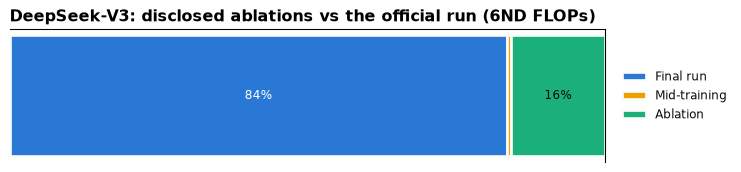
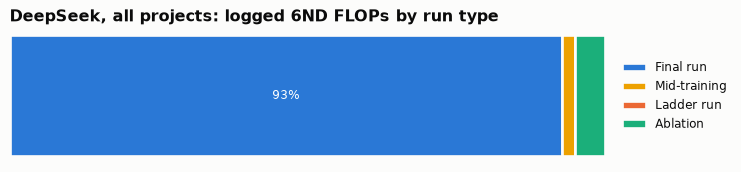
Disclosed non-final share for V3: 16% of logged FLOPs.
DeepSeek is the lab with the most-quoted training cost and the most explicit statement of what that cost leaves out. The V3 report’s 2.788M H800-hours ($5.576M at $2 per hour) covers “only the official training of DeepSeek-V3, excluding the costs associated with prior research and ablation experiments on architectures, algorithms, or data.” This chapter asks how much of the excluded part the reports themselves let us reconstruct. Working notes with sources are in data/notes/deepseek.md; 51 verbatim statements are in the claims table.
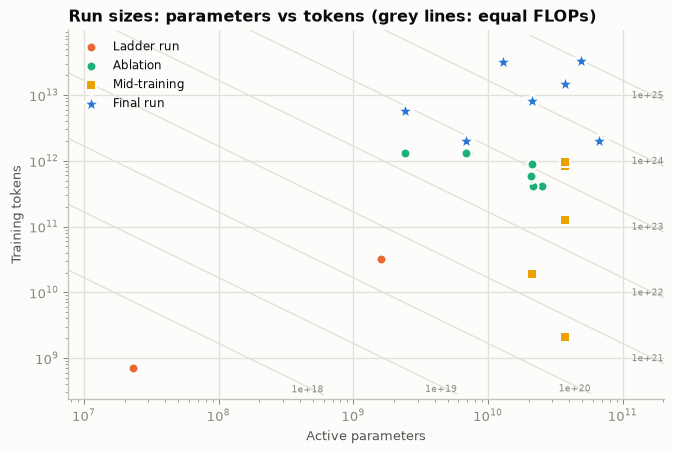
The V3 report describes its ablations by size and tokens: multi-token prediction and auxiliary-loss-free balancing each tested on a 15.7B mixture-of-experts model at 1.33T tokens and a 228.7B model at 540 to 578B tokens, and FP8 against BF16 on models “similar to DeepSeek-V2-Lite and DeepSeek-V2” for about 1T tokens each. Summed at 6ND with both runs of each pair counted, those disclosed ablations come to roughly one sixth of the compute of the 3.3e24 final run (the bar below gives the exact share). Nothing about the many runs behind the architecture and data choices is counted, so this is a floor, and a low one.
Disclosed non-final share for V3: 16% of logged FLOPs.
Two contrasts with the labs that count everything. Ai2 reports 82 percent development for Olmo 3 and Meta about 70 percent for LLaMA 1. If DeepSeek’s true ratio were similar, the widely quoted $5.6M would be a fifth to a third of the programme’s compute cost.
The first report is the only one with a full ladder: eight IsoFLOP budgets from 1e17 to 3e20 FLOPs with about ten allocations each (roughly 80 runs, derived), fitted to M_opt = 0.1715 · C^0.5243 and D_opt = 5.8316 · C^0.4757 (non-embedding FLOPs per token and tokens), plus hyperparameter laws for learning rate and batch size. The 7B and 67B are overlaid on the loss-versus-compute curve and described as “well-predicted” at about 1,000 times the largest ladder run, but no numerical error is printed. Later reports (V2, V3) ablate at two fixed scales instead of fitting laws, and R1, V3.2 and V4 mention small-scale preparation only qualitatively. Disclosure of the experimental process has fallen with each release even as the cost figure became more precise.
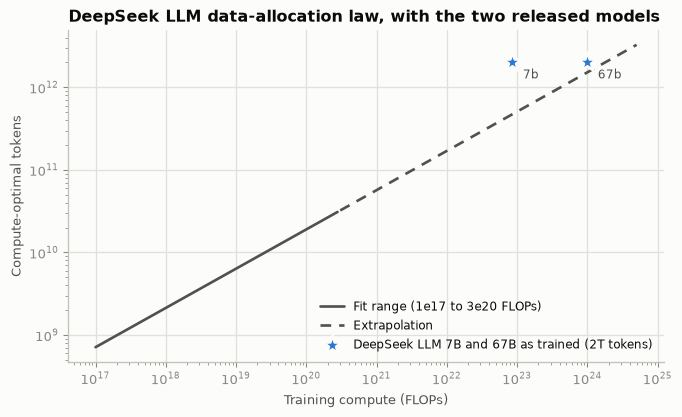
Both released models sit well above the fitted optimum in tokens: they were deliberately over-trained for inference efficiency, as most released open models are.
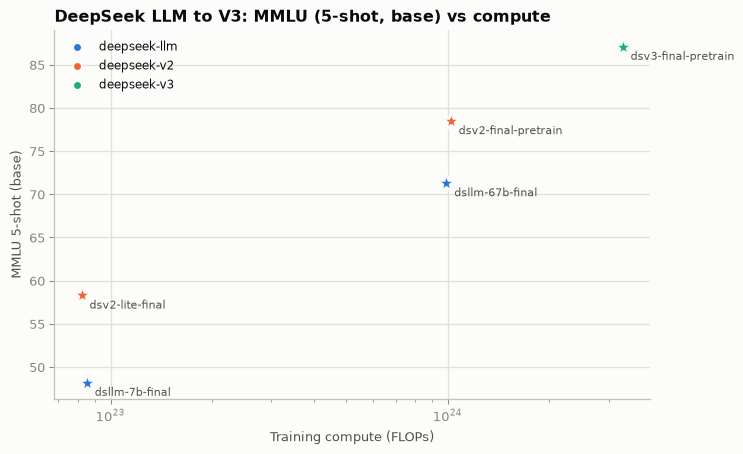
R1’s revised report gives the RL programme’s cost directly: 512 H800s for 198 hours (R1-Zero, 101K GPU-hours) plus 80 hours (R1, 41K) plus 5K for SFT data, 147K GPU-hours or $294K, about 5 percent of the V3 pretraining run. A 30B preparatory model was trained on A100s first with no figures given. V3.2 states that post-training now exceeds 10 percent of pretraining cost.
| project | date | stage | intervention | model_sizes | compute_range | metric | fitted_exponent | exponent_source | raw_data_available | source_url | notes | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 0 | deepseek-llm | 2024-01-05 | pretraining | batch size and learning rate vs compute budget... | 177M FLOPs/token model at C=1e17 (grid); multi... | 1e17-2e19 (fit); 1e20 (validation) | generalization error (bits-per-byte on validat... | B_opt = 0.2920*C^0.3271; eta_opt = 0.3118*C^-0... | paper Eq. (1) / Sec 3.1 | figure_only | [src](https://arxiv.org/abs/2401.02954) | near-optimal defined as within 0.25% of min ge... |
| 1 | deepseek-llm | 2024-01-05 | pretraining | IsoFLOP optimal model/data allocation (compute... | ~80 models: 8 compute budgets x ~10 model/data... | 1e17-3e20 | bits-per-byte on in-house validation set | M_opt = 0.1715*C^0.5243; D_opt = 5.8316*C^0.47... | paper Eq. (3), Fig. 4 | figure_only | [src](https://arxiv.org/abs/2401.02954) | uses M=72*n_layer*d_model^2+12*n_layer*d_model... |
| 2 | deepseek-llm | 2024-01-05 | pretraining | loss-vs-compute extrapolation to final 7B and ... | small models 1e17-3e20 (grey circles) vs DeepS... | 1e17-1e24 | bits-per-byte on validation set | power law of optimal generalization error vs C... | paper Fig. 5 | figure_only | [src](https://arxiv.org/abs/2401.02954) | 'using small-scale experiments can accurately ... |
| 3 | deepseek-llm | 2024-01-05 | pretraining | data quality effect on scaling exponents (thre... | IsoFLOP suites on early in-house data, current... | not stated (presumably 1e17-3e20) | bits-per-byte | a/b: early data 0.450/0.550; current data 0.52... | paper Table 4 | numbers_in_text | [src](https://arxiv.org/abs/2401.02954) | 'as data quality improves, the model scaling e... |
| 4 | deepseek-v2 | 2024-05-07 | pretraining | attention variant: MHA vs GQA(8) vs MQA in 7B ... | 7.1B / 6.9B / 6.9B dense, 1.33T tokens each | ~5.5e22 each (6ND) | BBH, MMLU, C-Eval, CMMLU | numbers_in_text | [src](https://arxiv.org/abs/2405.04434) | Appendix D.1, Table 8; MHA best (MMLU 45.2 vs ... | ||
| 5 | deepseek-v2 | 2024-05-07 | pretraining | MLA vs MHA in MoE at two scales | ~16B total (2.4-2.5B active) on 1.33T tokens; ... | ~2e22 (small) to ~6e22 (large) (6ND active) | BBH, MMLU, C-Eval, CMMLU; KV cache per token | numbers_in_text | [src](https://arxiv.org/abs/2405.04434) | Appendix D.2, Table 9; MLA slightly better wit... | ||
| 6 | deepseek-v3 | 2024-12-27 | pretraining | multi-token prediction (MTP) objective | 15.7B MoE on 1.33T tokens; 228.7B MoE on 540B ... | ~2e22 to ~7e22 (6ND active; large active param... | Pile BPB, BBH, MMLU, DROP, TriviaQA, NQ, Human... | numbers_in_text | [src](https://arxiv.org/abs/2412.19437) | Table 4; large: HumanEval 44.5->53.7, GSM8K 72... | ||
| 7 | deepseek-v3 | 2024-12-27 | pretraining | auxiliary-loss-free load balancing vs auxiliar... | 15.7B MoE on 1.33T tokens; 228.7B MoE on 578B ... | ~2e22 to ~7e22 | Pile BPB, BBH, MMLU, HumanEval, MBPP, GSM8K, MATH | numbers_in_text | [src](https://arxiv.org/abs/2412.19437) | Table 5; large HumanEval 40.2->46.3 | ||
| 8 | deepseek-v3 | 2024-12-27 | pretraining | FP8 mixed-precision vs BF16 training | ~16B (V2-Lite-like) and ~230B (V2-like) MoE, ~... | ~1.4e22 and ~1.3e23 per run | training loss curve; relative loss error | relative loss error < 0.25% | Appendix B.1, Fig. 10 | figure_only | [src](https://arxiv.org/abs/2412.19437) | 'the relative loss error of our FP8-training m... |
| 9 | deepseek-v3 | 2024-12-27 | pretraining | batch-wise vs sequence-wise load balancing | 1B MoE (3 runs, validation loss 2.258/2.253/2.... | not stated | validation loss; expert load on Pile test | numbers_in_text | [src](https://arxiv.org/abs/2412.19437) | Sec 4.5.3, Fig. 9 | ||
| 10 | deepseek-r1 | 2025-01-22 | post-training/RL | RL preparation on a smaller model before scaling | 30B model on A100 GPUs | not stated | not stated ('results ... have been promising') | numbers_in_text | [src](https://arxiv.org/abs/2501.12948v2) | arXiv v2 Appendix B.4.4 only mentions the expe... | ||
| 11 | deepseek-r1 | 2025-01-22 | post-training/RL | RL training dynamics of R1-Zero (AIME accuracy... | 671B/37B (DeepSeek-V3-Base) | 101K H800 GPU-hours total | AIME 2024 pass@1 (avg of 16 samples) and cons@... | figure_only | [src](https://arxiv.org/abs/2501.12948) | Fig. 2/3; 15.6% -> 71.0% over 10,400 steps (st... | ||
| 12 | deepseek-r1 | 2025-01-22 | post-training/RL | large-scale RL vs distillation on Qwen-32B | Qwen-32B-Base RL >10K steps vs Distill-Qwen-32... | not stated | AIME 2024, MATH-500, GPQA, LiveCodeBench | numbers_in_text | [src](https://arxiv.org/abs/2501.12948) | Table 6; distillation wins (AIME 72.6 vs RL mo... | ||
| 13 | deepseek-r1 | 2025-01-22 | post-training/RL | unsuccessful attempts: process reward model, MCTS | not stated | not stated | qualitative | numbers_in_text | [src](https://arxiv.org/abs/2501.12948) | Sec 4.2 describes failures (reward hacking, se... | ||
| 14 | deepseek-v3.2 | 2025-12-02 | midtraining | DeepSeek Sparse Attention via continued pretra... | 671B/37B; 2.1B dense warm-up + 943.7B sparse t... | ~2e23 (6ND active, rough) | benchmark parity (MMLU-Pro 85.0, AIME 2025 89.... | numbers_in_text | [src](https://github.com/deepseek-ai/DeepSeek-... | training configurations aligned with V3.1-Term... |
| project | claim | value | unit | source_url | quote | notes | |
|---|---|---|---|---|---|---|---|
| 0 | deepseek-v3 | official training cost excludes research/ablat... | 5.576e6 | USD | [src](https://arxiv.org/abs/2412.19437) | Note that the aforementioned costs include onl... | Table 1 context; verbatim via GitHub-mirrored ... |
| 1 | deepseek-v3 | cost assumption | 2 | USD per H800 GPU-hour | [src](https://arxiv.org/abs/2412.19437) | Assuming the rental price of the H800 GPU is $... | |
| 2 | deepseek-v3 | GPU-hour breakdown | 2664K / 119K / 5K / 2788K | H800 GPU-hours (pretraining / context extensio... | [src](https://arxiv.org/abs/2412.19437) | Pre-Training 2664K ($5.328M); Context Extensio... | Table 1 |
| 3 | deepseek-v3 | pretraining efficiency | 180000 | H800 GPU-hours per trillion tokens | [src](https://arxiv.org/abs/2412.19437) | Consequently, our pre-training stage is comple... | wording reassembled from two adjacent sentence... |
| 4 | deepseek-v3 | cluster size | 2048 | H800 GPUs | [src](https://arxiv.org/abs/2412.19437) | DeepSeek-V3 is trained on a cluster equipped w... | |
| 5 | deepseek-v3 | training stability | 0 | irrecoverable loss spikes / rollbacks | [src](https://arxiv.org/abs/2412.19437) | Throughout the entire training process, we did... | |
| 6 | deepseek-v3 | FP8 ablation scale | ~16B on 1.33T tokens; ~230B on ~0.9T tokens | params; tokens | [src](https://arxiv.org/abs/2412.19437) | approximately 16B total parameters on 1.33T to... | Appendix B.1, verified in arXiv HTML v2 on 202... |
| 7 | deepseek-v3 | FP8 relative loss error | <0.25 | percent | [src](https://arxiv.org/abs/2412.19437) | the relative loss error of our FP8-training mo... | Appendix B.1 / Fig. 10 |
| 8 | deepseek-v3 | MTP ablation scales | 15.7B on 1.33T; 228.7B on 540B | params; tokens | [src](https://arxiv.org/abs/2412.19437) | small MoE model, comprising 15.7B total parame... | Sec 4.5.1 (paraphrase of table-adjacent text; ... |
| 9 | deepseek-v3 | aux-loss-free ablation scales | 15.7B on 1.33T; 228.7B on 578B | params; tokens | [src](https://arxiv.org/abs/2412.19437) | Table 5: small MoE 15.7B total params, 1.33T t... | Sec 4.5.2 |
| 10 | deepseek-v3 | load-balance ablation validation losses | 2.258 / 2.253 / 2.253 | validation loss (1B MoE: sequence-wise aux los... | [src](https://arxiv.org/abs/2412.19437) | On 1B MoE models, the validation losses are: 2... | Sec 4.5.3 |
| 11 | deepseek-v3 | expert-load analysis scale | 16B | params | [src](https://arxiv.org/abs/2412.19437) | we record and analyze the expert load of a 16B... | Sec 4.5.3 / Fig. 9 |
| 12 | deepseek-v3 | Pile-test BPB (base) | 0.548 | bits-per-byte | [src](https://github.com/deepseek-ai/DeepSeek-V3) | Pile-test (BPB): DeepSeek-V2 Base 0.606; Qwen2... | README benchmark table |
| 13 | deepseek-v3 | MTP acceptance rate | 85-90 | percent of second-token predictions accepted | [src](https://arxiv.org/abs/2412.19437) | the acceptance rate of the second token predic... | Sec 5.4.3 / conclusion; wording via mirror |
| 14 | deepseek-v3 | author count | 199 | named authors (Appendix A, v1 and v2; arXiv li... | [src](https://arxiv.org/abs/2412.19437) | Appendix A counted 2026-09-13: Research & Engi... | REFUTES the earlier 139 (Interconnects, 2025-0... |
| 15 | deepseek-v3 | total experimentation multiplier (external est... | 2-4 | x final-run cost | [src](https://www.interconnects.ai/p/deepseek-... | Lambert estimates the $5.5M reported figure re... | paraphrase from GitHub-mirrored article text; ... |
| 16 | deepseek-v3 | GPU fleet estimate (external) | ~50,000 | Hopper GPUs (mix of H800/H100/H20) | [src](https://semianalysis.com/2025/01/31/deep... | DeepSeek has access to roughly 50,000 Hopper G... | from search-result snippet; semianalysis.com b... |
| 17 | deepseek-v2 | training cost per trillion tokens | 300.6K (67B) vs 172.8K (V2) | H800 GPU-hours per trillion tokens | [src](https://arxiv.org/abs/2405.04434) | During our practical training on the H800 clus... | Sec 3.2.3; verbatim from PDF text |
| 18 | deepseek-v2 | pretraining tokens | 8.1e12 | tokens | [src](https://arxiv.org/abs/2405.04434) | Our tokenized pre-training corpus contains 8.1... | |
| 19 | deepseek-v2 | MLA ablation scales | ~16B on 1.33T; ~250B on 420B | params; tokens | [src](https://arxiv.org/abs/2405.04434) | Two small MoE models comprise about 16B total ... | Appendix D.2 |
| 20 | deepseek-v2 | attention ablation scale | 7B dense x3 on 1.33T | params; tokens | [src](https://arxiv.org/abs/2405.04434) | We show the evaluation results for 7B dense mo... | Appendix D.1 |
| 21 | deepseek-v2 | context extension | 1000 steps x 576 seqs x 32K | steps | [src](https://arxiv.org/abs/2405.04434) | We additionally train the model for 1000 steps... | |
| 22 | deepseek-v2 | V2-Lite scale | 15.7B total / 2.4B active; 5.7T tokens | params; tokens | [src](https://arxiv.org/abs/2405.04434) | DeepSeek-V2-Lite comprises 15.7B total paramet... | Appendix B |
| 23 | deepseek-llm | IsoFLOP experiment design | 8 budgets x ~10 allocations; 1e17-3e20 | compute budgets (FLOPs) | [src](https://arxiv.org/abs/2401.02954) | We selected 8 different compute budgets rangin... | Sec 3.2 |
| 24 | deepseek-llm | optimal allocation fit | M_opt = 0.1715*C^0.5243; D_opt = 5.8316*C^0.4757 | power-law fit | [src](https://arxiv.org/abs/2401.02954) | M_opt = M_base * C^a, M_base = 0.1715, a = 0.5... | Eq. (3) |
| 25 | deepseek-llm | hyperparameter scaling fit | eta_opt = 0.3118*C^-0.1250; B_opt = 0.2920*C^0... | power-law fit | [src](https://arxiv.org/abs/2401.02954) | eta_opt = 0.3118 * C^-0.1250, B_opt = 0.2920 *... | Eq. (1); fit over 1e17-2e19, validated at 1e20 |
| 26 | deepseek-llm | hyperparameter grid compute | 1e17 (grid, 177M FLOPs/token); 1e20 (validatio... | FLOPs | [src](https://arxiv.org/abs/2401.02954) | We initially conducted a grid search for batch... | Sec 3.1 |
| 27 | deepseek-llm | prediction accuracy (qualitative) | 1000 | x compute extrapolation | [src](https://arxiv.org/abs/2401.02954) | The results indicate that using small-scale ex... | no numeric error reported |
| 28 | deepseek-llm | 7B/67B well-predicted (Fig. 5 caption) | bits-per-byte | [src](https://arxiv.org/abs/2401.02954) | Performance scaling curve. The metric is bits-... | Fig. 5 caption; figure with small runs and fin... | |
| 29 | deepseek-llm | near-optimal criterion | 0.25 | percent above minimum generalization error | [src](https://arxiv.org/abs/2401.02954) | We regarded the parameters used by models whos... | |
| 30 | deepseek-llm | data-quality dependence of exponents | a/b = 0.450/0.550, 0.524/0.476, 0.578/0.422 | exponents (early data, current data, OpenWebTe... | [src](https://arxiv.org/abs/2401.02954) | as data quality improves, the model scaling ex... | Table 4 |
| 31 | deepseek-llm | author count | 86 | authors | [src](https://arxiv.org/abs/2401.02954) | (author block counted: Xiao Bi ... Yuheng Zou ... | counted from GitHub-mirrored transcription |
| 32 | deepseek-r1 | R1 training cost table | 101K / 5K / 41K / 147K | H800 GPU-hours (R1-Zero / SFT data creation / ... | [src](https://arxiv.org/abs/2501.12948v2) | Table 7 | Training costs of DeepSeek-R1, assum... | arXiv v2 (4 Jan 2026) Appendix B.4.4; verbatim... |
| 33 | deepseek-r1 | RL hardware and duration | 64*8 H800; 198 h (R1-Zero); ~80 h (R1) | GPUs; hours | [src](https://arxiv.org/abs/2501.12948v2) | For the training of DeepSeek-R1-Zero, we emplo... | |
| 34 | deepseek-r1 | preparatory small-model experiments | 30B on A100 | params | [src](https://arxiv.org/abs/2501.12948v2) | Regarding our research on DeepSeek-R1, we util... | |
| 35 | deepseek-r1 | R1-Zero RL steps | 10400 | steps (1.6 epochs; batch 512) | [src](https://arxiv.org/abs/2501.12948v2) | for a total of 10,400 steps, corresponding to ... | |
| 36 | deepseek-r1 | R1 second RL stage steps | 1700 | steps | [src](https://arxiv.org/abs/2501.12948v2) | The stage comprises a total of 1,700 training ... | |
| 37 | deepseek-r1 | SFT data | ~600k reasoning + ~200k non-reasoning = ~800k | samples | [src](https://arxiv.org/abs/2501.12948) | In total, we collect about 600k reasoning rela... | |
| 38 | deepseek-r1 | R1-Zero AIME progression | 15.6 -> 71.0 (86.7 cons@64) | percent | [src](https://arxiv.org/abs/2501.12948) | the pass@1 score on AIME 2024 increases from 1... | |
| 39 | deepseek-r1 | RL vs distillation ablation | over 10K steps | RL steps on Qwen-32B-Base | [src](https://arxiv.org/abs/2501.12948) | we conduct large-scale RL training on Qwen-32B... | |
| 40 | deepseek-r1 | author count | 195 | authors (v1 appendix, incl. departed members) | [src](https://arxiv.org/abs/2501.12948) | (Appendix A Contributions and Acknowledgments:... | |
| 41 | deepseek-v2 | author count | 158 | authors | [src](https://arxiv.org/abs/2405.04434) | (Appendix A Contributions and Acknowledgments ... | |
| 42 | deepseek-v3.2 | post-training budget vs pretraining | 10 | percent of pre-training cost (lower bound) | [src](https://arxiv.org/abs/2512.02556) | this framework allocates a post-training compu... | via GitHub-mirrored transcription |
| 43 | deepseek-v3.2 | DSA continued pretraining tokens | 2.1e9 (dense warm-up) + 943.7e9 (sparse) | tokens | [src](https://github.com/deepseek-ai/DeepSeek-... | We train the indexer for only 1000 steps, with... | V3.2-Exp report PDF in repo |
| 44 | deepseek-v3.2 | knowledge gap attributed to FLOPs | [src](https://arxiv.org/abs/2512.02556) | due to fewer total training FLOPs, the breadth... | |||
| 45 | deepseek-v3.2 | agentic RL environments | 1800 / 85000 | environments / prompts | [src](https://arxiv.org/abs/2512.02556) | over 1,800 distinct environments and 85,000 co... | |
| 46 | deepseek-v3.1 | continued pretraining tokens | 839e9 (630e9 at 32K + 209e9 at 128K) | tokens | [src](https://huggingface.co/deepseek-ai/DeepS... | The 32K extension phase has been increased 10-... | DeepSeek-V3.1-Base model card README, fetched ... |
| 47 | deepseek-v4 | pretraining tokens | 33T (Pro) / 32T (Flash) | tokens | [src](https://arxiv.org/abs/2606.19348) | pre-train both models on more than 32T diverse... | Confirmed in report Sec 4 (https://arxiv.org/h... |
| 48 | deepseek-v4 | efficiency vs V3.2 | 27% FLOPs / 10% KV cache | relative single-token inference cost at 1M con... | [src](https://arxiv.org/abs/2606.19348) | DeepSeek-V4-Pro requires only 27% of single-to... | |
| 49 | lab-level | Fire-Flyer 2 cluster | 10000 | PCIe A100 GPUs (built 2021) | [src](https://arxiv.org/abs/2408.14158) | Fire-Flyer 2 with 10,000 PCIe A100 GPUs, achie... | SC24 paper; abstract via mirrors |
| 50 | lab-level | headcount (press) | ~160 | employees (Dec 2024) | [src](https://www.tomshardware.com/tech-indust... | Deepseek has 'about 160' employees (sources sp... | from search snippet; page blocked |
| 51 | deepseek-v3.2 | author count | 263 | named authors (212 R&E + 27 Data Annotation + ... | [src](https://arxiv.org/abs/2512.02556) | (Appendix 'Author List' of https://arxiv.org/h... | Replaces the earlier 342 in the notes, which m... |
| 52 | deepseek-v4 | author count | 318 | named authors (270 R&E + 48 Business & Complia... | [src](https://arxiv.org/abs/2606.19348) | (Appendix A.1 of https://arxiv.org/html/2606.1... |
| project | run_id | run_type | stage | params_total | tokens | flops | flops_method | gpu_hours | loss | benchmark_name | benchmark_value | confidence | source_url | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 0 | deepseek-llm | dsllm-7b-final | final | pretraining | 6.90e+09 | 2.00e+12 | 8.50e+22 | M*D with M=72*n_layer*d_model^2+12*n_layer*d_m... | NaN | NaN | MMLU (5-shot) | 48.2 | reported | [src](https://arxiv.org/abs/2401.02954) |
| 1 | deepseek-llm | dsllm-67b-final | final | pretraining | 6.70e+10 | 2.00e+12 | 9.90e+23 | M*D; 95 layers, d=8192, GQA 8 kv heads, l_seq=... | 601000.0 | NaN | MMLU (5-shot) | 71.3 | derived | [src](https://arxiv.org/abs/2405.04434) |
| 2 | deepseek-llm | dsllm-7b-chat | final | post-training/RL | 6.90e+09 | NaN | NaN | GSM8K (chat) | 63.0 | reported | [src](https://arxiv.org/abs/2401.02954) | |||
| 3 | deepseek-llm | dsllm-67b-chat | final | post-training/RL | 6.70e+10 | NaN | NaN | GSM8K (chat) | 84.1 | reported | [src](https://arxiv.org/abs/2401.02954) | |||
| 4 | deepseek-llm | dsllm-hparam-grid-1e17 | ladder | pretraining | 1.00e+17 | paper's compute budget C = M*D (non-embedding ... | NaN | NaN | NaN | reported | [src](https://arxiv.org/abs/2401.02954) | |||
| 5 | deepseek-llm | dsllm-hparam-sweep-1e17-2e19 | ladder | pretraining | 2.00e+19 | compute budgets ranging from 1e17 to 2e19 (val... | NaN | NaN | NaN | reported | [src](https://arxiv.org/abs/2401.02954) | |||
| 6 | deepseek-llm | dsllm-hparam-validation-1e20 | ladder | pretraining | 1.00e+20 | paper compute budget | NaN | NaN | NaN | reported | [src](https://arxiv.org/abs/2401.02954) | |||
| 7 | deepseek-llm | dsllm-isoflop-budget-min-1e17 | ladder | pretraining | 2.30e+07 | 7.10e+08 | 1.00e+17 | paper compute budget C=M*D; params derived as ... | NaN | NaN | NaN | derived | [src](https://arxiv.org/abs/2401.02954) | |
| 8 | deepseek-llm | dsllm-isoflop-budget-max-3e20 | ladder | pretraining | 1.60e+09 | 3.20e+10 | 3.00e+20 | paper compute budget C=M*D; params derived as ... | NaN | NaN | NaN | derived | [src](https://arxiv.org/abs/2401.02954) | |
| 9 | deepseek-llm | dsllm-scaling-data-quality-suite | ladder | pretraining | NaN | NaN | NaN | reported | [src](https://arxiv.org/abs/2401.02954) | |||||
| 10 | deepseek-v2 | dsv2-final-pretrain | final | pretraining | 2.36e+11 | 8.10e+12 | 1.02e+24 | 6*N_active*D = 6*2.1e10*8.1e12 | 1400000.0 | 0.606 | MMLU (5-shot) | 78.5 | derived | [src](https://arxiv.org/abs/2405.04434) |
| 11 | deepseek-v2 | dsv2-context-ext-128k | midtrain | midtraining | 2.36e+11 | 1.90e+10 | 2.40e+21 | 6*N_active*D; tokens derived as 1000 steps x 5... | NaN | NaN | NaN | derived | [src](https://arxiv.org/abs/2405.04434) | |
| 12 | deepseek-v2 | dsv2-chat-sft-rl | final | post-training/RL | 2.36e+11 | NaN | NaN | GSM8K (chat RL) | 92.2 | reported | [src](https://arxiv.org/abs/2405.04434) | |||
| 13 | deepseek-v2 | dsv2-lite-final | final | pretraining | 1.57e+10 | 5.70e+12 | 8.20e+22 | 6*N_active*D | NaN | NaN | MMLU | 58.3 | reported | [src](https://arxiv.org/abs/2405.04434) |
| 14 | deepseek-v2 | dsv2-abl-attn-7b-mqa | ablation | pretraining | 7.10e+09 | 1.33e+12 | 5.67e+22 | 6*N*D | NaN | NaN | MMLU (5-shot) | 37.9 | reported | [src](https://arxiv.org/abs/2405.04434) |
| 15 | deepseek-v2 | dsv2-abl-attn-7b-gqa8 | ablation | pretraining | 6.90e+09 | 1.33e+12 | 5.51e+22 | 6*N*D | NaN | NaN | MMLU (5-shot) | 41.2 | reported | [src](https://arxiv.org/abs/2405.04434) |
| 16 | deepseek-v2 | dsv2-abl-attn-7b-mha | ablation | pretraining | 6.90e+09 | 1.33e+12 | 5.51e+22 | 6*N*D | NaN | NaN | MMLU (5-shot) | 45.2 | reported | [src](https://arxiv.org/abs/2405.04434) |
| 17 | deepseek-v2 | dsv2-abl-mla-small-mha | ablation | pretraining | 1.58e+10 | 1.33e+12 | 2.00e+22 | 6*N_active*D | NaN | NaN | MMLU (5-shot) | 48.7 | reported | [src](https://arxiv.org/abs/2405.04434) |
| 18 | deepseek-v2 | dsv2-abl-mla-small-mla | ablation | pretraining | 1.57e+10 | 1.33e+12 | 1.90e+22 | 6*N_active*D | NaN | NaN | MMLU (5-shot) | 50.0 | reported | [src](https://arxiv.org/abs/2405.04434) |
| 19 | deepseek-v2 | dsv2-abl-mla-large-mha | ablation | pretraining | 2.51e+11 | 4.20e+11 | 6.30e+22 | 6*N_active*D | NaN | NaN | MMLU (5-shot) | 57.5 | reported | [src](https://arxiv.org/abs/2405.04434) |
| 20 | deepseek-v2 | dsv2-abl-mla-large-mla | ablation | pretraining | 2.47e+11 | 4.20e+11 | 5.40e+22 | 6*N_active*D | NaN | NaN | MMLU (5-shot) | 59.0 | reported | [src](https://arxiv.org/abs/2405.04434) |
| 21 | deepseek-v3 | dsv3-final-pretrain | final | pretraining | 6.71e+11 | 1.48e+13 | 3.30e+24 | 6*N_active*D = 6*3.7e10*1.48e13 (excludes MTP ... | 2664000.0 | 0.548 | MMLU (5-shot EM) | 87.1 | reported | [src](https://arxiv.org/abs/2412.19437) |
| 22 | deepseek-v3 | dsv3-context-ext-32k-128k | midtrain | midtraining | 6.71e+11 | 1.26e+11 | 2.80e+22 | 6*N_active*D; tokens derived: 1000 steps x 192... | 119000.0 | NaN | NaN | derived | [src](https://arxiv.org/abs/2412.19437) | |
| 23 | deepseek-v3 | dsv3-post-training | final | post-training/RL | 6.71e+11 | 5000.0 | NaN | MATH-500 (chat EM) | 90.2 | reported | [src](https://arxiv.org/abs/2412.19437) | |||
| 25 | deepseek-v3 | dsv3-abl-mtp-small-baseline | ablation | pretraining | 1.57e+10 | 1.33e+12 | 1.90e+22 | 6*N_active*D (2.4B activated params, V3 report... | NaN | NaN | NaN | reported | [src](https://arxiv.org/abs/2412.19437) | |
| 26 | deepseek-v3 | dsv3-abl-mtp-small-mtp | ablation | pretraining | 1.57e+10 | 1.33e+12 | 1.90e+22 | 6*N_active*D (2.4B activated params, V3 report... | NaN | NaN | NaN | reported | [src](https://arxiv.org/abs/2412.19437) | |
| 27 | deepseek-v3 | dsv3-abl-mtp-large-baseline | ablation | pretraining | 2.29e+11 | 5.40e+11 | 6.77e+22 | 6ND (active params) | NaN | NaN | HumanEval (Pass@1) | 44.5 | reported | [src](https://arxiv.org/abs/2412.19437) |
| 28 | deepseek-v3 | dsv3-abl-mtp-large-mtp | ablation | pretraining | 2.29e+11 | 5.40e+11 | 6.77e+22 | 6ND (active params) | NaN | NaN | HumanEval (Pass@1) | 53.7 | reported | [src](https://arxiv.org/abs/2412.19437) |
| 29 | deepseek-v3 | dsv3-abl-auxfree-small-pair | ablation | pretraining | 1.57e+10 | 1.33e+12 | 3.83e+22 | 6ND x 2 (baseline + variant) | NaN | NaN | NaN | reported | [src](https://arxiv.org/abs/2412.19437) | |
| 30 | deepseek-v3 | dsv3-abl-auxfree-large-pair | ablation | pretraining | 2.29e+11 | 5.78e+11 | 1.45e+23 | 6ND x 2 (baseline + variant) | NaN | NaN | HumanEval (Pass@1) aux-loss -> aux-free | NaN | reported | [src](https://arxiv.org/abs/2412.19437) |
| 31 | deepseek-v3 | dsv3-abl-fp8-16b-pair | ablation | pretraining | 1.60e+10 | 1.33e+12 | 3.83e+22 | 6ND x 2 (baseline + variant) | NaN | NaN | NaN | reported | [src](https://arxiv.org/abs/2412.19437) | |
| 32 | deepseek-v3 | dsv3-abl-fp8-230b-pair | ablation | pretraining | 2.30e+11 | 9.00e+11 | 2.27e+23 | 6ND x 2 (baseline + variant) | NaN | NaN | NaN | reported | [src](https://arxiv.org/abs/2412.19437) | |
| 33 | deepseek-v3 | dsv3-abl-balance-1b-seqwise | ablation | pretraining | 1.00e+09 | NaN | 2.258 | NaN | reported | [src](https://arxiv.org/abs/2412.19437) | ||||
| 34 | deepseek-v3 | dsv3-abl-balance-1b-auxfree | ablation | pretraining | 1.00e+09 | NaN | 2.253 | NaN | reported | [src](https://arxiv.org/abs/2412.19437) | ||||
| 35 | deepseek-v3 | dsv3-abl-balance-1b-batchwise | ablation | pretraining | 1.00e+09 | NaN | 2.253 | NaN | reported | [src](https://arxiv.org/abs/2412.19437) | ||||
| 36 | deepseek-v3 | dsv3-abl-expertload-16b-pair | ablation | pretraining | 1.60e+10 | NaN | NaN | NaN | reported | [src](https://arxiv.org/abs/2412.19437) | ||||
| 37 | deepseek-r1 | r1-prep-30b-a100 | ablation | post-training/RL | 3.00e+10 | NaN | NaN | NaN | reported | [src](https://arxiv.org/abs/2501.12948v2) | ||||
| 38 | deepseek-r1 | r1-zero | final | post-training/RL | 6.71e+11 | 101000.0 | NaN | AIME 2024 pass@1 | 71.0 | reported | [src](https://arxiv.org/abs/2501.12948v2) | |||
| 39 | deepseek-r1 | r1-sft-data-creation | final | post-training/RL | 5000.0 | NaN | NaN | reported | [src](https://arxiv.org/abs/2501.12948v2) | |||||
| 40 | deepseek-r1 | r1-final | final | post-training/RL | 6.71e+11 | 41000.0 | NaN | AIME 2024 pass@1 | 79.8 | reported | [src](https://arxiv.org/abs/2501.12948v2) | |||
| 41 | deepseek-r1 | r1-zero-qwen-32b | ablation | post-training/RL | 3.20e+10 | NaN | NaN | AIME 2024 pass@1 | 47.0 | reported | [src](https://arxiv.org/abs/2501.12948) | |||
| 42 | deepseek-r1 | r1-distill-series | final | post-training/RL | NaN | NaN | AIME 2024 pass@1 (Distill-Qwen-32B) | 72.6 | reported | [src](https://arxiv.org/abs/2501.12948) | ||||
| 43 | deepseek-v3.1 | dsv31-continued-pretrain-840b | midtrain | midtraining | 6.71e+11 | 8.39e+11 | 1.90e+23 | 6*N_active*D | 150000.0 | NaN | NaN | derived | [src](https://huggingface.co/deepseek-ai/DeepS... | |
| 44 | deepseek-v3.2 | dsv32exp-dsa-dense-warmup | midtrain | midtraining | 6.71e+11 | 2.10e+09 | 4.66e+20 | 6ND | NaN | NaN | NaN | reported | [src](https://github.com/deepseek-ai/DeepSeek-... | |
| 45 | deepseek-v3.2 | dsv32exp-dsa-sparse-stage | midtrain | midtraining | 6.71e+11 | 9.44e+11 | 2.10e+23 | 6*N_active*D (attention now sparse; rough) | NaN | NaN | NaN | reported | [src](https://github.com/deepseek-ai/DeepSeek-... | |
| 46 | deepseek-v3.2 | dsv32-final-post-training | final | post-training/RL | 6.71e+11 | 300000.0 | NaN | AIME 2025 | 93.1 | derived | [src](https://arxiv.org/abs/2512.02556) | |||
| 47 | deepseek-v3.2 | dsv32-speciale | final | post-training/RL | 6.71e+11 | NaN | NaN | AIME 2025 | 96.0 | reported | [src](https://arxiv.org/abs/2512.02556) | |||
| 48 | deepseek-v4 | dsv4-pro-pretrain | final | pretraining | 1.60e+12 | 3.30e+13 | 9.70e+24 | 6*N_active*D = 6*4.9e10*3.3e13 | NaN | NaN | NaN | derived | [src](https://arxiv.org/abs/2606.19348) | |
| 49 | deepseek-v4 | dsv4-flash-pretrain | final | pretraining | 2.84e+11 | 3.20e+13 | 2.50e+24 | 6*N_active*D | NaN | NaN | NaN | derived | [src](https://arxiv.org/abs/2606.19348) |
Hardware and accounting. V3 trained on 2,048 H800s; the report gives per-stage GPU-hours (2.664M pretraining, 119K context extension, 5K post-training). V2’s report gives per-trillion-token rates (300.6K and 172.8K GPU-hours per T tokens for the dense 67B and the MoE V2), which this chapter uses to derive GPU-hours for the 67B and V2 finals; those rows are flagged derived.
What is not reconstructable. The compute behind architecture and data decisions for every release after the first; any prediction error for the DeepSeek LLM law; active-parameter counts for two V3 ablation models (flagged as guesses); GPU-hours for V4 (33T and 32T tokens, no hours disclosed). Primary hosts were blocked from this environment; text came from DeepSeek’s GitHub-hosted PDFs and GitHub transcriptions of the arXiv papers, marked as such in the claims.