4 Meta Llama
Meta is the closed-weights-process, open-weights-model case: the Llama 3 paper describes a scaling ladder, data-mix experiments and annealing ablations in detail but never counts them, and only Llama 1 discloses total development compute. Working notes with sources are in data/notes/llama.md; 39 verbatim quantitative statements are in the claims table.
4.1 The one disclosed development budget: Llama 1
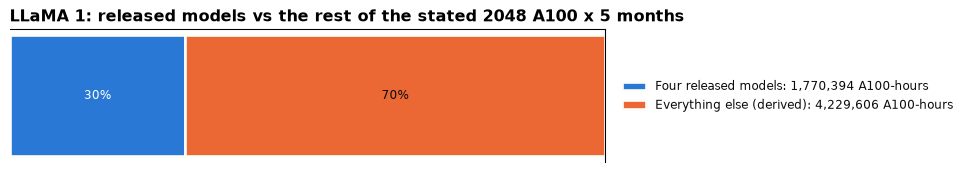
The LLaMA 1 paper estimates the whole project at 2,048 A100s for about five months (2,638 MWh). At the paper’s own throughput that is roughly 6.0M A100-hours, against 1.77M for the four released models. Around 70 percent of Llama 1’s compute went to runs that did not ship. Llama 2, 3 and 4 say nothing comparable.
4.2 Llama 3’s ladder, as far as it is published
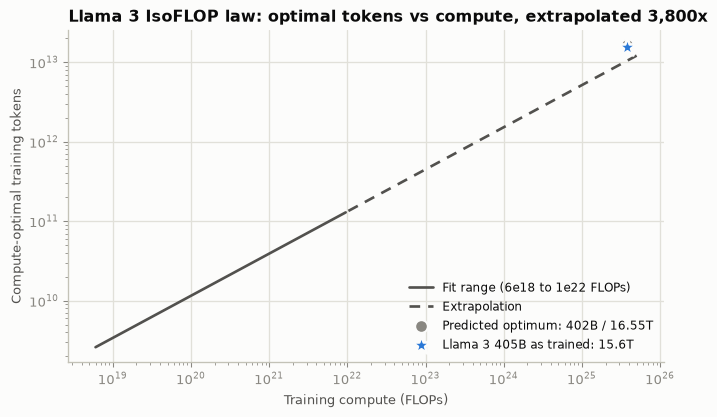
Models of 40M to 16B parameters at budgets from 6e18 to 1e22 FLOPs gave the compute-optimal relation N_opt(C) = A · C^α with α = 0.53 and A = 0.29, which predicted 402B parameters and 16.55T tokens at the 3.8e25 budget; Meta chose 405B and 15.6T. The run count is never stated. The two-stage benchmark prediction (normalised log-likelihood from compute, then a sigmoid to ARC Challenge accuracy) is figure-only.
4.3 Across releases: released models, one benchmark
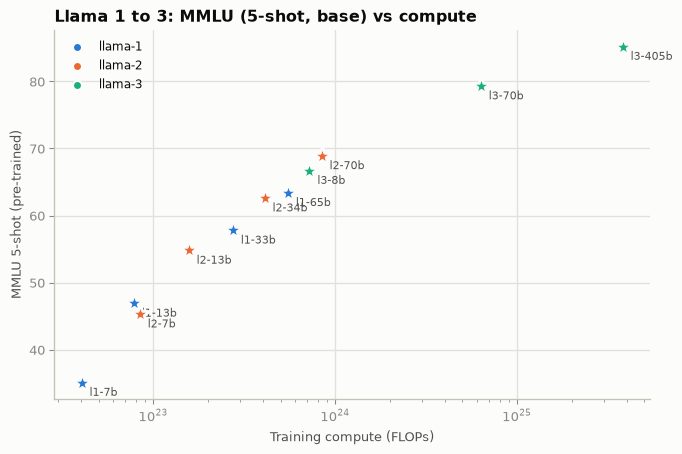
With no experiment runs sized, the cross-release picture is the released models only. Five-shot MMLU on the pre-trained base against 6ND compute, Llama 1 to Llama 3.
4.4 Run sizes, compute split, timeline
4.5 Published scaling experiments
| project | date | stage | intervention | model_sizes | compute_range | metric | fitted_exponent | exponent_source | raw_data_available | source_url | notes | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 0 | llama-3 | 2024-07 | pretraining | IsoFLOP scaling-law ladder: vary model size vs... | 40M-16B params (subset of sizes per budget; co... | 6e18-1e22 FLOPs | negative log-likelihood on held-out validation... | alpha=0.53 (A=0.29) for optimal training token... | numbers_in_text (text: 0.53/0.29; figure legen... | figure_only | [src](https://arxiv.org/abs/2407.21783) | Extrapolation to 3.8e25 FLOPs -> 402B params o... |
| 1 | llama-3 | 2024-07 | pretraining | Two-stage downstream benchmark prediction (ARC... | ladder 40M-16B; Llama 2 7B-70B; target 405B | ~1e19-1e22 (stage 1); Llama 2 models ~8e22-8.4... | normalized NLL per character of correct answer... | not reported (linear and sigmoid coefficients ... | figure_only | figure_only | [src](https://arxiv.org/abs/2407.21783) | 'extrapolates over four orders of magnitude ..... |
| 2 | llama-3 | 2024-07 | pretraining | Data-mix selection via scaling-law experiments... | not stated ('several small models', 'a larger ... | not stated | predicted large-model benchmark performance | figure_only | [src](https://arxiv.org/abs/2407.21783) | No numbers at all are published for these runs... | ||
| 3 | llama-3 | 2024-07 | midtraining | Annealing as data-quality probe: take 50%-trai... | 8B | ~1.9e21 FLOPs per anneal run (derived 6*8e9*40... | downstream benchmark change | numbers_in_text | [src](https://arxiv.org/abs/2407.21783) | Only GSM8k/MATH deltas are given numerically (... | ||
| 4 | llama-3 | 2024-07 | midtraining | Annealing on GSM8k and MATH training sets (fol... | 8B and 405B | not stated | GSM8k and MATH validation accuracy | 8B: +24.0% GSM8k, +6.4% MATH; 405B: negligible | numbers_in_text | numbers_in_text | [src](https://arxiv.org/abs/2407.21783) | Interpreted by authors as evidence the flagshi... |
| 5 | llama-3 | 2024-07 | pretraining | Parallelism/scale configuration of 405B pre-tr... | 405B | 430 / 400 / 380 TFLOPs per GPU; BF16 MFU 43% /... | BF16 Model FLOPs Utilization | numbers_in_text | [src](https://arxiv.org/abs/2407.21783) | MFU drop 43%->41% attributed to lower per-DP-g... | ||
| 6 | llama-3 | 2024-07 | pretraining | Batch-size ramp and LR schedule of flagship (s... | 405B | within the 3.8e25 flagship run | training stability (loss spikes) | numbers_in_text | [src](https://arxiv.org/abs/2407.21783) | 'we observed few loss spikes and did not requi... | ||
| 7 | llama-2 | 2023-07 | pretraining | Model-size series 7B/13B/34B/70B at fixed 2.0T... | 7B, 13B, 34B, 70B | 8.4e22-8.4e23 FLOPs (derived 6ND) | training loss (Figure 5) | none reported | figure_only | [src](https://arxiv.org/abs/2307.09288) | 'after pretraining on 2T Tokens, the models st... | |
| 8 | llama-1 | 2023-02 | pretraining | Model-size series 7B/13B/33B/65B trained on 1.... | 6.7B, 13.0B, 32.5B, 65.2B | 4.0e22-5.5e23 FLOPs (derived 6ND) | training loss vs tokens (Figure 1) | none reported | figure_only | [src](https://arxiv.org/abs/2302.13971) | 'the performance of a 7B model continues to im... | |
| 9 | llama-4 | 2025-04 | pretraining | MetaP hyperparameter-transfer technique (per-l... | Scout 109B/17B active; Maverick 400B/17B activ... | Behemoth: 32K GPUs at 390 TFLOPs/GPU (FP8); to... | not stated | not reported (no MetaP values published) | figure_only | [src](https://ai.meta.com/blog/llama-4-multimo... | Blog only; no technical report. No numbers for... |
4.6 What the lab says about itself
| project | claim | value | unit | source_url | quote | notes | |
|---|---|---|---|---|---|---|---|
| 0 | llama-3 | flagship pre-training compute | 3.8e25 | FLOPs | [src](https://arxiv.org/abs/2407.21783) | our flagship language model was pre-trained us... | Section 1 |
| 1 | llama-3 | scaling-law compute range | 6e18-1e22 | FLOPs | [src](https://arxiv.org/abs/2407.21783) | we construct our scaling laws by pre-training ... | Section 3.2.1 |
| 2 | llama-3 | scaling-law ladder hyperparameters | 2000 warmup steps; LR 2e-4 to 4e-4; batch 250K-4M | various | [src](https://arxiv.org/abs/2407.21783) | we use a cosine learning rate schedule with a ... | Section 3.2.1 |
| 3 | llama-3 | fitted token-scaling exponent | alpha=0.53, A=0.29 | dimensionless | [src](https://arxiv.org/abs/2407.21783) | we assume a power-law relation between compute... | Figure 3 legend (arXiv HTML v3, datacompute.sv... |
| 4 | llama-3 | compute-optimal prediction | 402B params / 16.55T tokens | params / tokens | [src](https://arxiv.org/abs/2407.21783) | Extrapolation of the resulting scaling law to ... | Section 3.2.1 |
| 5 | llama-3 | decision to use 405B | 405B | params | [src](https://arxiv.org/abs/2407.21783) | An important observation is that IsoFLOPs curv... | Section 3.2.1 |
| 6 | llama-3 | two-stage benchmark prediction accuracy | 4 orders of magnitude; slight underestimate | qualitative | [src](https://arxiv.org/abs/2407.21783) | We find this two-step scaling law prediction, ... | ARC Challenge; Figure 4 |
| 7 | llama-3 | data-mix scaling law experiments | several small models per mix | count (vague) | [src](https://arxiv.org/abs/2407.21783) | we perform scaling law experiments in which we... | Section 3.1.2; no counts or sizes |
| 8 | llama-3 | final data mix | 50/25/17/8 | % tokens | [src](https://arxiv.org/abs/2407.21783) | Our final data mix contains roughly 50% of tok... | Section 3.1.2 |
| 9 | llama-3 | annealing effect on 8B | +24.0% GSM8k; +6.4% MATH | % (relative or absolute unclear) | [src](https://arxiv.org/abs/2407.21783) | annealing improved the performance of a pre-tr... | Section 3.1.3 |
| 10 | llama-3 | annealing as data-quality probe | 8B at 50% trained; 40B tokens; 30%/70% | tokens / weight | [src](https://arxiv.org/abs/2407.21783) | We measure the value of such datasets by annea... | Section 3.1.3 |
| 11 | llama-3 | flagship LR schedule | 8e-5 peak; 8000 warmup; 1,200,000 steps; 8e-7 ... | various | [src](https://arxiv.org/abs/2407.21783) | We pre-train Llama 3 405B using AdamW with a p... | Section 3.4.1 |
| 12 | llama-3 | flagship batch-size ramp | 4M -> 8M (after 252M tokens) -> 16M (after 2.8... | tokens/batch | [src](https://arxiv.org/abs/2407.21783) | we use an initial batch size of 4M tokens and ... | Section 3.4.1 |
| 13 | llama-3 | long-context stage tokens | ~800B; six stages 8K->128K | tokens | [src](https://arxiv.org/abs/2407.21783) | In Llama 3 405B pre-training, we increased con... | Section 3.4.2. Sec 2.1 says the 15.6T-token ru... |
| 14 | llama-3 | annealing stage | 40M tokens; LR to 0; Polyak averaging | tokens | [src](https://arxiv.org/abs/2407.21783) | During pre-training on the final 40M tokens, w... | Section 3.4.3 |
| 15 | llama-3 | cluster size | 16K of 24K GPUs | H100 GPUs | [src](https://arxiv.org/abs/2407.21783) | Llama 3 405B is trained on up to 16K H100 GPUs... | Section 3.3.1 |
| 16 | llama-3 | MFU | 38-43% | BF16 MFU | [src](https://arxiv.org/abs/2407.21783) | we achieve an overall BF16 Model FLOPs Utiliza... | Table 4: 8,192 GPUs 430 TFLOPs/GPU 43%; 16,384... |
| 17 | llama-3 | reliability during 54-day snapshot | 466 interruptions (47 planned, 419 unexpected)... | count / % | [src](https://arxiv.org/abs/2407.21783) | During a 54-day snapshot period of pre-trainin... | Section 3.3.4; Table 5 |
| 18 | llama-3 | smaller models over-trained | qualitative | [src](https://arxiv.org/abs/2407.21783) | While our scaling laws suggest our flagship mo... | Section 1 | |
| 19 | llama-3 | total GPU hours (herd) | 39.3M | H100-80GB GPU-hours | [src](https://github.com/meta-llama/llama-mode... | Training utilized a cumulative of 39.3M GPU ho... | Llama 3.1 model card (Jul 23 2024); per-model ... |
| 20 | llama-3 | total GPU hours (Llama 3 April release) | 7.7M | H100-80GB GPU-hours | [src](https://github.com/meta-llama/llama3/blo... | Pretraining utilized a cumulative 7.7M GPU hou... | Llama 3 model card, Model Release Date April 1... |
| 21 | llama-3 | post-training rounds | 6 | rounds | [src](https://arxiv.org/abs/2407.21783) | Following Llama 2, we apply the above methods ... | Section 4.1.6 |
| 22 | llama-3 | code expert continued pre-training | 1T tokens (>85% code) | tokens | [src](https://arxiv.org/abs/2407.21783) | This is accomplished by branching the main pre... | Section 4.3.1 |
| 23 | llama-3 | author count | 559 | authors | [src](https://arxiv.org/abs/2407.21783) | Contributors section of https://arxiv.org/html... | Verified against arXiv HTML v3 (23 Nov 2024) o... |
| 24 | llama-3 | derived training duration | ~72 days | days | [src](https://x.com/EpochAIResearch/status/181... | (Epoch AI) Llama 3.1 405B was trained using a ... | Third-party derivation; snippet only |
| 25 | llama-3 | clusters used for Llama 3 | two 24K-GPU clusters | GPUs | [src](https://engineering.fb.com/2024/03/12/da... | (search snippet) Meta announced two 24k GPU cl... | Engineering blog 2024-03-12; page not directly... |
| 26 | llama-2 | GPU hours | 184320 / 368640 / 1038336 / 1720320; total 331... | A100-80GB GPU-hours | [src](https://arxiv.org/abs/2307.09288) | A cumulative of 3.3M GPU hours of computation ... | Table 2: 7B 184320 400W 31.22; 13B 368640 400W... |
| 27 | llama-2 | training hardware | A100; RSC InfiniBand 400W; production RoCE 350... | [src](https://arxiv.org/abs/2307.09288) | We pretrained our models on Meta's Research Su... | Section 2.2.1 | |
| 28 | llama-2 | no saturation at 2T tokens | 2T | tokens | [src](https://arxiv.org/abs/2307.09288) | Figure 5: Training Loss for Llama 2 models. We... | Figure only; no numeric loss |
| 29 | llama-2 | training dates | Jan 2023 - Jul 2023 | [src](https://github.com/meta-llama/llama/blob... | Llama 2 was trained between January 2023 and J... | Model card | |
| 30 | llama-2 | SFT and preference data | 27,540 SFT; 1,418,091 comparisons | annotations | [src](https://arxiv.org/abs/2307.09288) | We stopped annotating SFT after collecting a t... | Sections 3.1, 3.2; Table 6 |
| 31 | llama-1 | GPU hours | 82,432 / 135,168 / 530,432 / 1,022,362 | A100-80GB GPU-hours | [src](https://arxiv.org/abs/2302.13971) | LLaMA-7B A100-80GB 400W 82,432 36 MWh 14; LLaM... | Table 15 carbon footprint; PUE 1.1; 0.385 kg C... |
| 32 | llama-1 | total development compute | 2048 A100 x ~5 months; 2,638 MWh; 1,015 tCO2eq | [src](https://arxiv.org/abs/2302.13971) | we estimate that we used 2048 A100-80GB for a ... | Section 6; implies ~6.0M GPU-h total vs 1.77M ... | |
| 33 | llama-1 | 65B throughput and duration | 380 tokens/sec/GPU; 21 days | [src](https://arxiv.org/abs/2302.13971) | When training a 65B-parameter model, our code ... | Section 2.4 | |
| 34 | llama-1 | over-training rationale | 7B improves after 1T tokens | tokens | [src](https://arxiv.org/abs/2302.13971) | although Hoffmann et al. (2022) recommends tra... | Section 1 |
| 35 | llama-4 | GPU hours | Scout 5.0M; Maverick 2.38M; total 7.38M | H100-80GB GPU-hours | [src](https://github.com/meta-llama/llama-mode... | Model pre-training utilized a cumulative of 7.... | Model card; release date April 5, 2025 |
| 36 | llama-4 | training tokens | Scout ~40T; Maverick ~22T | tokens | [src](https://github.com/meta-llama/llama-mode... | Llama 4 Scout was pretrained on ~40 trillion t... | Model card |
| 37 | llama-4 | Behemoth throughput | 390 TFLOPs/GPU on 32K GPUs (FP8) | TFLOPs/GPU | [src](https://ai.meta.com/blog/llama-4-multimo... | (blog, via search snippet and mirrors) while p... | Blog not directly fetched; wording confirmed b... |
| 38 | llama-4 | Behemoth size | 288B active; 16 experts; ~2T total | params | [src](https://ai.meta.com/blog/llama-4-multimo... | (blog, via mirrors) Llama 4 Behemoth ... 288B ... |
4.7 Key numbers
| project | run_id | run_type | stage | params_total | tokens | flops | flops_method | gpu_hours | loss | benchmark_name | benchmark_value | confidence | source_url | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 0 | llama-3 | l3-405b-pretrain | final | pretraining | 4.05e+11 | 1.56e+13 | 3.80e+25 | reported in paper (Sec 1); 6*N*D check = 3.79e25 | 30840000.0 | NaN | MMLU (5-shot, pre-trained) | 85.2 | reported | [src](https://arxiv.org/abs/2407.21783 ; https... |
| 1 | llama-3 | l3-405b-longcontext | midtrain | midtraining | 4.05e+11 | 8.00e+11 | 1.90e+24 | derived 6*N*D with N=405e9, D=800e9 | NaN | NaN | NaN | derived | [src](https://arxiv.org/abs/2407.21783) | |
| 2 | llama-3 | l3-405b-anneal | midtrain | midtraining | 4.05e+11 | 4.00e+07 | 9.70e+19 | derived 6*N*D with D=40e6 | NaN | NaN | NaN | reported | [src](https://arxiv.org/abs/2407.21783) | |
| 3 | llama-3 | l3-405b-posttrain | final | post-training/RL | 4.05e+11 | NaN | NaN | MMLU (5-shot, post-trained) | 87.3 | reported | [src](https://arxiv.org/abs/2407.21783) | |||
| 4 | llama-3 | l3-70b-pretrain | final | pretraining | 7.00e+10 | 1.50e+13 | 6.30e+24 | derived 6*N*D with D=15e12 (model card says '1... | 7000000.0 | NaN | MMLU (5-shot, pre-trained) | 79.3 | reported | [src](https://arxiv.org/abs/2407.21783 ; https... |
| 5 | llama-3 | l3-8b-pretrain | final | pretraining | 8.00e+09 | 1.50e+13 | 7.20e+23 | derived 6*N*D with D=15e12 | 1460000.0 | NaN | MMLU (5-shot, pre-trained) | 66.7 | reported | [src](https://arxiv.org/abs/2407.21783 ; https... |
| 6 | llama-3 | l3-code-expert-branch | midtrain | midtraining | 1.00e+12 | NaN | NaN | NaN | reported | [src](https://arxiv.org/abs/2407.21783) | ||||
| 7 | llama-3 | l3-multilingual-expert-branch | midtrain | midtraining | NaN | NaN | NaN | reported | [src](https://arxiv.org/abs/2407.21783) | |||||
| 8 | llama-3 | l3-scaling-ladder | ladder | pretraining | range 6e18 to 1e22 FLOPs per run (reported) | NaN | NaN | NaN | reported | [src](https://arxiv.org/abs/2407.21783) | ||||
| 9 | llama-3 | l3-datamix-scaling-ablations | ablation | pretraining | NaN | NaN | NaN | reported | [src](https://arxiv.org/abs/2407.21783) | |||||
| 10 | llama-3 | l3-anneal-dataquality-ablations-8b | ablation | midtraining | 8.00e+09 | 4.00e+10 | 1.90e+21 | derived 6*N*D per anneal run with N=8e9, D=40e9 | NaN | NaN | NaN | reported | [src](https://arxiv.org/abs/2407.21783) | |
| 11 | llama-3 | l3-anneal-gsm8k-math-8b | ablation | midtraining | 8.00e+09 | NaN | NaN | GSM8k / MATH validation improvement from annea... | NaN | reported | [src](https://arxiv.org/abs/2407.21783) | |||
| 12 | llama-3 | l3-anneal-gsm8k-math-405b | ablation | midtraining | 4.05e+11 | NaN | NaN | GSM8k / MATH improvement from annealing | NaN | reported | [src](https://arxiv.org/abs/2407.21783) | |||
| 13 | llama-3 | l3-405b-mfu-configs | unknown | pretraining | 4.05e+11 | NaN | NaN | NaN | reported | [src](https://arxiv.org/abs/2407.21783) | ||||
| 14 | llama-2 | l2-7b-pretrain | final | pretraining | 7.00e+09 | 2.00e+12 | 8.40e+22 | derived 6*N*D with D=2.0e12 | 184320.0 | NaN | MMLU (5-shot, pre-trained) | 45.3 | reported | [src](https://arxiv.org/abs/2307.09288 ; https... |
| 15 | llama-2 | l2-13b-pretrain | final | pretraining | 1.30e+10 | 2.00e+12 | 1.56e+23 | derived 6*N*D with D=2.0e12 | 368640.0 | NaN | MMLU (5-shot, pre-trained) | 54.8 | reported | [src](https://arxiv.org/abs/2307.09288 ; https... |
| 16 | llama-2 | l2-34b-pretrain | final | pretraining | 3.40e+10 | 2.00e+12 | 4.08e+23 | derived 6*N*D with D=2.0e12 | 1038336.0 | NaN | MMLU (5-shot, pre-trained) | 62.6 | reported | [src](https://arxiv.org/abs/2307.09288 ; https... |
| 17 | llama-2 | l2-70b-pretrain | final | pretraining | 7.00e+10 | 2.00e+12 | 8.40e+23 | derived 6*N*D with D=2.0e12 | 1720320.0 | NaN | MMLU (5-shot, pre-trained) | 68.9 | reported | [src](https://arxiv.org/abs/2307.09288 ; https... |
| 18 | llama-2 | l2-chat-rlhf | final | post-training/RL | 7.00e+09 | NaN | NaN | NaN | reported | [src](https://arxiv.org/abs/2307.09288) | ||||
| 19 | llama-1 | l1-7b-pretrain | final | pretraining | 6.70e+09 | 1.00e+12 | 4.02e+22 | derived 6*N*D | 82432.0 | NaN | MMLU (5-shot) | 35.1 | reported | [src](https://arxiv.org/abs/2302.13971 ; https... |
| 20 | llama-1 | l1-13b-pretrain | final | pretraining | 1.30e+10 | 1.00e+12 | 7.80e+22 | derived 6*N*D | 135168.0 | NaN | MMLU (5-shot) | 46.9 | reported | [src](https://arxiv.org/abs/2302.13971 ; https... |
| 21 | llama-1 | l1-33b-pretrain | final | pretraining | 3.25e+10 | 1.40e+12 | 2.73e+23 | derived 6*N*D | 530432.0 | NaN | MMLU (5-shot) | 57.8 | reported | [src](https://arxiv.org/abs/2302.13971 ; https... |
| 22 | llama-1 | l1-65b-pretrain | final | pretraining | 6.52e+10 | 1.40e+12 | 5.48e+23 | derived 6*N*D | 1022362.0 | NaN | MMLU (5-shot) | 63.4 | reported | [src](https://arxiv.org/abs/2302.13971 ; https... |
| 24 | llama-4 | l4-scout-pretrain | final | pretraining | 1.09e+11 | 4.00e+13 | 4.10e+24 | derived 6*N_active*D with N=17e9, D=40e12 (MoE... | 5000000.0 | NaN | NaN | reported | [src](https://github.com/meta-llama/llama-mode... | |
| 25 | llama-4 | l4-maverick-pretrain | final | pretraining | 4.00e+11 | 2.20e+13 | 2.20e+24 | derived 6*N_active*D with N=17e9, D=22e12 | 2380000.0 | NaN | NaN | reported | [src](https://github.com/meta-llama/llama-mode... | |
| 26 | llama-4 | l4-behemoth-pretrain | unknown | pretraining | 2.00e+12 | 3.00e+13 | 5.20e+25 | derived 6*N_active*D with N=288e9, D=30e12 (lo... | NaN | NaN | NaN | derived | [src](https://ai.meta.com/blog/llama-4-multimo... |
4.8 Narrative
Llama 3 (2024). 405B on 15.6T tokens, 3.8e25 FLOPs, 30.84M H100-hours for the flagship and 39.3M for the herd (from the model card, not the paper). MFU 38 to 43 percent; a 54-day snapshot logged 466 interruptions with over 90 percent effective training time. Development work the paper describes without counting: the IsoFLOP ladder, “several small models” per candidate data mix, annealing 40B tokens on a half-trained 8B as a data-quality probe, and code and multilingual expert branches continued from the main run. The ladder’s share of the flagship budget is a guess in the data (about 0.2 percent) and is flagged as such.
Llama 2 (2023). Four sizes on 2T tokens, 3.31M A100-hours including the unreleased 34B, trained January to July 2023. No ladder or pretraining ablation is described.
Llama 4 (2025). Scout and Maverick (17B active) at 5.0M and 2.38M H100-hours; Behemoth (288B active, about 2T total) on 32K GPUs at 390 TFLOPs per GPU in FP8, unreleased.
Not reconstructable. Any experiment run count or compute for Llama 2 to 4; the two-stage prediction’s coefficients; the ladder’s per-run sizes (read off a figure). Primary sources (arXiv, Meta AI, Hugging Face) were blocked from this environment; text was checked against GitHub-hosted conversions of the papers, and post-trained benchmark tables were omitted where the conversion garbled them.