| project | intervention | model_sizes | metric | raw_data_available | source_url | |
|---|---|---|---|---|---|---|
| 0 | intellect-2 | Async off-policy delay (sync vs 1/2/4-step asy... | 1.5B (R1-Distill-Qwen-1.5B) | mean reward vs step | figure_only | [src](https://storage.googleapis.com/public-te... |
| 1 | intellect-2 | Offline difficulty filtering: keep problems wi... | 7B (R1-Distill-Qwen-7B) | mean reward vs step | figure_only | [src](https://storage.googleapis.com/public-te... |
| 2 | intellect-2 | Two-sided GRPO clipping: upper bound delta on ... | 32B (QwQ-32B); ablations at smaller sizes | loss/grad-norm spikes, collapse | numbers_in_text | [src](https://storage.googleapis.com/public-te... |
| 3 | intellect-2 | Escalating gradient norm / clip-ratio vs model... | small (unspecified) to 32B (QwQ-32B, R1-Distil... | gradient norm, token-prob clip ratio vs step | figure_only | [src](https://storage.googleapis.com/public-te... |
| 4 | intellect-2 | Entropy-loss resurgence as collapse precursor;... | not stated (ablation runs) | entropy loss vs step | figure_only | [src](https://storage.googleapis.com/public-te... |
| 5 | intellect-2 | torch.compile on vs off | 1.5B (and 'regardless of model size') | grad norm and reward vs step | figure_only | [src](https://storage.googleapis.com/public-te... |
| 6 | intellect-2 | Length reward (L1-style, discrete targets) alp... | 1.5B/7B ablations (learned budget following); ... | length penalty vs step | figure_only | [src](https://storage.googleapis.com/public-te... |
| 7 | intellect-2 | Training-vs-inference compute split in decentr... | 32B | FLOPs ratio | numbers_in_text | [src](https://storage.googleapis.com/public-te... |
| 8 | intellect-2 | Overall RL on already-RL'd base (QwQ-32B) | 32B | AIME24/25, LCB v5, GPQA-D, IFEval | numbers_in_text | [src](https://storage.googleapis.com/public-te... |
| 9 | intellect-3 | GSPO vs CISPO under async-8 off-policyness | not stated (INTELLECT-3 pipeline) | reward vs step | figure_only | [src](https://storage.googleapis.com/intellect... |
| 10 | intellect-3 | Double-sided importance-ratio masking vs clipp... | 106B-A12B | run crashes | numbers_in_text | [src](https://storage.googleapis.com/intellect... |
| 11 | intellect-3 | In-flight weight updates + continuous batching | 106B-A12B | step time | numbers_in_text | [src](https://storage.googleapis.com/intellect... |
| 12 | intellect-3 | Online eval every 15 RL steps (benchmark vs step) | 106B-A12B | AIME24/25 avg@32, HLE avg@1, LCB avg@2, GPQA a... | figure_only | [src](https://storage.googleapis.com/intellect... |
| 13 | intellect-3 | Difficulty annotation with small proxy model (... | 4B proxy for 106B target | solve rate | numbers_in_text | [src](https://storage.googleapis.com/intellect... |
| 14 | intellect-3 | Small-model environment validation before addi... | 4B (Qwen3-4B-Instruct-2507) | mean reward vs step | figure_only | [src](https://storage.googleapis.com/intellect... |
| 15 | intellect-1 | SFT sweep (16 runs, 1-3.3B tokens) + 8 DPO run... | 10B | Open LLM Leaderboard benchmarks | numbers_in_text | [src](https://github.com/PrimeIntellect-ai/pri... |
| 16 | reward-hacking-sprints | backdoor-ifeval: hidden keyword reward vs visi... | 1B (Llama-3.2-1B-Instruct) | hidden vs visible reward vs step | figure_only | [src](https://www.primeintellect.ai/blog/rewar... |
| 17 | prime-rl | 1T-scale RL systems (FP8 inference, P/D disagg... | GLM-5 (~1T), Kimi-K2.7-Code, Nemotron-3-Ultra-... | throughput / step time | numbers_in_text | [src](https://www.primeintellect.ai/blog/rl-at... |
6 Prime Intellect (RL pilot)
The pilot chapter for post-training and RL. Prime Intellect’s INTELLECT-2 and INTELLECT-3 reports are unusually explicit that their recipe sections describe “the ablation experiments that led to it”, and both document abandoned paths. That makes them a good test of whether the experiments-to-final-run template works when the “experiments” are RL ablations on small proxy models and the “final run” is a released post-trained model. Working notes with sources are in data/notes/prime-intellect.md; the three technical reports were read in full.
6.1 What the template can and cannot do here
Two things break relative to pretraining. First, there is no compute axis: neither report gives GPU-hours, cluster size for INTELLECT-2, or the compute of any ablation, so every RL step count in the data is read off a figure. Second, there is no fitted scaling relation to test: Prime Intellect’s evidence is that findings on 1.5B, 4B and 7B proxies transfer qualitatively to 32B and 106B, and that benchmark-vs-step curves for INTELLECT-3 showed “no sign of plateauing”. What the record does give is a clean experiment ladder: which ablation, at what size, licensed which decision in the main run.
6.2 The RL experiment ladder
Reading the INTELLECT-2 ladder in order: an async-delay ablation at 1.5B licensed two-step asynchrony; a difficulty-filtering ablation at 7B (reward 0.34 to 0.42 over about 700 steps once problems outside a 12.5 to 50 percent pass@8 band were dropped) licensed the 7B model as a pre-filter for the 285k-task dataset; gradient-norm and entropy-collapse behaviour at 32B led to two-sided clipping and aggressive gradient clipping (adopted), a larger KL weight (rejected as too slow) and disabling torch.compile (adopted). The length reward that worked at 1.5B and 7B did not converge at 32B in the 200 to 350 step main runs and was left unresolved.
INTELLECT-3 added a proxy-model stage: a 4B model validated each new environment and annotated problem difficulty before anything ran at 106B, and algorithms were ablated under deliberately high off-policyness (GSPO collapsed, CISPO climbed from 0.3 to 0.8 over about 400 steps).
6.3 Final run against its base
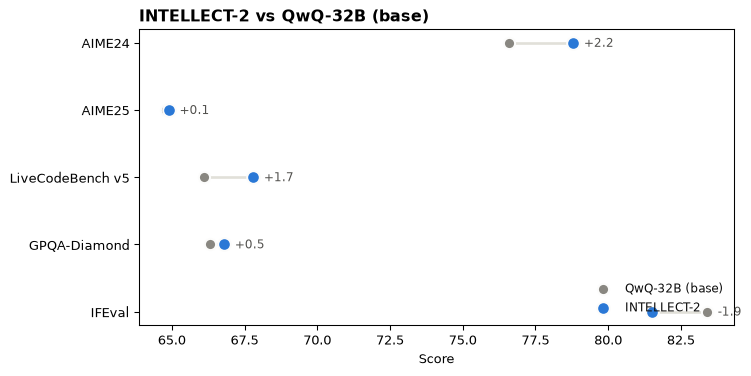
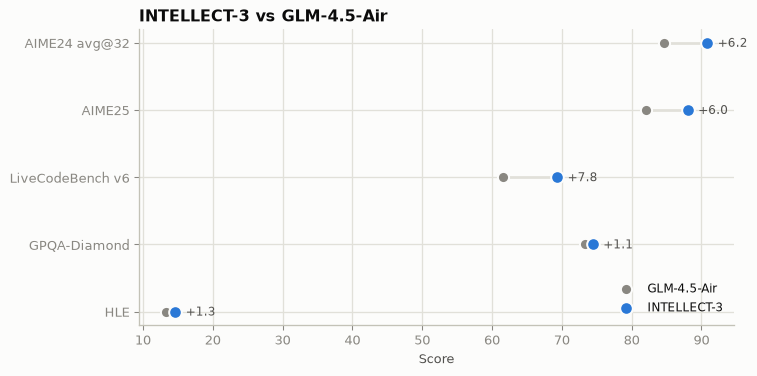
The RL analogue of the final-run star is the released model’s score against the base it started from. INTELLECT-2 started from an already heavily RL-trained base (QwQ-32B) and moved little; INTELLECT-3 started from a base model (GLM-4.5-Air-Base) and moved a lot.
6.4 Run sizes, compute split, timeline
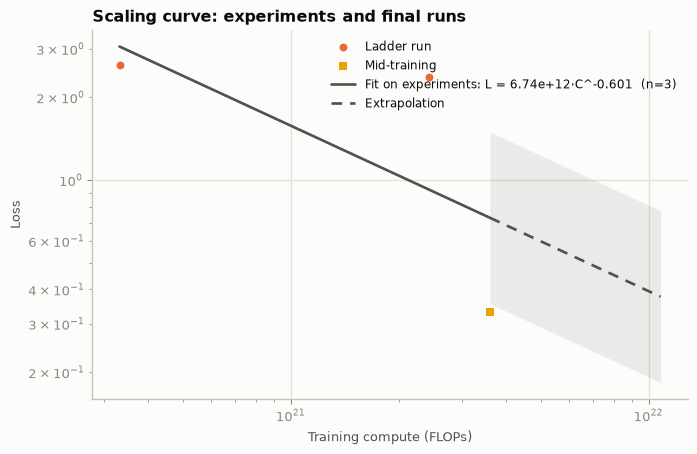
Only INTELLECT-1 (pretraining) and the derived INTELLECT-3 RL figure carry compute, so these standard panels are thin. They are kept so the chapter has the same skeleton as the others.
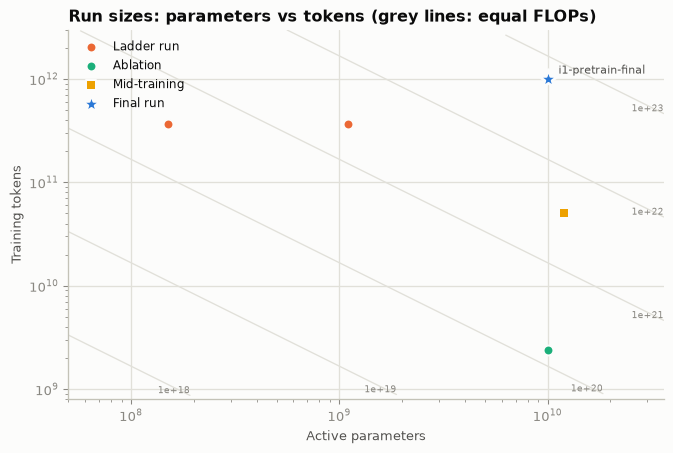
Experimental share of logged FLOPs: 10% (a lower bound: unlogged and failed runs are missing).
6.5 What the lab says about itself
| project | claim | value | unit | source_url | quote | notes | |
|---|---|---|---|---|---|---|---|
| 0 | intellect-2 | AIME24: INTELLECT-2 vs QwQ-32B base | 78.8 vs 76.6 | accuracy | [src](https://storage.googleapis.com/public-te... | final eval table | |
| 1 | intellect-2 | AIME25: INTELLECT-2 vs QwQ-32B base | 64.9 vs 64.8 | accuracy | [src](https://storage.googleapis.com/public-te... | ||
| 2 | intellect-2 | LiveCodeBench v5: INTELLECT-2 vs QwQ-32B base | 67.8 vs 66.1 | accuracy | [src](https://storage.googleapis.com/public-te... | ||
| 3 | intellect-2 | GPQA-Diamond: INTELLECT-2 vs QwQ-32B base | 66.8 vs 66.3 | accuracy | [src](https://storage.googleapis.com/public-te... | ||
| 4 | intellect-2 | IFEval: INTELLECT-2 vs QwQ-32B base | 81.5 vs 83.4 | accuracy | [src](https://storage.googleapis.com/public-te... | ||
| 5 | intellect-2 | Inference to training FLOPs ratio in decentral... | 4.5 | ratio | [src](https://storage.googleapis.com/public-te... | stated in report | |
| 6 | intellect-2 | Rollouts per RL step | 4096 | rollouts | [src](https://storage.googleapis.com/public-te... | 256 prompts x 16 samples | |
| 7 | intellect-2 | Duration of all INTELLECT-2 runs | 2 | weeks | [src](https://storage.googleapis.com/public-te... | "over the duration of two weeks" | training cluster size not disclosed; 18 comput... |
| 8 | intellect-3 | AIME24 avg@32: INTELLECT-3 vs GLM-4.5-Air | 90.8 vs 84.6 | accuracy | [src](https://storage.googleapis.com/intellect... | ||
| 9 | intellect-3 | AIME25: INTELLECT-3 vs GLM-4.5-Air | 88.0 vs 82.0 | accuracy | [src](https://storage.googleapis.com/intellect... | ||
| 10 | intellect-3 | LiveCodeBench v6: INTELLECT-3 vs GLM-4.5-Air | 69.3 vs 61.5 | accuracy | [src](https://storage.googleapis.com/intellect... | ||
| 11 | intellect-3 | GPQA-Diamond: INTELLECT-3 vs GLM-4.5-Air | 74.4 vs 73.3 | accuracy | [src](https://storage.googleapis.com/intellect... | ||
| 12 | intellect-3 | HLE: INTELLECT-3 vs GLM-4.5-Air | 14.6 vs 13.3 | accuracy | [src](https://storage.googleapis.com/intellect... | ||
| 13 | intellect-3 | Cluster and duration for SFT+RL including abla... | 512 H200, 2 months | [src](https://storage.googleapis.com/intellect... | "both stages, including multiple ablations, we... | ||
| 14 | intellect-3 | RL step time at 65,536 context on 16 train + 4... | 1500 | seconds | [src](https://storage.googleapis.com/intellect... | without in-flight weight updates >2x |
6.6 Key numbers
| project | run_id | run_type | stage | params_total | tokens | flops | flops_method | gpu_hours | loss | benchmark_name | benchmark_value | confidence | source_url | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 0 | intellect-1 | i1-pretrain-final | final | pretraining | 1.00e+10 | 1.00e+12 | 6.00e+22 | 6*N*D with N=10e9 D=1e12 (derived) | 44000.0 | NaN | MMLU 5-shot | 37.50 | derived | [src](https://github.com/PrimeIntellect-ai/pri... |
| 1 | intellect-1 | i1-post-sft-sweep | ablation | post-training/RL | 1.00e+10 | 2.40e+09 | 1.44e+20 | 6ND | NaN | NaN | NaN | reported | [src](https://github.com/PrimeIntellect-ai/pri... | |
| 2 | intellect-1 | i1-post-dpo-sweep | ablation | post-training/RL | 1.00e+10 | NaN | NaN | NaN | reported | [src](https://github.com/PrimeIntellect-ai/pri... | ||||
| 3 | intellect-1 | i1-instruct-final | final | post-training/RL | 1.00e+10 | NaN | NaN | MMLU 5-shot | 49.89 | reported | [src](https://github.com/PrimeIntellect-ai/pri... | |||
| 4 | opendiloco | odl-1b-precursor | ladder | pretraining | 1.10e+09 | 3.69e+11 | 2.44e+21 | 6ND derived | NaN | 2.376 | NaN | reported | [src](https://github.com/PrimeIntellect-ai/Ope... | |
| 5 | opendiloco | odl-150m-precursor | ladder | pretraining | 1.50e+08 | 3.69e+11 | 3.32e+20 | 6ND derived | NaN | 2.620 | NaN | reported | [src](https://github.com/PrimeIntellect-ai/Ope... | |
| 6 | intellect-2 | i2-target-long-final | final | post-training/RL | 3.20e+10 | NaN | 0.675 | AIME24 | 78.80 | guess | [src](https://storage.googleapis.com/public-te... | |||
| 7 | intellect-2 | i2-target-short | ablation | post-training/RL | 3.20e+10 | NaN | 0.640 | NaN | guess | [src](https://storage.googleapis.com/public-te... | ||||
| 8 | intellect-2 | i2-abl-async-1.5b | ablation | post-training/RL | 1.50e+09 | NaN | 0.450 | NaN | guess | [src](https://storage.googleapis.com/public-te... | ||||
| 9 | intellect-2 | i2-abl-offline-filter-7b | ablation | post-training/RL | 7.00e+09 | NaN | 0.420 | NaN | guess | [src](https://storage.googleapis.com/public-te... | ||||
| 10 | intellect-2 | i2-abl-gradnorm-scale | aborted | post-training/RL | 3.20e+10 | NaN | NaN | NaN | reported | [src](https://storage.googleapis.com/public-te... | ||||
| 11 | intellect-2 | i2-abl-torchcompile-1.5b | aborted | post-training/RL | 1.50e+09 | NaN | NaN | NaN | reported | [src](https://storage.googleapis.com/public-te... | ||||
| 12 | intellect-3 | i3-sft-stage1-general | midtrain | post-training/RL | 1.06e+11 | 5.00e+10 | 3.60e+21 | 6ND | NaN | 0.330 | NaN | guess | [src](https://storage.googleapis.com/intellect... | |
| 13 | intellect-3 | i3-sft-stage2-agentic | midtrain | post-training/RL | 1.06e+11 | NaN | 0.200 | NaN | reported | [src](https://storage.googleapis.com/intellect... | ||||
| 14 | intellect-3 | i3-rl-final | final | post-training/RL | 1.06e+11 | 120000.0 | NaN | AIME24 avg@32 | 90.80 | guess | [src](https://storage.googleapis.com/intellect... | |||
| 15 | intellect-3 | i3-abl-gspo-vs-cispo | ablation | post-training/RL | NaN | 0.800 | NaN | guess | [src](https://storage.googleapis.com/intellect... | |||||
| 16 | intellect-3 | i3-deepdive-validation-qwen3-4b | ablation | post-training/RL | 4.00e+09 | NaN | 0.720 | NaN | reported | [src](https://storage.googleapis.com/intellect... | ||||
| 17 | intellect-3.1 | i31-rl-config | final | post-training/RL | 1.06e+11 | NaN | NaN | NaN | reported | [src](https://github.com/PrimeIntellect-ai/pri... | ||||
| 18 | swe-ablations | glm45air-scaleswe-config | ablation | post-training/RL | 1.06e+11 | NaN | NaN | NaN | reported | [src](https://github.com/PrimeIntellect-ai/pri... |
6.7 Narrative
Lab shape. Three flagship runs about six months apart, moving from donated decentralised compute (INTELLECT-1: up to 112 H100s from 30 contributors over 42 days) to a trusted training cluster plus a permissionless inference swarm (INTELLECT-2: all runs “over the duration of two weeks”) to a centralised 512-H200 cluster (INTELLECT-3: SFT and RL “including multiple ablations over the course of two months”). Author counts grew from 12 to 13 to 22.
Compute that is not published. INTELLECT-2’s training-cluster size, GPU-hours and cost; the number of ablation runs for either RL project; any development-vs-final split. The derived figures in the data (about 1.2e5 H200-hours for the INTELLECT-3 RL run, up to about 7.5e5 for the whole two-month programme) come from node counts, step times and step counts, with the method in each row. The report does state one compute ratio: inference to training FLOPs of about 4.5 to 1 in decentralised RL.
Implication for the template. For RL labs the reconstructable object is the ladder of decisions, not a curve. The chapter template should carry a decision-ladder table as a standard section for Part II, and treat reward-vs-step figures as figure_only evidence unless a lab publishes W&B exports (Prime Intellect’s are private).