3 Ai2 OLMo
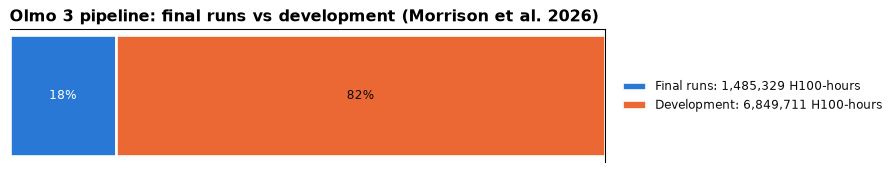
Ai2 publishes data, code, recipes, W&B logs, and intermediate checkpoints for OLMo 2 and OLMo 3, plus a model-ladder paper on predicting task performance from small runs. Two accounting papers by Morrison et al. give the development vs. final-run split directly: roughly 50/50 for the OLMo 2 era (ICLR 2025) and 82/18 for the whole Olmo 3 pipeline (2026). Working notes with sources are in data/notes/olmo.md.
3.1 The number that matters: development vs. final-run compute
Morrison et al. (2026) account for the entire Olmo 3 pipeline (7B and 32B, Instruct and Think). Of 8.34M H100-hours, development (experimentation, failed runs, ablations, synthetic data) took 6.85M and the final runs 1.49M. That is an experiment-to-final ratio near 4.6 to 1, up from about 1 to 1 in their OLMo 2-era paper.
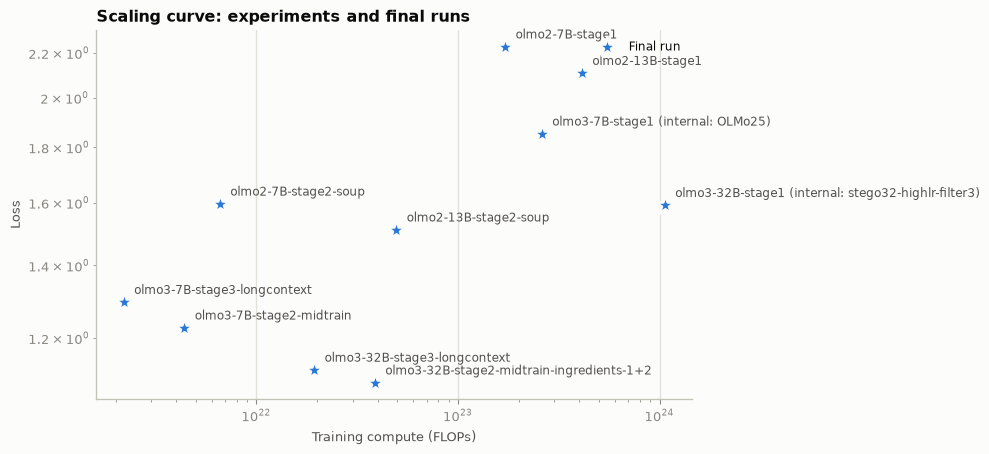
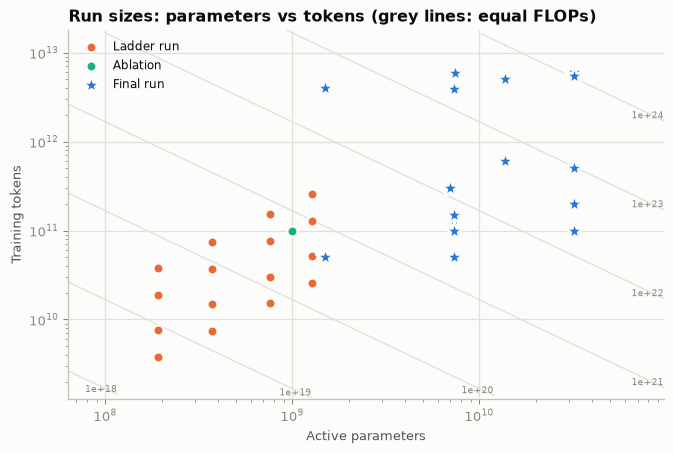
The rows below are the runs we can reconstruct individually. Final-run losses are pulled from Ai2’s public W&B projects (data/losses/ai2-olmo/, stage-1 runs stitched from 11 to 75 restart segments each). The loss column is the training cross-entropy at the end of each stage (median of the last 20 logged points), the only loss both generations log; Olmo 3 stage 1 also logs in-loop held-out losses, and those are the comparable numbers: c4_en CE 2.469 (7B, 5.93T) and 2.301 (32B, 5.70T), Pile 1.776 and 1.639. Training loss is on the training mix, so OLMo 2 (Dolma) and Olmo 3 (Dolma 3) stage-1 values, 2.23 / 2.11 and 1.85 / 1.59, are not one curve, and the midtraining and long-context stages read lower still because the anneal mixes are easier. The panel therefore draws points without a fitted law, and the ladder rows still carry no loss (the ai2-llm/olmo-ladder project is private); the run-size map shows the ladder and the released models on the parameters-vs-tokens plane.
3.2 Run sizes, compute split, timeline
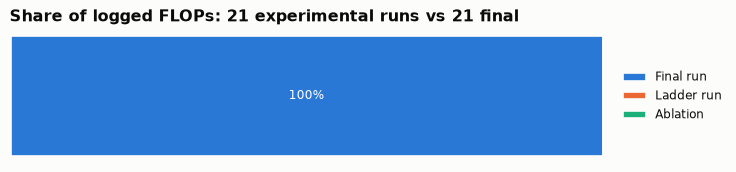
Experimental share of logged FLOPs: 0% (a lower bound: unlogged and failed runs are missing).
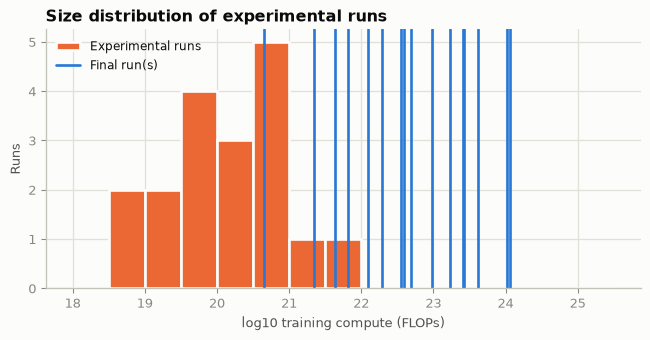
The logged-compute split above counts only runs we have individually, by 6ND FLOPs: the 16 ladder runs are about 1% of the compute of the two OLMo 2 targets they predicted, and the ablation series have no sizes attached, so the per-run picture shows a final-run-dominated budget. The lab’s own accounting, which includes everything, says the opposite. The gap between those two bars is the survivorship problem in one picture.
3.3 Published scaling experiments
| project | date | stage | intervention | model_sizes | compute_range | metric | fitted_exponent | exponent_source | raw_data_available | source_url | notes | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 0 | olmo-ladder | 2024-12 | pretraining | Model ladder: 4 sizes x 4 Chinchilla multiples... | 190M,370M,760M,1.3B (non-embedding) | ~1% of the compute of the targets (7B-4T, 13B-... | Task loss (per-task CE on correct continuation... | Per-task A,B,alpha,beta,E fitted (values in pa... | paper tables | logs | [src](https://arxiv.org/abs/2412.04403) | Prediction error on 7B-4T and 13B-5T: <2 abs. ... |
| 1 | olmo2 | 2024-11 | pretraining | Architecture/stability: RMSNorm with reordered... | 1B (ablation); 7B (stability comparison) | not stated | Loss spikes; L2 gradient-norm growth and spiki... | figure_only | [src](https://arxiv.org/abs/2501.00656) | Neither reordered norm nor QK-norm alone impro... | ||
| 2 | olmo2 | 2024-11 | midtraining | Microannealing: 19 anneal runs testing individ... | not stated (likely 7B) | 130B tokens total (< 3 x 50B full anneals) | OLMES downstream accuracy after anneal | numbers_in_text | [src](https://arxiv.org/abs/2501.00656) | Effects found to persist when sources mixed. | ||
| 3 | olmo2 | 2024-11 | midtraining | Anneal budget (50B/100B/300B) and model soupin... | 7B,13B,32B | 7B: 3x50B; 13B: 3x100B+1x300B; 32B: 2x100B+1x300B | Downstream evals of souped vs individual check... | numbers_in_text | [src](https://github.com/allenai/OLMo-core/blo... | Souping consistently beat individual checkpoin... | ||
| 4 | olmo2 | 2025-03 | pretraining | Compute-accounting of the OLMo 2 development p... | 20M to 13B | Models trained on up to 5.6T tokens; total 493... | Energy / carbon / water; development share of ... | numbers_in_text | [src](https://arxiv.org/abs/2503.05804) | Development (hyperparameter tuning, ablations ... | ||
| 5 | olmo3 | 2025-11 | midtraining | Microanneals: 5B target-source + 5B web (10B) ... | not stated | 10B tokens per microanneal; count not stated | Base-eval deltas vs web-only baseline | figure_only | [src](https://arxiv.org/abs/2512.13961) | Part of two-part framework: lightweight distri... | ||
| 6 | olmo3 | 2025-11 | midtraining | Integration tests: full 100B midtraining annea... | 7B (Olmo 3 7B base checkpoint) | 100B tokens per test | Base quality and post-trainability (SFT/RL) of... | figure_only | [src](https://arxiv.org/abs/2512.13961) | Final midtraining mixes: OLMo-midtraining-mix-... | ||
| 7 | olmo3 | 2025-11 | pretraining | Architecture: 8192 pretraining context (vs 409... | 7B,32B | ablation scale not stated | Throughput and downstream evals | figure_only | [src](https://arxiv.org/abs/2512.13961) | Ablation details not retrieved. | ||
| 8 | olmo3 | 2025 | pretraining | Run management: 7B pretraining schedule extend... | 7B,32B | ~196B 32B tokens (~0.4e22 FLOPs) trained past ... | n/a | logs | [src](https://github.com/allenai/OLMo-core/blo... | From official scripts OLMo-3-1025-7B-pretrain-... | ||
| 9 | olmo3 | 2026-05 | post-training/RL | Compute-accounting of full Olmo 3 pipeline (Mo... | 7B,32B (Instruct, Think) | 8.34M GPU-h total; 6.85M development (82.2%); ... | GPU-hours, energy, carbon, water per stage | numbers_in_text | [src](https://arxiv.org/abs/2605.01158) | Think post-training 17x Instruct energy (32B: ... | ||
| 10 | olmo-hybrid | 2026-04 | pretraining | Chinchilla-style scaling laws for transformer ... | 7 sizes (values not retrieved) x D/N in {10,20... | Compute-optimal projections evaluated 1e18-1e2... | Mean of 11 held-out validation CE losses (C4, ... | alpha, beta statistically indistinguishable ac... | paper text/tables (via search summaries) | numbers_in_text | [src](https://arxiv.org/abs/2604.03444) | Implied token savings 1.3-1.9x from 1B to 70B;... |
| 11 | olmo-hybrid | 2026-03 | pretraining | 1B-scale architecture sweep before 7B: hybrid ... | 1B | not stated | Bits-per-byte on evaluation slices | figure_only | [src](https://allenai.org/blog/olmohybrid) | Ordering: hybrid GDN > pure GDN > transformer ... |
3.4 What the lab says about itself
| project | claim | value | unit | source_url | quote | notes | |
|---|---|---|---|---|---|---|---|
| 0 | olmo3 | olmo3-all-development-aggregate: GPU-hours | 6.849711e6 | H100-hours | [src](https://arxiv.org/abs/2605.01158) | Total ... Dev 6,849,711 (Table 5) | Aggregate, not a single run. Dev GPU-h by stag... |
| 1 | olmo3 | olmo3-all-final-runs-aggregate: GPU-hours | 1.485329e6 | H100-hours | [src](https://arxiv.org/abs/2605.01158) | Total (final runs) 1,485,329 | Reported directly in https://arxiv.org/html/26... |
| 2 | olmo2 | olmo2-development-aggregate: GPU-hours | 6.8e5 | GPU-hours | [src](https://arxiv.org/abs/2503.05804) | Table 1: development total 680k GPU hours, 813... | Morrison et al. 2025 (OLMo 2-era accounting), ... |
3.5 Key numbers
| project | run_id | run_type | stage | params_total | tokens | flops | flops_method | gpu_hours | loss | benchmark_name | benchmark_value | confidence | source_url | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 0 | olmo2 | olmo2-1B-stage1 | final | pretraining | 1.50e+09 | 4.00e+12 | 3.60e+22 | 6ND derived | NaN | NaN | NaN | reported | [src](https://github.com/allenai/OLMo/blob/mai... | |
| 1 | olmo2 | olmo2-1B-stage2 | final | midtraining | 1.50e+09 | 5.00e+10 | 4.50e+20 | 6ND derived | NaN | NaN | NaN | reported | [src](https://github.com/allenai/OLMo/blob/mai... | |
| 2 | olmo2 | olmo2-7B-stage1 | final | pretraining | 7.30e+09 | 3.90e+12 | 1.71e+23 | 6ND derived | NaN | 2.2297 | NaN | reported | [src](https://arxiv.org/abs/2501.00656) | |
| 3 | olmo2 | olmo2-7B-stage2-soup | final | midtraining | 7.30e+09 | 1.50e+11 | 6.57e+21 | 6ND derived (3 seeds x 50B) | NaN | 1.5966 | MMLU | 63.7 | reported | [src](https://arxiv.org/abs/2501.00656) |
| 4 | olmo2 | olmo2-13B-stage1 | final | pretraining | 1.37e+10 | 5.00e+12 | 4.11e+23 | 6ND derived | NaN | 2.1078 | NaN | reported | [src](https://arxiv.org/abs/2501.00656) | |
| 5 | olmo2 | olmo2-13B-stage2-soup | final | midtraining | 1.37e+10 | 6.00e+11 | 4.93e+22 | 6ND derived (3x100B + 1x300B) | NaN | 1.5110 | MMLU | 67.5 | reported | [src](https://arxiv.org/abs/2501.00656) |
| 6 | olmo2 | olmo2-32B-stage1 (peteish32) | final | pretraining | 3.22e+10 | 6.06e+12 | 1.17e+24 | 6ND derived | 930000.0 | NaN | NaN | derived | [src](https://github.com/allenai/OLMo-core/blo... | |
| 7 | olmo2 | olmo2-32B-stage2-soup | final | midtraining | 3.22e+10 | 5.00e+11 | 9.66e+22 | 6ND derived (100B seed1110 + 100B seed2662 + 3... | NaN | NaN | MMLU | 74.9 | reported | [src](https://github.com/allenai/OLMo-core/blo... |
| 8 | olmo3 | olmo3-7B-stage1 (internal: OLMo25) | final | pretraining | 7.30e+09 | 5.93e+12 | 2.60e+23 | 6ND derived | 234475.0 | 1.8528 | NaN | reported | [src](https://github.com/allenai/OLMo-core/blo... | |
| 9 | olmo3 | olmo3-7B-stage2-midtrain | final | midtraining | 7.30e+09 | 1.00e+11 | 4.38e+21 | 6ND derived | 4848.0 | 1.2268 | NaN | reported | [src](https://github.com/allenai/OLMo-core/blo... | |
| 10 | olmo3 | olmo3-7B-stage3-longcontext | final | midtraining | 7.30e+09 | 5.00e+10 | 2.19e+21 | 6ND derived | 4781.0 | 1.2955 | MMLU (base) | 66.9 | reported | [src](https://github.com/allenai/OLMo-core/blo... |
| 11 | olmo3 | olmo3-32B-stage1 (internal: stego32-highlr-fil... | final | pretraining | 3.22e+10 | 5.50e+12 | 1.06e+24 | 6ND derived (tokens actually consumed by branc... | 1050287.0 | 1.5918 | NaN | reported | [src](https://github.com/allenai/OLMo-core/blo... | |
| 12 | olmo3 | olmo3-32B-stage2-midtrain-ingredients-1+2 | final | midtraining | 3.22e+10 | 2.00e+11 | 3.86e+22 | 6ND derived (2 x 100B) | 29058.0 | 1.0916 | NaN | reported | [src](https://github.com/allenai/OLMo-core/blo... | |
| 13 | olmo3 | olmo3-7B-Think-posttrain (DPO+RLVR) | final | post-training/RL | 7.30e+09 | 10000.0 | NaN | NaN | reported | [src](https://arxiv.org/abs/2605.01158) | ||||
| 14 | olmo3 | olmo3-7B-Instruct-posttrain (SFT+DPO+RLVR) | final | post-training/RL | 7.30e+09 | 4200.0 | NaN | NaN | reported | [src](https://arxiv.org/abs/2605.01158) | ||||
| 15 | olmo3 | olmo3-32B-Instruct-posttrain | final | post-training/RL | 3.22e+10 | 7100.0 | NaN | NaN | reported | [src](https://arxiv.org/abs/2605.01158) | ||||
| 16 | olmo3 | olmo3.1-32B-Think-extended-RL | final | post-training/RL | 3.22e+10 | 110000.0 | NaN | AIME 2025 delta | 5.6 | derived | [src](https://huggingface.co/allenai/Olmo-3.1-... | |||
| 17 | olmo-hybrid | olmo-hybrid-7B-stage1 | final | pretraining | 7.43e+09 | 5.93e+12 | 2.64e+23 | 6ND derived | NaN | NaN | NaN | reported | [src](https://github.com/allenai/OLMo-core/blo... | |
| 18 | olmo-hybrid | olmo-hybrid-7B-stage2+3 | final | midtraining | 7.00e+09 | 3.00e+11 | 1.26e+22 | 6ND derived (2x100B midtrain souped + 100B lon... | NaN | NaN | NaN | reported | [src](https://github.com/allenai/OLMo-core/blo... | |
| 19 | olmo-ladder | ladder-190M-1xC | ladder | pretraining | 1.90e+08 | 3.81e+09 | 4.35e+18 | 6ND derived; D = 20*N*multiple (Chinchilla xC) | NaN | NaN | NaN | reported | [src](https://arxiv.org/abs/2412.04403) | |
| 20 | olmo-ladder | ladder-190M-2xC | ladder | pretraining | 1.90e+08 | 7.61e+09 | 8.70e+18 | 6ND derived; D = 20*N*multiple (Chinchilla xC) | NaN | NaN | NaN | reported | [src](https://arxiv.org/abs/2412.04403) | |
| 21 | olmo-ladder | ladder-190M-5xC | ladder | pretraining | 1.90e+08 | 1.90e+10 | 2.17e+19 | 6ND derived; D = 20*N*multiple (Chinchilla xC) | NaN | NaN | NaN | reported | [src](https://arxiv.org/abs/2412.04403) | |
| 22 | olmo-ladder | ladder-190M-10xC | ladder | pretraining | 1.90e+08 | 3.81e+10 | 4.35e+19 | 6ND derived; D = 20*N*multiple (Chinchilla xC) | NaN | NaN | NaN | reported | [src](https://arxiv.org/abs/2412.04403) | |
| 23 | olmo-ladder | ladder-370M-1xC | ladder | pretraining | 3.71e+08 | 7.43e+09 | 1.65e+19 | 6ND derived; D = 20*N*multiple (Chinchilla xC) | NaN | NaN | NaN | reported | [src](https://arxiv.org/abs/2412.04403) | |
| 24 | olmo-ladder | ladder-370M-2xC | ladder | pretraining | 3.71e+08 | 1.48e+10 | 3.31e+19 | 6ND derived; D = 20*N*multiple (Chinchilla xC) | NaN | NaN | NaN | reported | [src](https://arxiv.org/abs/2412.04403) | |
| 25 | olmo-ladder | ladder-370M-5xC | ladder | pretraining | 3.71e+08 | 3.71e+10 | 8.27e+19 | 6ND derived; D = 20*N*multiple (Chinchilla xC) | NaN | NaN | NaN | reported | [src](https://arxiv.org/abs/2412.04403) | |
| 26 | olmo-ladder | ladder-370M-10xC | ladder | pretraining | 3.71e+08 | 7.43e+10 | 1.65e+20 | 6ND derived; D = 20*N*multiple (Chinchilla xC) | NaN | NaN | NaN | reported | [src](https://arxiv.org/abs/2412.04403) | |
| 27 | olmo-ladder | ladder-760M-1xC | ladder | pretraining | 7.58e+08 | 1.52e+10 | 6.90e+19 | 6ND derived; D = 20*N*multiple (Chinchilla xC) | NaN | NaN | NaN | reported | [src](https://arxiv.org/abs/2412.04403) | |
| 28 | olmo-ladder | ladder-760M-2xC | ladder | pretraining | 7.58e+08 | 3.03e+10 | 1.38e+20 | 6ND derived; D = 20*N*multiple (Chinchilla xC) | NaN | NaN | NaN | reported | [src](https://arxiv.org/abs/2412.04403) | |
| 29 | olmo-ladder | ladder-760M-5xC | ladder | pretraining | 7.58e+08 | 7.58e+10 | 3.45e+20 | 6ND derived; D = 20*N*multiple (Chinchilla xC) | NaN | NaN | NaN | reported | [src](https://arxiv.org/abs/2412.04403) | |
| 30 | olmo-ladder | ladder-760M-10xC | ladder | pretraining | 7.58e+08 | 1.52e+11 | 6.90e+20 | 6ND derived; D = 20*N*multiple (Chinchilla xC) | NaN | NaN | NaN | reported | [src](https://arxiv.org/abs/2412.04403) | |
| 31 | olmo-ladder | ladder-1.3B-1xC | ladder | pretraining | 1.28e+09 | 2.56e+10 | 1.96e+20 | 6ND derived; D = 20*N*multiple (Chinchilla xC) | NaN | NaN | NaN | reported | [src](https://arxiv.org/abs/2412.04403) | |
| 32 | olmo-ladder | ladder-1.3B-2xC | ladder | pretraining | 1.28e+09 | 5.12e+10 | 3.93e+20 | 6ND derived; D = 20*N*multiple (Chinchilla xC) | NaN | NaN | NaN | reported | [src](https://arxiv.org/abs/2412.04403) | |
| 33 | olmo-ladder | ladder-1.3B-5xC | ladder | pretraining | 1.28e+09 | 1.28e+11 | 9.82e+20 | 6ND derived; D = 20*N*multiple (Chinchilla xC) | NaN | NaN | NaN | reported | [src](https://arxiv.org/abs/2412.04403) | |
| 34 | olmo-ladder | ladder-1.3B-10xC | ladder | pretraining | 1.28e+09 | 2.56e+11 | 1.96e+21 | 6ND derived; D = 20*N*multiple (Chinchilla xC) | NaN | NaN | NaN | reported | [src](https://arxiv.org/abs/2412.04403) | |
| 35 | olmo2 | olmo2-microanneals-series | ablation | midtraining | 7.30e+09 | 1.30e+11 | 5.69e+21 | 6ND | NaN | NaN | NaN | reported | [src](https://arxiv.org/abs/2501.00656) | |
| 36 | olmo2 | olmo2-1B-architecture-ablations | ablation | pretraining | 1.00e+09 | NaN | NaN | NaN | reported | [src](https://arxiv.org/abs/2501.00656) | ||||
| 37 | olmo3 | olmo3-microanneal-template | ablation | midtraining | 1.00e+10 | NaN | NaN | NaN | reported | [src](https://arxiv.org/abs/2512.13961) | ||||
| 38 | olmo3 | olmo3-integration-test-template | ablation | midtraining | 1.00e+11 | NaN | NaN | NaN | reported | [src](https://arxiv.org/abs/2512.13961) | ||||
| 39 | olmo-hybrid | olmo-hybrid-1B-scale-experiments | ablation | pretraining | 1.00e+09 | 1.00e+11 | 6.00e+20 | 6ND | NaN | NaN | NaN | reported | [src](https://allenai.org/blog/olmohybrid) | |
| 40 | olmo3 | olmo3-32B-stage3-longcontext | final | midtraining | 3.22e+10 | 1.00e+11 | 1.93e+22 | 6ND derived | 23497.0 | 1.1216 | MMLU (base) | 76.2 | reported | [src](https://github.com/allenai/OLMo-core/blo... |
| 41 | olmo3 | olmo3-32B-Think-posttrain (DPO+RLVR) | final | post-training/RL | 3.22e+10 | 96561.0 | NaN | MATH; MMLU | 96.1 | reported | [src](https://arxiv.org/abs/2605.01158) |
3.6 Narrative
Process. The OLMo 2 development pattern: architecture and stability changes ablated at 1B, 19 “microanneal” runs totalling 130B tokens to test individual data sources, then final stage-1 runs (1 to 1.2 epochs) and several stage-2 anneals weight-averaged into the released model. Olmo 3 formalised this into per-source microanneals (5B target tokens plus 5B web) feeding “integration tests” (full 100B midtraining anneals on candidate mixes).
Ladder. Bhagia et al. (2024) trained 16 ladder models (190M, 370M, 760M, 1.3B, each at 1x, 2x, 5x, 10x Chinchilla tokens) and predicted OLMo 2 7B-4T and 13B-5T task accuracy within about 2 points on four tasks and about 4 points averaged over eight. The ladder cost about 1% of the targets’ compute.
Run management visible in the scripts. The official training scripts show decisions the papers do not: the Olmo 3 7B schedule was extended from 5T to 7T tokens mid-run and then hard-stopped at one epoch (5.93T); the 32B midtraining branched at 5.50T while pretraining ran on to 5.70T, so about 196B tokens of 32B pretraining were not used by the released model.
Not yet reconstructable. Per-task fitted coefficients from the ladder paper; the split of the 6.85M development hours across pretraining, midtraining, post-training and synthetic data; OLMo 2 7B and 13B GPU-hours; OLMo 2 32B losses (comet.ml, key-gated) and the ladder losses (private W&B project). arXiv was unreachable from this environment, so paper numbers came via secondary summaries and Ai2’s GitHub repositories; the notes file lists 13 items to verify against the primary sources.