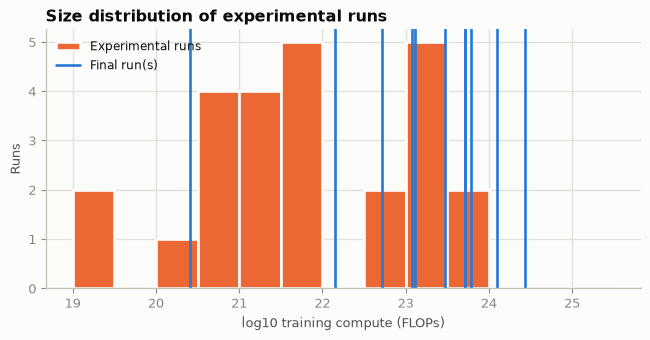
Marin runs every experiment as a public GitHub issue with W&B links, which makes it the only lab whose whole experiment record can be browsed: 446 issues carry the experiment label as of this writing, and the 8B and 32B retrospectives name every phase, restart and discarded cooldown. Final runs so far: Marin 8B (May 2025), Marin 32B (Oct 2025), Snowball 67B-A2B (2026), and a 535B-A23B hero run in progress. Working notes with sources are in data/notes/marin.md.
Marin at a glance
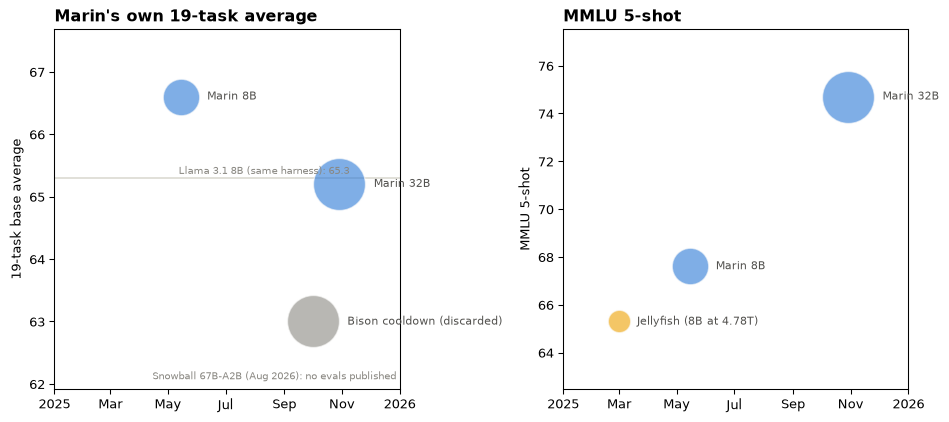
Two figures before the detail. First, the released and evaluated checkpoints over time, scored on Marin’s own 19-task base-model average and on MMLU, with circle area proportional to the cumulative pretraining compute behind each checkpoint. Post-training compute would be drawn as a ring around the disk, but the 8B instruct model’s SFT used 2.6e20 FLOPs, four ten-thousandths of the base’s 6.1e23, so the ring would be indistinguishable from the disk and is omitted; the 32B has no post-trained release. The 2026 runs are missing from this figure because none has a published benchmark table yet: Delphi’s held-out models (March 2026), Snowball 67B-A2B (pretraining finished August 2026) and the 535B-A23B hero run (in progress) have public loss curves, which the next figure uses, but no evaluations.
Two released dense models in five months is a short series, and the 32B’s 19-task average is below the 8B’s despite twice the compute: the 19-task suite saturates on easy tasks and the 32B’s gains were on MMLU (+7), MMLU-Pro (+9) and BBH. The discarded Bison cooldown sits two points under Mantis on the same tokens.
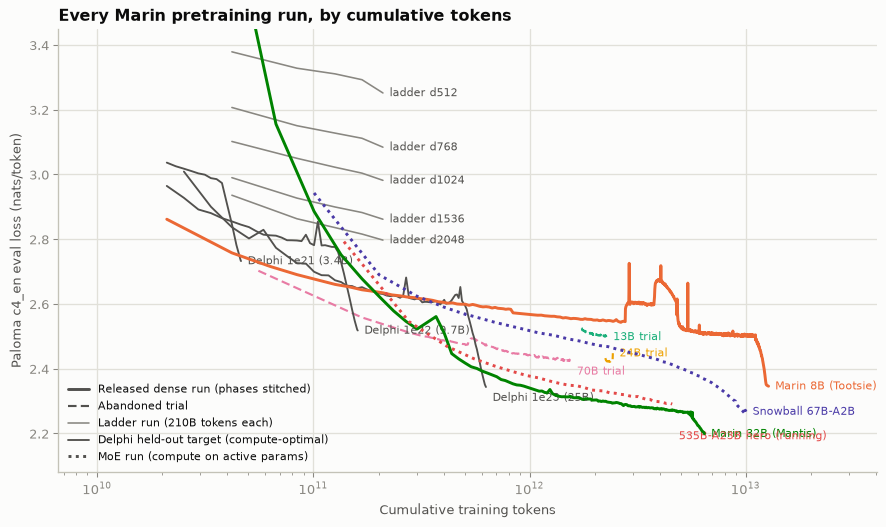
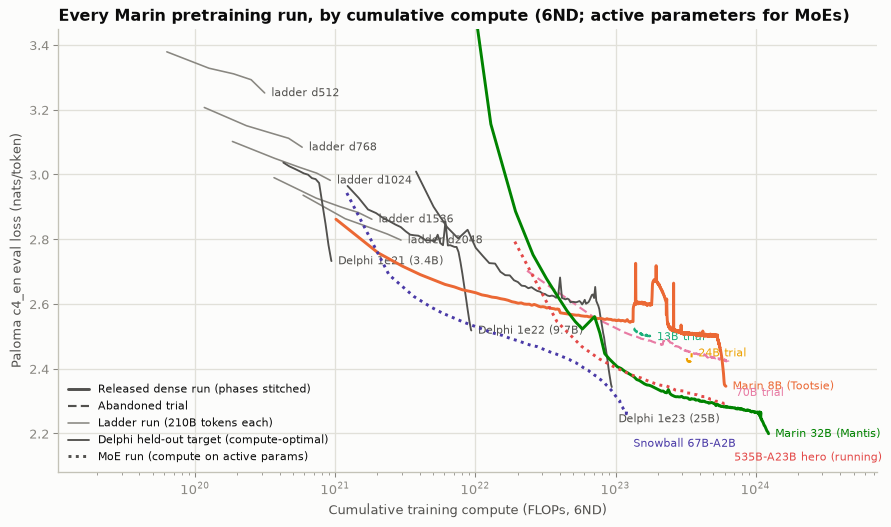
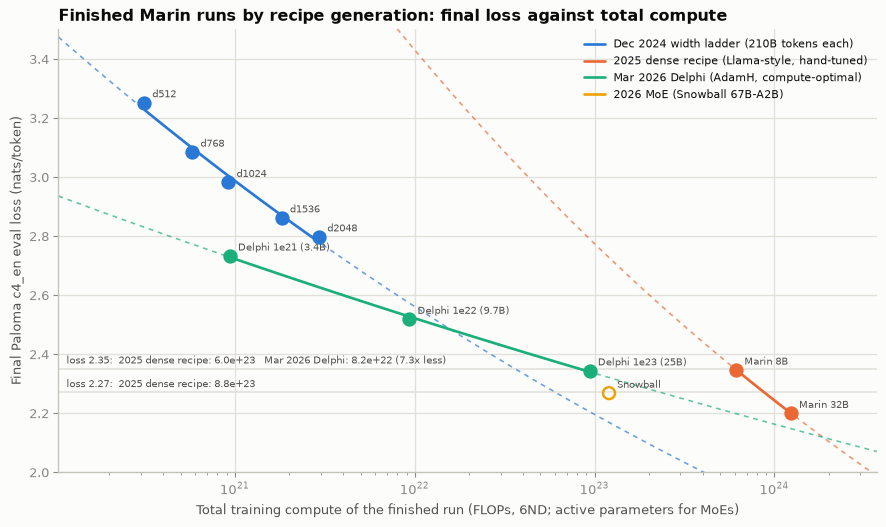
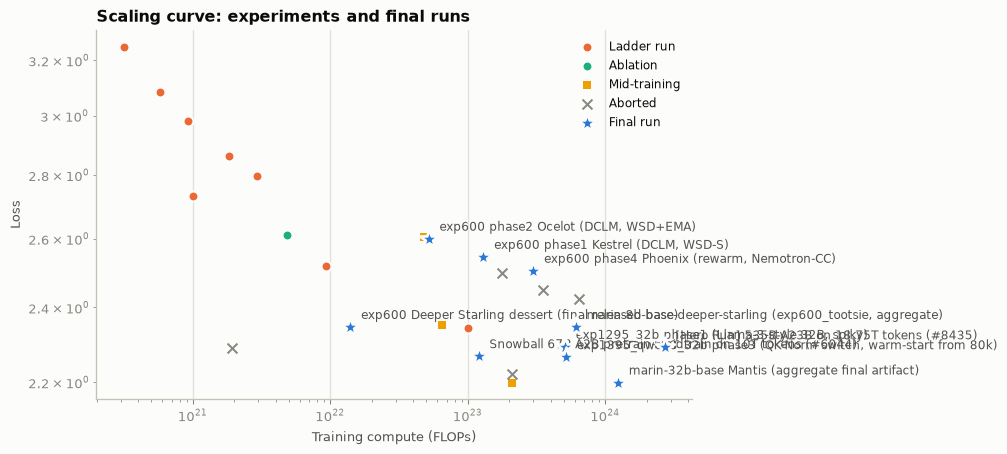
Second, every Marin pretraining run with a public loss curve on one axis, three generations of recipe: the five-width December 2024 ladder and the 2025 dense runs (the 8B with all its phases stitched together, the three abandoned Tootsie trials, the 32B) in the hand-tuned Llama-style recipe; Delphi’s three held-out compute-optimal models from March 2026 in the AdamH recipe; and the 2026 mixture-of-experts runs, Snowball 67B-A2B and the 535B-A23B hero run as far as it has got. The second chart puts them on cumulative compute (6ND, active parameters for the MoEs), which is what makes sizes and recipes comparable. The first 20B tokens of each run are cut. The MoE curves are the Paloma c4_en loss under dropless routing (no capacity-factor token dropping); the hero run’s first segment logged a capacity-dropped evaluation instead, which sits about 0.13 nats higher at the same step and is not drawn.
Three readings from the compute axis.
Size, within one recipe. Where the 13B trial stopped (1.8e23 FLOPs) it was at 2.50 against the 8B’s 2.60 at the same compute; the 24B at 3.5e23 was 2.45 against 2.51. The 70B stopped at 6.5e23, just past the finished 8B’s 6.1e23, at 2.42 against the 8B’s final 2.35: on matched compute the smaller model won, because it had a cooldown and the 70B never did. That is the same lesson as the trajectory figure below, from the other side: without a cooldown a trial’s loss understates the model. The ladder’s small models, trained to 90 to 900 tokens per parameter, sit well above everything else at equal compute, which is what over-training past the compute-optimal point costs.
Recipe, at equal compute. Delphi’s 1e23 model reached 2.34 on 9.4e22 FLOPs. The 32B, on the 2025 recipe, was at 2.42 when it had spent the same compute, and the 8B at 2.55; the finished 32B needed 1.2e24, thirteen times as much, to get to 2.20. Delphi’s 1e22 model likewise beats the 8B at matched compute by 0.12. Some of that is compute-optimal allocation rather than recipe, since the 2025 runs were far past optimal tokens per parameter at any given point, but it is the cleanest cross-generation comparison Marin’s record allows.
Architecture. Snowball, at 1.2e23 FLOPs of active-parameter compute, ended at 2.27, below Delphi’s 25B dense model at similar compute and below where the 32B was at that compute by 0.12. The hero run at 4.6T tokens (6.3e23 FLOPs so far) is at 2.29, level with where the 32B was at the same compute, and still at full learning rate with three quarters of its tokens to go. The 6ND-on-active-parameters convention flatters MoEs, since it ignores the memory and communication cost of the inactive experts, and the two MoE curves should be read against each other and against the Marin MoE law rather than as a like-for-like efficiency gain.
Bookkeeping: the 13B trial’s curve starts at 1.7T tokens because only its longest restart segment was fetched; the trials’ token axes use the average tokens per step from W&B, since their batch ramps are not public; Snowball’s active parameter count (about 2B) is from the model name, not a stated figure.
Returns to post-training compute
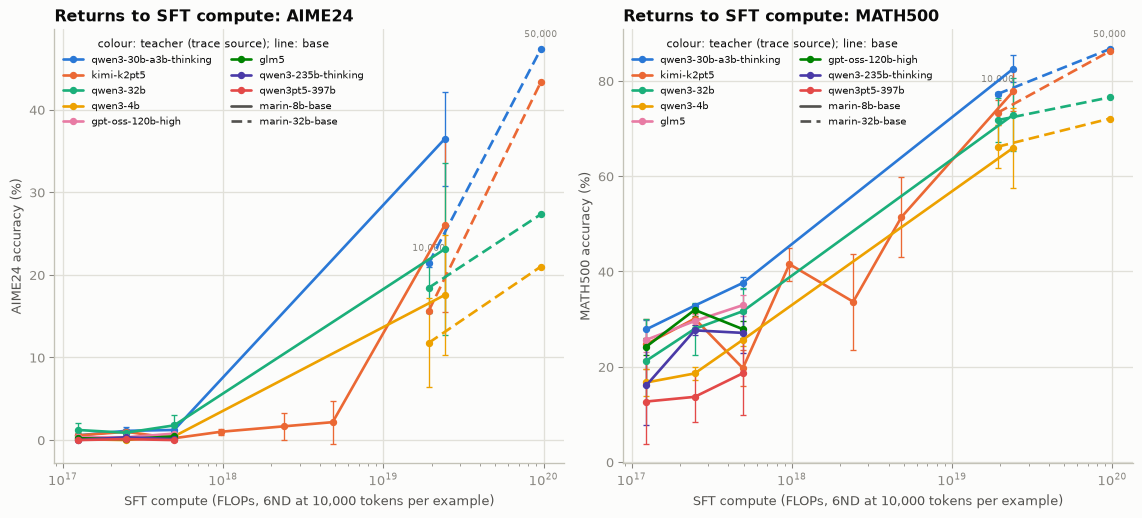
Marin has published no RL curve, and its only released post-trained model is the SFT-only 8B instruct. But one 2026 experiment (issue 3956, April to May 2026) is exactly a returns-to-SFT sweep: the Marin 8B base fine-tuned on OpenThoughts-4 math subsets of 256, 512, 1,024, 2k, 5k, 10k and 50k examples, each with reasoning traces written by one of eight teacher models, three training repeats per cell; the 32B base on 10k and 50k with four teachers. Every fine-tune was scored with evalchemy on AIME 24 and 25, AMC23, HMMT and MATH500, averaged over 3 to 10 sampling seeds, and the results are public W&B runs. data/posttraining/marin_sft_scaling.csv holds the 1,014 averaged evaluations; src/fetch_evalchemy.py rebuilds it. SFT compute is not logged, so the x-axis is 6ND at an assumed 10,000 tokens per example (OpenThoughts traces run to the 32k cap); the assumption shifts every point by the same factor.
Four readings.
The shape depends on the benchmark. MATH500 rises close to log-linearly in SFT compute, from 13 to 28 percent at 256 examples to 66 to 83 percent at 50k on the 8B, roughly seven points per doubling of data. AIME24 is flat within noise, under 4 percent, through 10k examples and then jumps to 18 to 36 percent at 50k. A competition benchmark reads as a threshold; a broad one reads as a smooth return.
The base model carries through. At the same data and teacher, the 32B lands 10 to 20 AIME24 points above the 8B (47 against 36 percent with Qwen3-30B-A3B traces at 50k). Pretraining compute and post-training compute are not substitutes here; the larger base gets more from every example.
The teacher matters as much as the data. At 50k examples on the 8B, traces from Qwen3-30B-A3B-Thinking give 36 percent on AIME24 and traces from Qwen3-4B give 18, at identical SFT compute. What is being bought is distilled capability from a stronger model, so this is a return to distillation, not to post-training compute alone, and it cannot be read across to RL.
The compute is tiny. The 50k-example run is about 2.4e19 FLOPs for the 8B under the stated assumption, four hundred-thousandths of the 6.1e23 pretraining run; the whole sweep, some 130 fine-tunes, is under 1e21. Whatever the right functional form, the marginal return per FLOP in this regime is orders of magnitude above the pretraining curve’s, which is the standard argument for why labs moved spend into post-training. Marin’s own move is the Snowball post-training pipeline, which had no published numbers as of September 2026.
Compute and cost
Marin has never published a dollar figure, a GPU-hour total or a budget. What exists: the compute was donated (Google’s TPU Research Cloud for the 2024 and 2025 runs and for Delphi; the Jen-Hsun and Lori Huang Foundation’s CoreWeave GB200 allocation for the 535B run, out of a total foundation purchase of about $108M of CoreWeave compute for AI research that is not broken down by project), development funding came from the Siegel Family Endowment and Schmidt Sciences, and the team grew from one to about ten FTE between 2025 and 2026. The table converts the 6ND compute of every sized Marin run into the book’s common yardstick, H100-hours at 40 percent utilisation and $2 per hour; these are what the runs would have cost at cloud list price on GPUs, not what Marin paid, which was nothing in cash for the accelerators.
| 0 |
delphi |
ladder |
1.19e+23 |
82,603 |
$0.17M |
| 1 |
marin-13b |
aborted |
1.77e+23 |
122,917 |
$0.25M |
| 2 |
marin-24b |
aborted |
3.50e+23 |
243,056 |
$0.49M |
| 3 |
marin-32b |
final |
1.03e+24 |
715,278 |
$1.43M |
| 4 |
marin-32b |
midtrain |
2.10e+23 |
145,833 |
$0.29M |
| 5 |
marin-32b |
aborted |
2.12e+23 |
147,167 |
$0.29M |
| 6 |
marin-535b-a23b |
ladder |
6.72e+21 |
4,665 |
$0.01M |
| 7 |
marin-535b-a23b |
final |
2.70e+24 |
1,875,000 |
$3.75M |
| 8 |
marin-70b |
aborted |
6.47e+23 |
449,306 |
$0.90M |
| 9 |
marin-8b |
ladder |
6.58e+21 |
4,573 |
$0.01M |
| 10 |
marin-8b |
ablation |
4.80e+21 |
3,333 |
$0.01M |
| 11 |
marin-8b |
final |
4.96e+23 |
344,622 |
$0.69M |
| 12 |
marin-8b |
midtrain |
1.13e+23 |
78,472 |
$0.16M |
| 13 |
marin-ablations |
ablation |
4.80e+20 |
333 |
$0.00M |
| 14 |
marin-moe |
ladder |
1.11e+23 |
76,875 |
$0.15M |
| 15 |
marin-snowball-67b-a2b |
final |
1.20e+23 |
83,333 |
$0.17M |
All sized Marin runs together: 6.3e+24 FLOPs, about 4.4M H100-hours or $9M at list price; the 535B hero run alone is 43% of it. Rows typed final include the released 8B and 32B and the Snowball and 535B runs; aborted is the discarded 32B cooldown, rescues and the 13B/24B/70B trials; ladder is Delphi, the MoE sweeps and the 2024 width ladder.
The share that did not ship (aborted plus ladder plus ablation rows) is the experiment share this book is after, and for Marin it is a floor: the 446-issue long tail of small ablations has no compute attached, and the 2026 MoE screening cells (about 80 runs at d512 to d1280) are one row. People are the other missing half. At ten FTE and a fully loaded US research-engineer cost of $300k to $500k a year, Marin’s labour bill is a few million dollars a year, the same order as the list-price value of a year of its compute; but neither number is Marin’s, and the lab has not published either.
Algorithmic efficiency across recipe generations
The cleanest measure of algorithmic progress a lab’s own record allows is the compute its finished runs needed to reach a given loss, generation by generation. Finished matters: under a warmup-stable-decay schedule the loss drops at the cooldown wherever it happens to fall, so the point along a curve where it first crosses a threshold mostly measures where the cooldown was, not how good the recipe is. The figure below therefore uses only endpoints: the five December 2024 ladder runs, the two 2025 dense releases, Delphi’s three 2026 held-out models, and Snowball. The 13B, 24B and 70B trials and the running hero are excluded because they never cooled down. A power law is drawn through each generation’s endpoints; dashed where extrapolated.
At c4_en 2.35 (the finished 8B’s loss): 2025 recipe 6.0e+23 FLOPs, Delphi 8.2e+22, a 7.3x reduction in about ten months. At Snowball’s 2.268: the 2025 line needs 8.9e+23, Delphi’s line (extrapolated 2.6x past its largest run) 2.4e+23, Snowball used 1.2e+23: 7.4x over 2025 and 2.0x over Delphi, on active-parameter compute.
Three cautions on reading this as a rate of algorithmic progress. The generations differ in data as well as recipe (DCLM and Nemotron-CC for the 2025 runs, a Nemotron, StarCoder and ProofPile mix for Delphi), and c4_en is a web-text loss, so part of the gap is data mix. The 2025 runs were trained far past compute-optimal tokens per parameter, so part of the gap is allocation rather than optimizer or architecture; Delphi’s own contribution was to make the allocation principled. And MoE compute on active parameters ignores the memory and communication cost of the inactive experts, which is why Marin quotes its MoE gain as 6.7x theoretical but 3.6x realised on TPU v4. Marin’s own stated multipliers, on its Paloma macro-loss metric, are: the May 2026 recipe law against the April MoE law, which at equal loss implies about 2.1x less compute in seven weeks (the coefficient fell from 95.18 to 88.90 at a shared exponent of 0.0941); the MoE recipe against Delphi, 3.6x realised; and the 2025 optimizer benchmark, at most 1.4x over AdamW at 130M shrinking to about 1.1x at 1.2B. Taken together with the endpoint frontier, Marin’s record is consistent with something like a 5 to 10x fall in compute-to-loss between the 2025 and 2026 recipes, most of it from compute-optimal allocation and the AdamH recipe, with MoE adding a further two-fold on the active-parameter accounting.
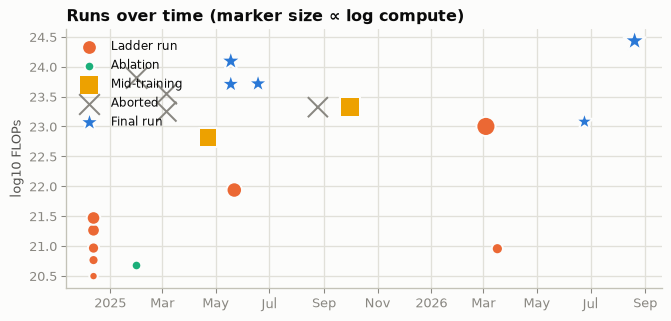
All scaling experiments over time
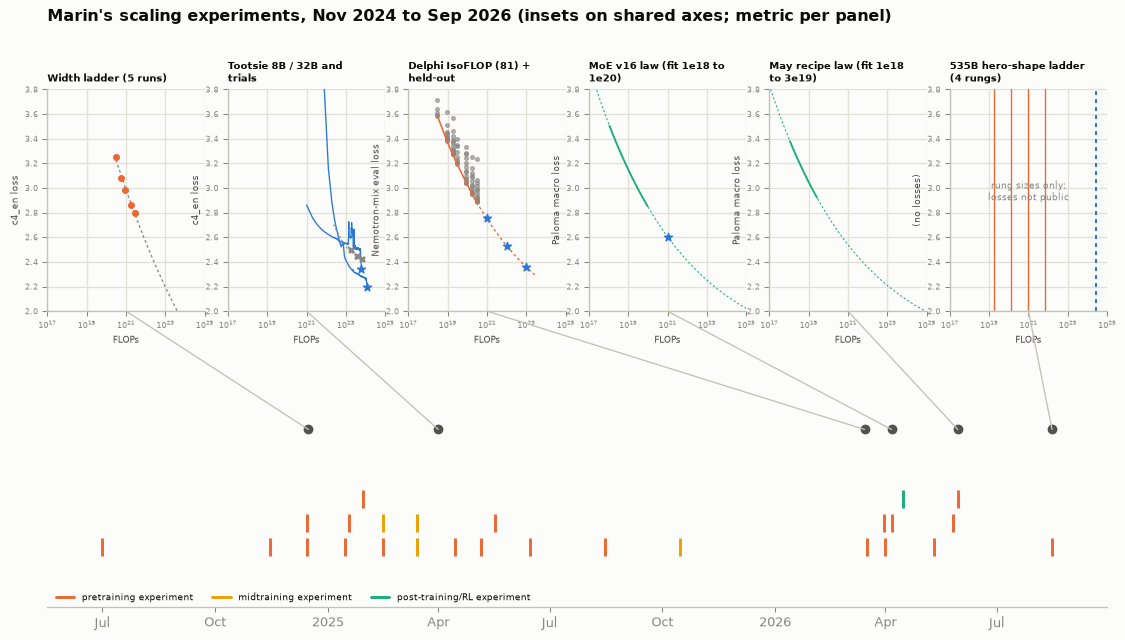
Every Marin experiment with a date, on one time axis. The six families that produced a scaling curve are drawn as insets on shared axes (compute 1e17 to 1e25 FLOPs on x, loss 2.0 to 3.8 on y), each above its date, so their shapes and ranges can be compared directly; every other dated experiment in experiments.csv is a tick on the timeline, coloured by stage. The insets do not share a metric: the ladder and Tootsie panels are Paloma c4_en, Delphi is its Nemotron-mix eval loss, and the two MoE laws are Paloma macro loss, so compare shapes across panels, not levels.
The picture is of a lab that ran one width ladder, then trained by hand for a year, then built the apparatus: within five months of March 2026 it had an IsoFLOP suite validated at 300x, two successive MoE laws on the same functional form, a learning-rate law, and a hero-shape ladder. The 2025 panel is the only one whose curves are actual training trajectories rather than fitted laws or ladder endpoints; everything before it is five points and everything after it is a formula plus a validation star.
What is unusual here
Marin’s flagship 2025 runs were not preceded by a scaling ladder. The 8B was chosen “mostly out of pragmatism” (reserved capacity) and started “with what we had”; the 32B was “largely a scale-up of the 8B recipe” and needed two rescues and a discarded cooldown. In 2026 the lab built the machinery it had lacked: Delphi (an 81-run IsoFLOP suite whose pre-registered forecast hit the 1e23 run within 0.2 percent at a 300x extrapolation), a mixture-of-experts law validated at 1e21, a learning-rate law that removed per-size sweeps, and a four-rung ladder costing about 1 percent of the 535B run. So this chapter shows both regimes in one lab: scale-up by hand, then scale-up by law.
Compute that did not ship
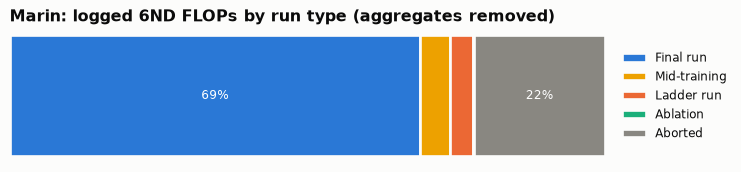
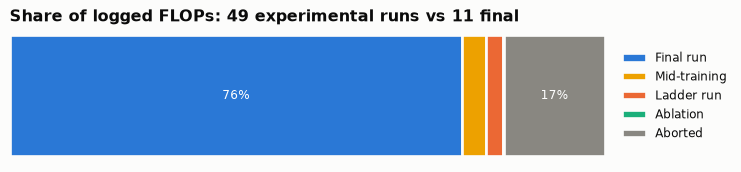
Where OLMo’s development share comes from an accounting paper, Marin’s is visible run by run. The 32B programme discarded a full 1.07T-token cooldown (about 2.1e23 FLOPs) after GSM8K contamination and a data-permutation artefact were traced, and abandoned an optimizer-state rebuild and a Muon swap. Three larger Tootsie runs (13B, 24B, 70B) were opened and closed with empty results. The bar below counts only runs with a size attached, so the 446-issue long tail of small ablations is missing from it; it is a floor.
Non-final share of logged FLOPs: 31%; aborted alone: 22%.
The final runs as trajectories
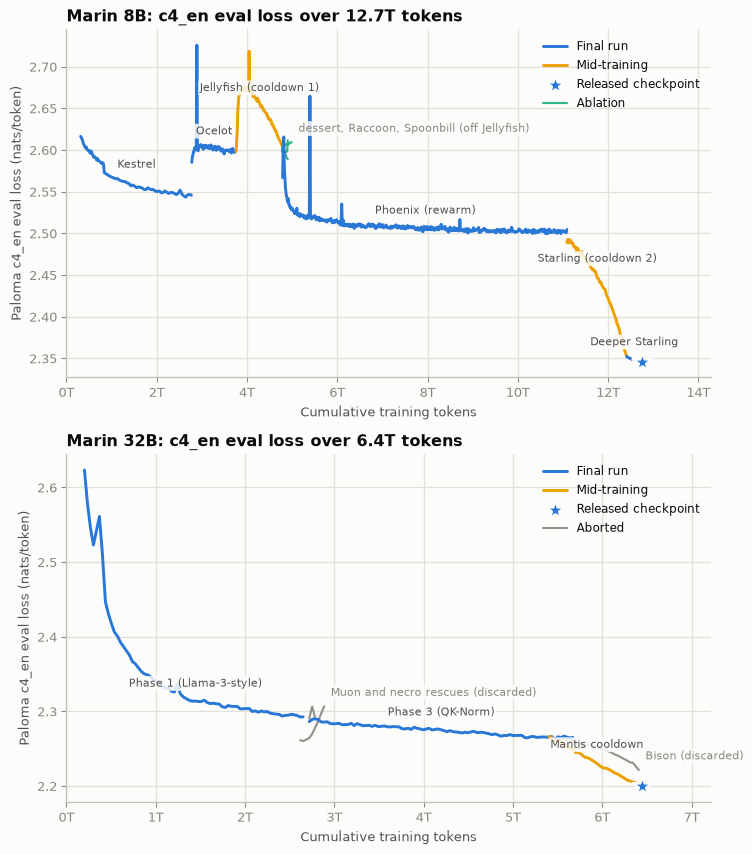
runs.csv gives each phase of the 8B and 32B runs its own tokens and FLOPs. That is right for the compute split and wrong for the loss: the loss at the end of Phoenix reflects every token since step 0, not the 6.3T on that row. The figure below puts the W&B curves on the honest axis, cumulative training tokens (the trainer’s global step times the batch schedule, which reproduces the model card’s phase totals to within 0.03T), and draws each phase, cooldown and abandoned side branch as one piece of one trajectory. The metric is the Paloma c4_en eval loss throughout; train loss moves with the data mix and is not comparable across phases. The first 0.3T tokens are cut so the warm-up does not set the scale.
Start and end of every drawn segment (start = first eval point after the cut):
| 0 |
Kestrel |
final |
0.315 |
2.768 |
2.616 |
2.546 |
-0.071 |
| 1 |
Ocelot |
final |
2.776 |
3.745 |
2.585 |
2.600 |
0.015 |
| 2 |
Jellyfish (cooldown 1) |
midtrain |
3.757 |
4.776 |
2.598 |
2.605 |
0.007 |
| 3 |
Phoenix (rewarm) |
final |
4.789 |
11.085 |
2.567 |
2.505 |
-0.062 |
| 4 |
Starling (cooldown 2) |
midtrain |
11.085 |
12.410 |
2.489 |
2.352 |
-0.137 |
| 5 |
Deeper Starling |
final |
12.410 |
12.746 |
2.352 |
2.346 |
-0.006 |
| 6 |
dessert, Raccoon, Spoonbill (off Jellyfish) |
ablation |
4.776 |
4.990 |
2.605 |
2.609 |
0.004 |
| 7 |
exp898 Raccoon (deep cooldown 1.7e-4->1.7e-5 f... |
ablation |
4.776 |
4.902 |
2.605 |
2.612 |
0.007 |
| 8 |
exp916 Spoonbill (cooldown to 3e-5 + Tulu 0.3%... |
ablation |
4.839 |
4.902 |
2.596 |
2.589 |
-0.008 |
| 9 |
Phase 1 (Llama-3-style) |
final |
0.201 |
2.651 |
2.623 |
2.292 |
-0.331 |
| 10 |
Phase 3 (QK-Norm) |
final |
2.718 |
5.671 |
2.286 |
2.265 |
-0.021 |
| 11 |
Mantis cooldown |
midtrain |
5.402 |
6.442 |
2.266 |
2.199 |
-0.067 |
| 12 |
exp1390_32b_necro (optimizer-state rebuild res... |
aborted |
2.718 |
2.785 |
2.290 |
2.291 |
0.001 |
| 13 |
Muon and necro rescues (discarded) |
aborted |
2.617 |
2.886 |
2.261 |
2.306 |
0.045 |
| 14 |
Bison (discarded) |
aborted |
5.402 |
6.409 |
2.266 |
2.221 |
-0.045 |
Four things are visible here that no per-row number shows.
Stable phases are nearly flat on this metric. Kestrel’s constant-learning-rate stretch from 2T to 2.77T moved the loss by under 0.01. Phoenix spent 5.5T tokens, 43 percent of the whole run, between 2.52 and 2.50. Phase 3 of the 32B bought 0.02 over 3T tokens. Under a warmup-stable-decay schedule the stable phase is banking capability that only shows up in the decay, so most of the tokens in both runs look wasted on a loss-versus-tokens plot and are not.
The cooldowns do the visible work. Starling, the second 8B cooldown, is 1.3T tokens or 10 percent of the run, and took the loss from 2.49 to 2.35: a larger drop than the entire 9T between 2T and 11T (0.06). The 32B’s Mantis cooldown bought 0.07 in 1.07T tokens against phase 3’s 0.02 in 3T. A final-run loss is therefore as much a measurement of cooldown depth as of scale, which matters when the cross-lab chapter compares final losses across labs.
The first cooldown bought nothing on c4_en. Jellyfish ended at 2.605, above the 2.585 where Ocelot started, while its benchmark gains were real (MMLU 65.3, the reason it was kept). The 70/30 high-quality mix moves the model away from web text, and c4_en is web text. The three short cooldown branches off Jellyfish (dessert, Raccoon, Spoonbill) all land within 0.02 of it. Their value was diagnostic: Raccoon and Spoonbill isolated the lm_head norm explosion that led to z-loss in Starling.
Restarts and rescues leave marks. Every phase boundary shows a transient: the batch and learning-rate change into Ocelot, the rewarm into Phoenix, a spike at 5.4T. The 32B’s phase 1 spikes are visible even in the sparse eval curve, and its two rescue attempts sit on top of the trunk and go nowhere (the Muon swap ends 0.045 above where it began). Bison and Mantis ran the same 1.07T tokens; Mantis sits 0.02 below Bison at matched tokens, so the permutation fix and MegaMath moved the loss, not only the contaminated GSM8K score.
The trajectory also corrects a comparison made in earlier drafts of this chapter, which read the abandoned 13B, 24B and 70B trials’ final losses against the finished 8B’s 2.35. Those trials never had a cooldown, so that reading is unfair to them. At matched tokens, with no cooldown on either side, the size advantage was real and grew with size:
| 12 |
exp860 Tootsie 13B |
13B |
2.27 |
2.498 |
2.548 |
-0.050 |
| 13 |
exp861 Tootsie 24B |
24B |
2.43 |
2.448 |
2.546 |
-0.098 |
| 14 |
exp750 Tootsie 70B |
70B |
1.54 |
2.425 |
2.555 |
-0.130 |
What Marin gave up in April 2025 was that gap; the losses on the rows understate it.
The mixture-of-experts law and its held-out point
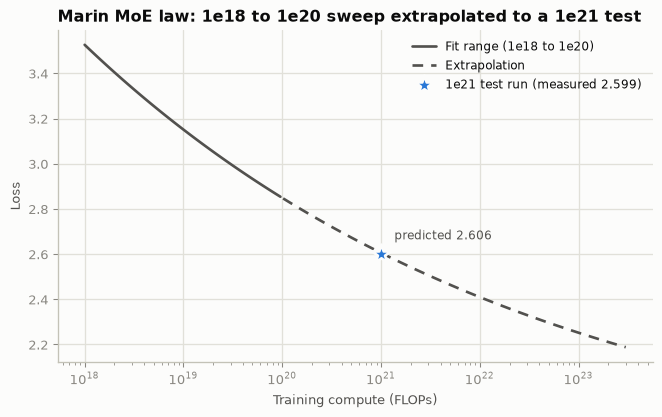
Marin fitted loss = 1.6 + 95.18 · C^-0.0941 on a 1e18 to 1e20 IsoFLOP sweep and then trained a 1e21 test: predicted 2.606, measured 2.599. That is the experiments-predict-the-final-run test in miniature, and the residual is the number the cross-lab chapter wants.
Log residual at 1e21: -0.0027. Elasticity of loss to compute at 1e21 from the law: -0.036; at the 2.7e24 hero-run scale it falls to -0.022 because the pinned irreducible term dominates.
Run sizes, compute split, timeline
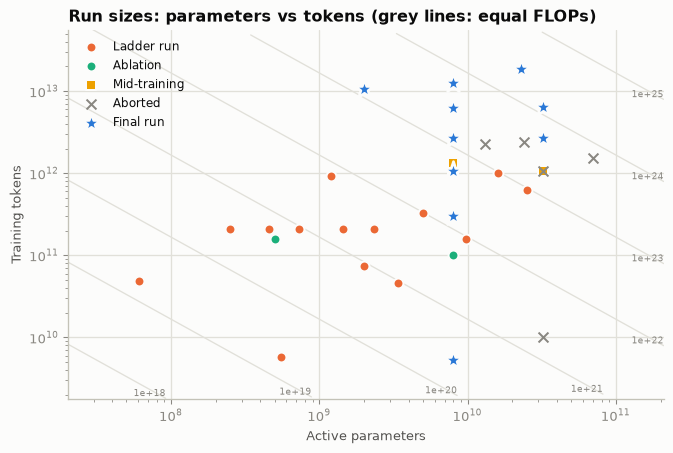
Losses come from the public marin-community/marin W&B project (data/losses/marin/; the metric is the Paloma c4_en eval loss, the one the retrospectives plot, in nats per token with the Llama 3 tokenizer). Eighteen runs are covered: every 8B phase and cooldown, the 13B, 24B and 70B trials, and the 32B phases, rescues and cooldowns. The standard panel below draws them without a fitted law, for the reason the trajectory figure makes visible: most rows with a loss are continuation phases whose flops is that phase’s compute, not the cumulative compute the loss reflects, and the cooldown losses are on a different learning-rate footing from the pretraining phases. Read the abandoned trials against the 8B at matched tokens (table above), not against the finished stars. Delphi’s 81-run grid is one row here; its per-run sizes are in the repository’s hard-coded suite and can be expanded later.
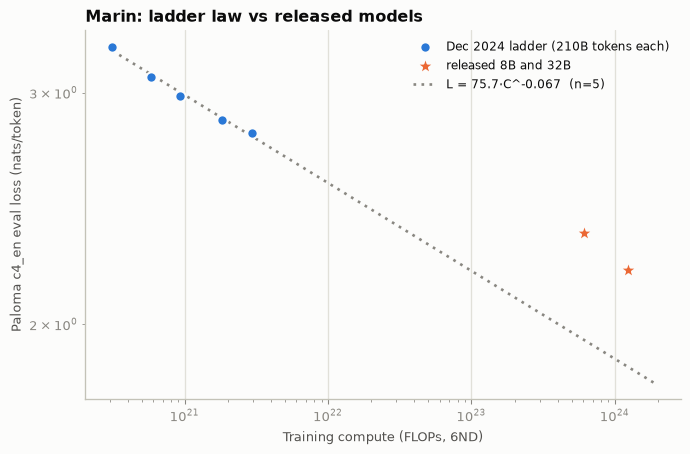
One clean experiment series does exist: a five-width ladder from December 2024 (tootsie-scaling-*, hidden 512 to 2048 at 16 layers, each 210B tokens of DCLM-baseline, so 90 to 900 tokens per parameter rather than compute-optimal). Fitting a two-parameter power law to those five points and extrapolating to the released 8B and 32B is the report’s basic move, shown here on Marin’s own data; the residuals are in the table.
| 0 |
marin-8b-base-deeper-starling (exp600_tootsie,... |
6.100000e+23 |
2.3460 |
1.9455 |
0.1872 |
| 15 |
marin-32b-base Mantis (aggregate final artifact) |
1.240000e+24 |
2.1993 |
1.8554 |
0.1700 |
The ladder is not a compute-optimal sweep, the law has no irreducible term (so it keeps falling where a real curve flattens), and the finals sit at the end of long cooldowns on a different data mix, so the residual mixes all three effects; a 200x to 400x extrapolation from five points is a demonstration of the method, not a test of Marin’s forecasting. It is still the only Marin curve that runs from experiments to finals on one metric.
Experimental share of logged FLOPs: 24% (a lower bound: unlogged and failed runs are missing).
Published scaling experiments
| 0 |
delphi |
2026-05-11 |
pretraining |
Scaling suite / scaling law: IsoFLOP sweeps (Q... |
d512-d4096 grid (~1e8-1e10 params); optima 550... |
3e18-3e20 fit; 1e21/1e22/1e23 held out |
eval loss (Paloma/Nemotron); D*~A*C^alpha from... |
not accessible (alpha for D* vs C not in reach... |
figure_only |
logs |
[src](https://openathena.ai/blog/delphi/ ; htt... |
Forecast of 1e23 run within 0.2% (300x extrapo... |
| 1 |
delphi |
2026-04-01 |
pretraining |
Scaling-law extrapolation check ('at least 100... |
as above |
~1e21 ladder cost vs 1e23 target |
loss |
|
figure_only |
figure_only |
[src](https://x.com/WilliamBarrHeld/status/203... |
HF commit 'blog update: 100x -> 300x'. |
| 2 |
marin-moe |
2026-04-06 |
pretraining |
MoE v16 AdamH IsoFLOP sweep -> compute-optimal... |
d512-d2560 (MoE, 64 experts); recommendation 1... |
1e18-1e20 fit; 1e21 validation |
Paloma macro loss; loss(C)=1.6+95.18*C^-0.0941 |
0.0941 (L_inf pinned 1.6) |
numbers_in_text |
logs |
[src](https://github.com/marin-community/marin... |
Predicted 2.606 vs measured 2.599 at 1e21; unc... |
| 3 |
marin-moe |
2026-05-30 |
pretraining |
May Recipe (MuonH, QB router, half-RoPE, XSA, ... |
d512-d1792 |
1e18-3e19 (1e18 dropped from fit) |
Paloma macro; loss=1.6+88.90*C^-0.0941 (README... |
0.0941 (pinned to v16) |
numbers_in_text |
logs |
[src](https://github.com/marin-community/marin... |
2.12-2.22x equal-throughput compute-equivalent... |
| 4 |
marin-moe |
2026-05-26 |
pretraining |
MuonH learning-rate scaling law sweep (~150 runs) |
d512-d1280 |
4-240 tokens/param (+TPP 5000) |
loss-optimal LR; LR=26.9*tokens^-0.395*dim^-0.... |
-0.395 (tokens), -0.121 (dim), +0.5 (batch); R... |
numbers_in_text |
logs |
[src](https://github.com/marin-community/marin... |
Adopted in heuristic as adam_lr=0.06602*tokens... |
| 5 |
marin-moe |
2026-03-31 to 2026-08-20 |
pretraining |
Agent MoE digest: 80 small-scale A/B experimen... |
d512-d1280 MoE cells |
~1e17-1e20 per cell |
model-FLOPs speedup via scaling-law inversion ... |
|
numbers_in_text |
logs |
[src](https://github.com/marin-community/marin... |
16 worked / 9 promising / 13 mixed / 32 did no... |
| 6 |
marin-535b-a23b |
2026-08 |
pretraining |
4-rung hero-shape scaling ladder to forecast a... |
1.6B-A61M (48B tok) ... 27.7B-A1.2B (926B tok) |
~1.8e19 to ~6.7e21 per rung; ladder ~1% of 2.7... |
loss, grad norm, token dropping, eval trajecto... |
|
figure_only |
figure_only |
[src](https://x.com/percyliang/status/20909180... |
Forecast loss value not in accessible text (W&... |
| 7 |
marin-moe |
2026-03-17 |
pretraining |
MoE architecture + quantile balancing at 1e21 ... |
14B-A2B (75B tok); 35B-A5B (326B tok) |
1e21-1e22 |
paloma/macro_loss; predicted 2.3887 at 1e22 |
|
numbers_in_text |
logs |
[src](https://github.com/marin-community/marin... |
Blog: zero loss spikes, no aux loss. |
| 8 |
marin-8b |
2024-12 to 2025-06 |
pretraining |
Scaling laws to predict Tootsie 8B performance... |
not stated |
not stated |
c4_en bpb; lm_eval acc_norm; forced-choice bpb |
|
figure_only |
figure_only |
[src](https://github.com/marin-community/marin... |
Results section empty; two W&B reports (blocked). |
| 9 |
marin-8b |
2025-02 |
pretraining |
Scaling-law experiment plan: ladders of ~5 mod... |
up to 1.4B, projected to 8B-22B |
not stated |
loss/bpb |
|
figure_only |
figure_only |
[src](https://github.com/marin-community/marin... |
Closed 2025-08-24; unclear how much executed. |
| 10 |
marin-ablations |
2025-01-18 |
pretraining |
AdamW hyperparameter sweep across 3 (N,D) sett... |
0.1B, 0.5B |
10B-50B tokens |
loss; optimal hparams stable |
|
numbers_in_text |
logs |
[src](https://github.com/marin-community/marin... |
lr*width=1.6e-2*512 rule. |
| 11 |
marin-ablations |
2025-05-17 |
pretraining |
Optimizer benchmark: 10 optimizers, 4 sizes, 1... |
130M-1.2B |
1x-16x Chinchilla |
speedup over AdamW: <=1.4x (130M) shrinking to... |
|
numbers_in_text |
logs |
[src](https://github.com/marin-community/marin... |
Muon best at 1-4x; Soap/Kron at >=8x. |
| 12 |
marin-ablations |
2025-01-30 |
pretraining |
LR schedule (cosine, linear, WSD 20/40% const/... |
0.5B |
4.8e20 per run x7 |
loss |
|
numbers_in_text |
logs |
[src](https://github.com/marin-community/marin... |
Cosine best; high LR important; WSD 'isn't ter... |
| 13 |
marin-ablations |
2025-04 |
pretraining |
z-loss vs none from scratch |
1.4B |
|
loss, lm_head norm |
|
numbers_in_text |
logs |
[src](https://github.com/marin-community/marin... |
Adopted z-loss 1e-4 as default. |
| 14 |
marin-ablations |
2025-05-06 |
pretraining |
MoE (8x1B) vs dense 1B, matched tokens |
1B dense; 8x1B MoE |
|
train/eval loss, MFU |
|
numbers_in_text |
logs |
[src](https://github.com/marin-community/marin... |
MoE wins on tokens; dense better MFU; crossove... |
| 15 |
marin-ablations |
2024-11 |
pretraining |
Tokenizer choice (Llama3/Llama2/NeoX) |
small |
|
bpb |
|
numbers_in_text |
logs |
[src](https://github.com/marin-community/marin... |
Llama 3 tokenizer best. |
| 16 |
marin-ablations |
2025-01 |
pretraining |
High-quality many epochs vs lower-quality few ... |
|
|
loss/evals |
|
numbers_in_text |
logs |
[src](https://github.com/marin-community/marin... |
'There's no data like more data'. |
| 17 |
marin-ablations |
2024 |
pretraining |
HTML->text extraction methods |
|
|
Paloma loss |
|
numbers_in_text |
logs |
[src](https://github.com/marin-community/marin... |
Format preservation helps. |
| 18 |
marin-8b |
2025-02 to 2025-05 |
midtraining |
Microannealing (70/30 anneals) to score cooldo... |
8B checkpoint |
|
task accuracy + HQ eval loss |
|
numbers_in_text |
logs |
[src](https://github.com/marin-community/marin... |
70% PT/15% FLAN/15% HQ best; HQ-only hurt task... |
| 19 |
marin-8b |
2025-03 |
midtraining |
Cooldown ablations of markdownified Wikipedia/... |
8B checkpoint |
|
loss/evals |
|
numbers_in_text |
logs |
[src](https://github.com/marin-community/marin... |
No major improvement vs control. |
| 20 |
marin-8b |
2025-03 to 2025-04 |
midtraining |
Deep cooldown depth (1.7e-4 vs 3e-5 vs 1.7e-5)... |
8B |
|
training loss drift, lm_head norm, SFT evals |
|
numbers_in_text |
logs |
[src](https://github.com/marin-community/marin... |
z-loss 1e-4 cured loss creep; adopted in Starl... |
| 21 |
marin-32b |
2025-06 |
pretraining |
Loss-spike mitigations at 32B: grad-norm clip ... |
32B |
~5e23 phase |
loss spikes |
|
numbers_in_text |
logs |
[src](https://github.com/marin-community/marin... |
Only QK-Norm (Qwen3 backbone) removed spikes. |
| 22 |
marin-32b |
2025-10 |
midtraining |
Data shuffle: LCG/affine permutation vs Feiste... |
32B |
|
train-loss phase shift; Paloma losses |
|
numbers_in_text |
logs |
[src](https://github.com/marin-community/marin... |
Feistel removed phase shift and improved all P... |
| 23 |
marin-ablations |
2025-08 |
pretraining |
Batch-size scaling of Muon vs AdamW gap |
|
|
loss |
|
figure_only |
logs |
[src](https://github.com/marin-community/marin... |
|
| 24 |
marin-ablations |
2024-12 |
pretraining |
MuP vs heuristic hyperparameter scaling |
|
|
loss |
|
numbers_in_text |
logs |
[src](https://github.com/marin-community/marin... |
'not worth it compared to our heuristic version'. |
| 25 |
marin-ablations |
2026-04 to 2026-05 |
post-training/RL |
SFT data scaling (exp3956): Marin 8B base fine... |
8B, 32B (Marin bases) |
about 1e18 to 1e20 FLOPs of SFT at ~1e4 tokens... |
AIME24, AIME25, AMC23, HMMT, MATH500 accuracy ... |
|
none published |
logs |
[src](https://github.com/marin-community/marin... |
Per-run evalchemy results are public W&B runs ... |
What the lab says about itself
| 0 |
marin-8b |
Experiment issues in marin-community/marin (la... |
446 |
issues |
[src](https://github.com/search?q=repo%3Amarin... |
|
as of 2026-09-13 |
| 1 |
marin-8b |
Marin 8B 19-task average vs Llama 3.1 8B |
66.6 vs 65.3 |
accuracy |
[src](https://github.com/marin-community/marin... |
beats Llama 3.1 8B on 14/19 |
|
| 2 |
marin-8b |
Compute source |
nearly all from TRC |
|
[src](https://github.com/marin-community/marin... |
"Nearly all of the compute used for Marin come... |
Google TPU Research Cloud; no dollar figures p... |
| 3 |
marin-32b |
Discarded 32B cooldown (Bison) rerun as Mantis |
1.074e12 |
tokens |
[src](https://github.com/marin-community/marin... |
|
GSM8K contamination via cached Dolmino test.js... |
| 4 |
marin-moe |
MoE IsoFLOP law (v16 AdamH, 1e18 to 1e20) |
loss = 1.6 + 95.18 * C^-0.0941 |
|
[src](https://github.com/marin-community/marin... |
|
irreducible term pinned at 1.6 |
| 5 |
marin-moe |
MoE law validation at 1e21 FLOPs: predicted vs... |
2.606 vs 2.599 |
loss |
[src](https://github.com/marin-community/marin... |
|
|
| 6 |
delphi |
Delphi pre-registered forecast error at 1e23 F... |
0.2 |
percent |
[src](https://openathena.ai/blog/delphi/) |
Delphi attempt 2 forecasts 1e23 to within 0.2% |
Confirmed in the blog text 2026-09-13: +0.2% a... |
| 7 |
delphi |
Delphi IsoFLOP grid size |
81 runs at budgets 3e18, 9e18, 1.8e19, 3e19, 9... |
runs |
[src](https://huggingface.co/datasets/marin-co... |
README: 'isoflop (81)' |
88 checkpoints on the HF org incl. held-out 1e... |
| 8 |
marin-535b-a23b |
535B hero-shape ladder cost as share of the he... |
1 |
percent |
[src](https://github.com/marin-community/marin... |
"only costs 1% of total compute" |
4 rungs, 1.6B-A61M to 27.7B-A1.2B |
| 9 |
marin-535b-a23b |
535B-A23B hero run compute |
2.7e24 |
FLOPs |
[src](https://github.com/marin-community/marin... |
|
Issue plan: 18.75T tokens, 11 x GB200 NVL72, ~... |
| 10 |
marin-moe |
May 2026 1e23 MoE hero run vs preregistered loss |
within 1 |
percent |
[src](https://openathena.ai/blog/marin-535b-la... |
The 129B-parameter, 16B-active run landed with... |
Launch note, read 2026-09-13 |
| 11 |
lab-level |
Marin headcount growth under Open Athena |
1 FTE -> 10 |
FTE |
[src](https://openathena.ai/blog/marin-535b-la... |
Since joining Open Athena, Marin has grown fro... |
Launch note, read 2026-09-13 |
Key numbers
| 0 |
marin-8b |
marin-8b-base-deeper-starling (exp600_tootsie,... |
final |
pretraining |
8.03e+09 |
1.27e+13 |
6.10e+23 |
6*N*D with N=8.03e9 (Llama 3.1 8B dims: 32 lay... |
NaN |
2.3460 |
MMLU 5-shot (LM Eval Harness) |
67.6 |
derived |
[src](https://github.com/marin-community/marin... |
| 1 |
marin-8b |
exp600 phase1 Kestrel (DCLM, WSD-S) |
final |
pretraining |
8.03e+09 |
2.70e+12 |
1.30e+23 |
6*N*D |
NaN |
2.5455 |
|
NaN |
derived |
[src](https://github.com/marin-community/marin... |
| 2 |
marin-8b |
exp600 phase2 Ocelot (DCLM, WSD+EMA) |
final |
pretraining |
8.03e+09 |
1.08e+12 |
5.20e+22 |
6*N*D on 2.7T->3.78T |
NaN |
2.5998 |
|
NaN |
derived |
[src](https://github.com/marin-community/marin... |
| 3 |
marin-8b |
exp600 phase3 Jellyfish (first cooldown, 'monu... |
midtrain |
midtraining |
8.03e+09 |
1.00e+12 |
4.80e+22 |
6*N*D on 3.78T->4.78T |
NaN |
2.6049 |
MMLU 5-shot |
65.3 |
reported |
[src](https://github.com/marin-community/marin... |
| 4 |
marin-8b |
exp600 dessert runs (math + FLAN patches off J... |
ablation |
midtraining |
8.03e+09 |
|
|
|
NaN |
2.6091 |
GSM8K; MATH; MMLU 5-shot |
NaN |
reported |
[src](https://github.com/marin-community/marin... |
| 5 |
marin-8b |
exp600 phase4 Phoenix (rewarm, Nemotron-CC) |
final |
pretraining |
8.03e+09 |
6.32e+12 |
3.00e+23 |
6*N*D on 4.78T->11.1T |
NaN |
2.5046 |
|
NaN |
derived |
[src](https://github.com/marin-community/marin... |
| 6 |
marin-8b |
exp898 Raccoon (deep cooldown 1.7e-4->1.7e-5 f... |
ablation |
midtraining |
8.03e+09 |
1.00e+11 |
4.80e+21 |
6*N*D on ~100B tokens |
NaN |
2.6115 |
|
NaN |
reported |
[src](https://github.com/marin-community/marin... |
| 7 |
marin-8b |
exp916 Spoonbill (cooldown to 3e-5 + Tulu 0.3%... |
ablation |
midtraining |
8.03e+09 |
|
|
|
NaN |
2.5887 |
|
NaN |
reported |
[src](https://github.com/marin-community/marin... |
| 8 |
marin-8b |
exp977 phase5 Starling (second cooldown, 'sens... |
midtrain |
midtraining |
8.03e+09 |
1.34e+12 |
6.50e+22 |
6*N*D on 1.34T tokens (80,000 steps x 16Mi) |
NaN |
2.3523 |
|
NaN |
reported |
[src](https://github.com/marin-community/marin... |
| 9 |
marin-8b |
exp600 Deeper Starling dessert (final released... |
final |
midtraining |
8.03e+09 |
3.00e+11 |
1.40e+22 |
6*N*D on 12.4T->12.7T |
NaN |
2.3460 |
19-task avg |
66.6 |
reported |
[src](https://github.com/marin-community/marin... |
| 10 |
marin-8b |
marin-8b-instruct (deeper-starling-05-15 SFT) |
final |
post-training/RL |
8.03e+09 |
5.30e+09 |
2.55e+20 |
6*N*D on 5Gi tokens (10,227 steps x 512Ki) |
NaN |
NaN |
10-task instruct avg (IFEval, GSM8K-CoT, BBH, ... |
43.8 |
reported |
[src](https://github.com/marin-community/marin... |
| 11 |
marin-8b |
exp784/exp820 microannealing series (cooldown ... |
ablation |
midtraining |
8.03e+09 |
|
|
|
NaN |
NaN |
|
NaN |
reported |
[src](https://github.com/marin-community/marin... |
| 12 |
marin-13b |
exp860 Tootsie 13B |
aborted |
pretraining |
1.30e+10 |
2.27e+12 |
1.77e+23 |
6ND derived (tokens from W&B) |
NaN |
2.4983 |
|
NaN |
reported |
[src](https://github.com/marin-community/marin... |
| 13 |
marin-24b |
exp861 Tootsie 24B |
aborted |
pretraining |
2.40e+10 |
2.43e+12 |
3.50e+23 |
6ND derived (tokens from W&B) |
NaN |
2.4480 |
|
NaN |
reported |
[src](https://github.com/marin-community/marin... |
| 14 |
marin-70b |
exp750 Tootsie 70B |
aborted |
pretraining |
7.00e+10 |
1.54e+12 |
6.47e+23 |
6ND derived (tokens from W&B) |
NaN |
2.4247 |
|
NaN |
reported |
[src](https://github.com/marin-community/marin... |
| 15 |
marin-32b |
marin-32b-base Mantis (aggregate final artifact) |
final |
pretraining |
3.20e+10 |
6.44e+12 |
1.24e+24 |
6*N*D with N=32e9 (OLMo-2-32B dims) and D=6.437T |
NaN |
2.1993 |
19-task avg |
65.2 |
derived |
[src](https://github.com/marin-community/marin... |
| 16 |
marin-32b |
exp1295_32b phase1 (Llama-3-style 32B, spiky) |
final |
pretraining |
3.20e+10 |
2.68e+12 |
5.10e+23 |
6*N*D |
NaN |
2.2924 |
|
NaN |
reported |
[src](https://github.com/marin-community/marin... |
| 17 |
marin-32b |
exp1390_32b_necro (optimizer-state rebuild res... |
aborted |
pretraining |
3.20e+10 |
1.00e+10 |
1.92e+21 |
6ND |
NaN |
2.2905 |
|
NaN |
guess |
[src](https://github.com/marin-community/marin... |
| 18 |
marin-32b |
exp1380_muon32b (Muon optimizer swap at 80k) |
aborted |
pretraining |
3.20e+10 |
|
|
|
NaN |
2.3064 |
|
NaN |
reported |
[src](https://github.com/marin-community/marin... |
| 19 |
marin-32b |
exp1395_qwen3_32b phase3 (QK-Norm switch, warm... |
final |
pretraining |
3.20e+10 |
2.68e+12 |
5.20e+23 |
6*N*D |
NaN |
2.2649 |
|
NaN |
reported |
[src](https://github.com/marin-community/marin... |
| 20 |
marin-32b |
exp1529_32b_bison_cooldown (first 32B cooldown) |
aborted |
midtraining |
3.20e+10 |
1.07e+12 |
2.10e+23 |
6*N*D |
NaN |
2.2213 |
19-task avg |
63.0 |
reported |
[src](https://github.com/marin-community/marin... |
| 21 |
marin-32b |
exp1529_32b_mantis_cooldown (released cooldown) |
midtrain |
midtraining |
3.20e+10 |
1.07e+12 |
2.10e+23 |
6*N*D |
NaN |
2.1993 |
19-task avg |
65.2 |
reported |
[src](https://github.com/marin-community/marin... |
| 22 |
delphi |
Delphi IsoFLOP sweep adamh_scaling_v6 (78 runs... |
ladder |
pretraining |
|
|
8.63e+21 |
Sum of per-run budgets listed in reference_sca... |
NaN |
NaN |
|
NaN |
derived |
[src](https://github.com/marin-community/marin... |
| 23 |
delphi |
delphi-2e19-550Mparams-5.8Btokens |
ladder |
pretraining |
5.50e+08 |
5.80e+09 |
1.90e+19 |
6*N*D (nominal budget 2e19) |
NaN |
NaN |
|
NaN |
reported |
[src](https://huggingface.co/marin-community/d... |
| 24 |
delphi |
Delphi optimal 1e21 (3 seeds: 0, 42, 62746) |
ladder |
pretraining |
3.38e+09 |
4.63e+10 |
1.00e+21 |
reported budget |
NaN |
2.7326 |
|
NaN |
reported |
[src](https://github.com/marin-community/marin... |
| 25 |
delphi |
delphi-1e22-9.7Bparams-160Btokens (3 seeds) |
ladder |
pretraining |
9.70e+09 |
1.60e+11 |
9.30e+21 |
6*N*D (nominal 1e22) |
NaN |
2.5182 |
|
NaN |
reported |
[src](https://huggingface.co/marin-community/d... |
| 26 |
delphi |
Delphi optimal 1e23 (25B params, 600B tokens) |
ladder |
pretraining |
2.50e+10 |
6.28e+11 |
1.00e+23 |
6*N*D (nominal 1e23) |
NaN |
2.3435 |
|
NaN |
reported |
[src](https://openathena.ai/blog/delphi/ ; htt... |
| 27 |
marin-moe |
MoE v16 isoflop sweep (issue #4447) 1e18-1e20 |
ladder |
pretraining |
|
|
|
reported budgets |
NaN |
NaN |
|
NaN |
reported |
[src](https://github.com/marin-community/marin... |
| 28 |
marin-moe |
MoE 1e21 test (14B-A2B, 75B tokens) #3800 |
ladder |
pretraining |
1.40e+10 |
7.50e+10 |
9.00e+20 |
6*N_active*D (nominal 1e21) |
NaN |
NaN |
|
NaN |
reported |
[src](https://github.com/marin-community/marin... |
| 29 |
marin-moe |
MoE 1e22 test (35B-A5B / '32B-A5B', 326B token... |
ladder |
pretraining |
3.50e+10 |
3.26e+11 |
9.80e+21 |
6*N_active*D (nominal 1e22) |
NaN |
NaN |
|
NaN |
reported |
[src](https://github.com/marin-community/marin... |
| 30 |
marin-moe |
May 2026 1e23 MoE 'hero run' (~120-131B total ... |
ladder |
pretraining |
1.29e+11 |
1.02e+12 |
1.00e+23 |
reported budget (6*16e9*1.02e12=9.8e22 check) |
NaN |
NaN |
|
NaN |
derived |
[src](https://github.com/marin-community/marin... |
| 31 |
marin-moe |
May Recipe MuonH compute-optimal baselines (4 ... |
ladder |
pretraining |
|
|
|
reported per-cell budgets |
NaN |
3.5422 |
|
NaN |
reported |
[src](https://github.com/marin-community/marin... |
| 32 |
marin-moe |
Agent MoE experiment digest (80 sub-issues of ... |
ablation |
pretraining |
|
|
|
|
NaN |
NaN |
|
NaN |
reported |
[src](https://github.com/marin-community/marin... |
| 33 |
marin-moe |
MuonH LR scaling sweep #5951 (~150 runs) |
ablation |
pretraining |
|
|
|
|
NaN |
NaN |
|
NaN |
reported |
[src](https://github.com/marin-community/marin... |
| 34 |
marin-snowball-67b-a2b |
Snowball 67B-A2B pretrain+midtrain on 10T toke... |
final |
pretraining |
6.71e+10 |
1.05e+13 |
1.20e+23 |
6*N_active*D with N_active=2e9, D=1e13 |
NaN |
2.2676 |
|
NaN |
derived |
[src](https://github.com/marin-community/marin... |
| 35 |
marin-snowball-67b-a2b |
Snowball 2.7T-token checkpoint math RL + agent... |
ablation |
post-training/RL |
6.70e+10 |
|
|
|
NaN |
NaN |
|
NaN |
reported |
[src](https://storage.googleapis.com/marin-pub... |
| 36 |
marin-535b-a23b |
[Hero Run] 535B-A23B on 18.75T tokens (#8435) |
final |
pretraining |
5.36e+11 |
1.88e+13 |
2.70e+24 |
reported (6*23e9*18.75e12=2.6e24 check) |
1520000.0 |
2.2910 |
|
NaN |
reported |
[src](https://github.com/marin-community/marin... |
| 37 |
marin-535b-a23b |
535B hero-shape ladder rung 1: 1.6B-A61M, 48B ... |
ladder |
pretraining |
1.60e+09 |
4.80e+10 |
1.80e+19 |
6*N_active*D |
NaN |
NaN |
|
NaN |
reported |
[src](https://x.com/percyliang/status/20909180... |
| 38 |
marin-535b-a23b |
535B hero-shape ladder rung 4: 27.7B-A1.2B, 92... |
ladder |
pretraining |
2.77e+10 |
9.26e+11 |
6.70e+21 |
6*N_active*D |
NaN |
NaN |
|
NaN |
reported |
[src](https://x.com/percyliang/status/20909180... |
| 39 |
marin-ablations |
exp143 DCLM 7B baseline replication |
ablation |
pretraining |
7.00e+09 |
|
|
|
NaN |
NaN |
|
NaN |
reported |
[src](https://github.com/marin-community/marin... |
| 40 |
marin-ablations |
exp524 tokenizer comparison (Llama3 vs Llama2 ... |
ablation |
pretraining |
|
|
|
|
NaN |
NaN |
|
NaN |
reported |
[src](https://github.com/marin-community/marin... |
| 41 |
marin-ablations |
exp764 LR schedule comparison (7 runs, 0.5B, 1... |
ablation |
pretraining |
5.00e+08 |
1.60e+11 |
4.80e+20 |
6*N*D per run |
NaN |
NaN |
|
NaN |
derived |
[src](https://github.com/marin-community/marin... |
| 42 |
marin-ablations |
exp725 AdamW hyperparameter sweep (0.1B/10B, 0... |
ablation |
pretraining |
|
|
|
|
NaN |
NaN |
|
NaN |
reported |
[src](https://github.com/marin-community/marin... |
| 43 |
marin-ablations |
exp935 z-loss vs none at 1.4B |
ablation |
pretraining |
1.40e+09 |
|
|
|
NaN |
NaN |
|
NaN |
reported |
[src](https://github.com/marin-community/marin... |
| 44 |
marin-ablations |
exp1183 OLMoE replication: 8x1B MoE vs 1B dense |
ablation |
pretraining |
|
|
|
|
NaN |
NaN |
|
NaN |
reported |
[src](https://github.com/marin-community/marin... |
| 45 |
marin-ablations |
exp1290 Fantastic Pretraining Optimizers (10 o... |
ablation |
pretraining |
|
|
|
|
NaN |
NaN |
|
NaN |
reported |
[src](https://github.com/marin-community/marin... |
| 46 |
marin-ablations |
exp636 HQ many epochs vs LQ few epochs |
ablation |
pretraining |
|
|
|
|
NaN |
NaN |
|
NaN |
reported |
[src](https://github.com/marin-community/marin... |
| 47 |
marin-ablations |
exp246 HTML->text extraction comparison |
ablation |
pretraining |
|
|
|
|
NaN |
NaN |
|
NaN |
reported |
[src](https://github.com/marin-community/marin... |
| 48 |
marin-ablations |
exp845/846/847 cooldown ablations for markdown... |
ablation |
midtraining |
8.00e+09 |
|
|
|
NaN |
NaN |
|
NaN |
reported |
[src](https://github.com/marin-community/marin... |
| 49 |
marin-ablations |
exp620 INT8 training in Levanter |
ablation |
pretraining |
|
|
|
|
NaN |
NaN |
|
NaN |
reported |
[src](https://github.com/marin-community/marin... |
| 50 |
marin-ablations |
exp621 MuP for scaling laws |
ablation |
pretraining |
|
|
|
|
NaN |
NaN |
|
NaN |
reported |
[src](https://github.com/marin-community/marin... |
| 51 |
marin-ablations |
exp1565 batch size widens Muon vs AdamW gap |
ablation |
pretraining |
|
|
|
|
NaN |
NaN |
|
NaN |
reported |
[src](https://github.com/marin-community/marin... |
| 52 |
marin-ablations |
exp1572 Qwen3 (QK-Norm) speedruns incl. Muon |
ablation |
pretraining |
|
|
|
|
NaN |
NaN |
|
NaN |
reported |
[src](https://github.com/marin-community/marin... |
| 53 |
marin-ablations |
exp633 Compel compression-ratio quality filter... |
ablation |
pretraining |
1.40e+09 |
|
|
|
NaN |
NaN |
|
NaN |
reported |
[src](https://github.com/marin-community/marin... |
| 54 |
marin-ablations |
exp3124 OLMoE-M quantile-balancing sweep (40B ... |
ablation |
pretraining |
|
4.00e+10 |
|
|
NaN |
NaN |
|
NaN |
reported |
[src](https://github.com/marin-community/marin... |
| 55 |
marin-8b |
tootsie-scaling-512 (Dec 2024 ladder, 16L, 210... |
ladder |
pretraining |
2.49e+08 |
2.10e+11 |
3.13e+20 |
6ND derived |
NaN |
3.2518 |
|
NaN |
derived |
[src](https://wandb.ai/marin-community/marin/r... |
| 56 |
marin-8b |
tootsie-scaling-768 (Dec 2024 ladder, 16L, 210... |
ladder |
pretraining |
4.61e+08 |
2.10e+11 |
5.80e+20 |
6ND derived |
NaN |
3.0843 |
|
NaN |
derived |
[src](https://wandb.ai/marin-community/marin/r... |
| 57 |
marin-8b |
tootsie-scaling-1024 (Dec 2024 ladder, 16L, 21... |
ladder |
pretraining |
7.32e+08 |
2.10e+11 |
9.22e+20 |
6ND derived |
NaN |
2.9819 |
|
NaN |
derived |
[src](https://wandb.ai/marin-community/marin/r... |
| 58 |
marin-8b |
tootsie-scaling-1536 (Dec 2024 ladder, 16L, 21... |
ladder |
pretraining |
1.45e+09 |
2.10e+11 |
1.83e+21 |
6ND derived |
NaN |
2.8618 |
|
NaN |
derived |
[src](https://wandb.ai/marin-community/marin/r... |
| 59 |
marin-8b |
tootsie-scaling-2048 (Dec 2024 ladder, 16L, 21... |
ladder |
pretraining |
2.34e+09 |
2.10e+11 |
2.94e+21 |
6ND derived |
NaN |
2.7973 |
|
NaN |
derived |
[src](https://wandb.ai/marin-community/marin/r... |
Narrative
8B “Tootsie”. Llama-3.1-8B shape, 12.7T tokens, on two TPU v5e-256 slices and then a reserved v4-2048. Phases were named after the fact: Kestrel, Ocelot, Jellyfish (first cooldown), Phoenix (rewarm and data switch), Starling and Deeper Starling (second cooldown). Side runs that fed decisions: microanneals that settled the cooldown mix at 70/15/15, “dessert” patch runs, and two alternative cooldowns. Final 19-task average 66.6 against Llama 3.1 8B’s 65.3.
32B “Mantis”. Phase 1 (Llama-3-style, 80k steps) had persistent loss spikes that clipping softened but did not fix. Two rescues failed and were discarded. Phase 3 warm-started a Qwen3-32B backbone with QK-Norm from the 80k weights and the spikes disappeared. The first cooldown was discarded and rerun on the same tokens after the contamination and permutation bugs were found.
Scale-up by law (2026). Delphi, the MoE IsoFLOP law, the MuonH learning-rate law (R² 0.996 on a 150-run sweep), and the 535B ladder. Marin’s recipe document now codifies the sequence: tune at about 130M and 2.5B tokens, define scaling rules, run an IsoFLOP sweep, run a ladder, promote to a daily canary. Ideas for the MoE are screened at d512 to d1280 against the fitted law, with “effective speedup” computed by inverting the law and multiplying by measured throughput.
Not reconstructable from here. Delphi’s fitted exponent and the 535B ladder forecast (both in blocked pages or reports), the compute of the long tail of small ablations, any dollar figure (compute was donated by Google TRC and the Huang Foundation), and the reasons the 13B, 24B and 70B trials were abandoned (their W&B runs simply stop in April 2025 at 2.3T, 2.4T and 1.5T tokens).